


SURREALDB EARTH
Scaling out on Earth
SurrealDB Earth is serverless SurrealDB, running SurrealDS: object-storage native, multi-node, with parallelised query execution. It currently fans SELECT queries out as morsels for parallel execution, including counts, aggregation, filtering, indexed queries and streaming result sets. Scan throughput scales far beyond a single machine: over a billion rows per second, with a peak scan rate above ten billion.
3.1+ billion
Rows per second, best second
5 billion row scan fanned out across ~6,000 Earth Cells
18.9+ billion
Rows per second, peak scan rate
~120 byte rows, the current peak over a 100 ms window
300 GB/s
Sustained read throughput, best second
Data read from a single region
1.8 TB/s
Peak read throughput, one geographical location
Data read from a single region
1+ million
Concurrent active clients
Active querying clients, with 10+ million idle clients
100+ million
Point reads per second
1,000 point reads per transaction, across 10,000 transactions
These are today's numbers. We are still optimising Earth and scaling it further.
WHAT'S NEW IN 4.x
Headline gains from SurrealDB 3.x to 4.x
↑ 42%
Faster CRUD
Mean across creates, reads, updates, deletes
↑ 76%
Faster batches
Mean across batched operations
↑ 130%
Full-table scan performance
Mean across non-indexed read scans
↑ 2121%
Indexed query performance
Mean across indexed read scans, projected
↑ 81%
Faster CRUD tail latency
Mean p99 across creates, reads, updates, deletes
↑ 58%
Faster batch tail latency
Mean p99 across batched operations
↑ 23%
Faster indexed query tail latency
Mean p99 across indexed read scans, projected
WHAT'S NEW IN 3.x
Headline gains from SurrealDB 2.x to 3.x
↑ 31%
Faster CRUD
Mean across creates, reads, updates, deletes
↑ 58%
Faster batches
Mean across batched operations
↑ 11894%
Full-table scan performance
Mean across non-indexed read scans
↑ 136%
Indexed query performance
Mean across indexed read scans, projected
↑ 27%
Faster CRUD tail latency
Mean p99 across creates, reads, updates, deletes
↑ 32%
Faster batch tail latency
Mean p99 across batched operations
↑ 99%
Faster full-table scan tail latency
Mean p99 across non-indexed read scans
↑ 59%
Faster indexed query tail latency
Mean p99 across indexed read scans, projected
VERSION TO VERSION
SurrealDB across versions
Throughput improvements from SurrealDB 1.x through 4.x, summarised across the major workload classes. Higher is better.
CRUD throughput
Mean across creates, reads, updates, deletes
Batch throughput
Mean across batched CRUD operations
Full table scan throughput
Mean across non-indexed read scans
Indexed lookup throughput
Mean across indexed read scans
CROSS-DATABASE
Compare across database categories
SurrealDB benchmarked against the most-deployed database in each category - using the same workload, the same harness, the same hardware.
SurrealDB vs ArangoDB, MySQL, MongoDB, Neo4j, Postgres
Relational, document and graph workloads against the most-deployed engines: Postgres, MySQL, MongoDB, ArangoDB and Neo4j.
Engine: SurrealDB server
12%
slower
CRUD throughput
vs Postgres, mean across creates, reads, updates, deletes
39%
faster
Mean latency
vs Postgres, mean across CRUD operations
25%
faster
p99 latency
vs Postgres, mean across CRUD operations
47%
slower
Read throughput
vs Postgres, point reads by record id
1.8×
faster
Write throughput
vs Postgres, mean across creates, updates, deletes
44%
faster
Mean latency
vs Postgres, mean across creates, updates, deletes
33%
faster
p99 latency
vs Postgres, mean across creates, updates, deletes
CRUD operations
Single-record creates, reads, updates, and deletes against 5,000,000 records keyed by randomly-generated string IDs - never sequential, so engines cannot benefit from key locality. For SurrealDB, every operation runs inside its own snapshot-isolated, atomic transaction. The 128 clients each maintain 48 concurrent connections, and every operation is a single round-trip against a freshly-populated database.
Create
Throughput (higher is better)
ArangoDB 3.12
1.0k ops/s
MySQL 26.10
22.1k ops/s
MongoDB 9.0
129.9k ops/s
Neo4j 2026.04
42.1k ops/s
Postgres 18
82.8k ops/s
SurrealDB 4.0
143.1k ops/s
Read
Throughput (higher is better)
ArangoDB 3.12
255.9k ops/s
MySQL 26.10
205.5k ops/s
MongoDB 9.0
161.1k ops/s
Neo4j 2026.04
174.1k ops/s
Postgres 18
663.9k ops/s
SurrealDB 4.0
348.8k ops/s
Update
Throughput (higher is better)
ArangoDB 3.12
932 ops/s
MySQL 26.10
21.5k ops/s
MongoDB 9.0
123.2k ops/s
Neo4j 2026.04
50.3k ops/s
Postgres 18
79.8k ops/s
SurrealDB 4.0
130.5k ops/s
Delete
Throughput (higher is better)
ArangoDB 3.12
1.0k ops/s
MySQL 26.10
21.3k ops/s
MongoDB 9.0
141.5k ops/s
Neo4j 2026.04
44.1k ops/s
Postgres 18
83.2k ops/s
SurrealDB 4.0
173.7k ops/s
Batch operations
The same create / read / update / delete operations bundled into single requests of 100 and 1,000 rows. 250 batches are timed per operation per batch size, measuring how efficiently each engine commits a bulk of work in a single network round-trip and storage transaction.
Simple scans
Count and pagination operations without filters - the baseline scan performance.
First 100 rows
Throughput (higher is better)
ArangoDB 3.12
660 ops/s
MySQL 26.10
20.9k ops/s
MongoDB 9.0
62.1k ops/s
Neo4j 2026.04
19.0k ops/s
Postgres 18
81.4k ops/s
SurrealDB 4.0
49.5k ops/s
Offset pagination
Throughput (higher is better)
ArangoDB 3.12
622 ops/s
MySQL 26.10
10.7k ops/s
MongoDB 9.0
22.2k ops/s
Neo4j 2026.04
17.5k ops/s
Postgres 18
58.6k ops/s
SurrealDB 4.0
25.6k ops/s
Table scans and indexed queries
Range and predicate queries across non-indexed full table scans and indexed acceleration, each read-only and with writes mixed in, followed by full-table counts and BM25 full-text search. SurrealDB's indexed query figures are projected.
Read and mixed-workload queries
Filtered select(*) queries, each run read-only and with 15% writes mixed in.
Full-table counts
The same filters answered with count(*).
Full-text search
BM25 ranked search over an indexed text field.
Detailed comparison
Explore every operation interactively. Pick the databases to compare, then read the heatmap to spot where each engine wins or falls behind, chart a single operation head-to-head, or read the raw table. Switch the metric above to view throughput, mean latency, or p99. SurrealDB's indexed query figures are projected.
METHODOLOGY
How these benchmarks are run
All results are produced by the open-source crud-bench harness running against a fresh instance of each database on the same hardware.
Workload
5,000,000 records per test
1,000,000 for the embedded category, where SQLite is otherwise prohibitively slow.
128 clients, 48 concurrent queries each
Mixed read/write scans at 15% and 50% write ratios
Run separately, so each ratio is measured on its own.
Every row blends the data types
Strings, integers, floats, enums, UUIDs, datetimes, booleans, a nested geography object, and arrays of tag enums.
Batch operations at 100 and 1,000 rows per batch
Same harness for every engine
The same dataset shape and the same logical operations
Run against every engine.
Queries translated to each engine's native dialect
SQL variants, MongoDB filter documents, Cypher fragments, SurrealQL - so no engine is penalised for not speaking another's language.
Every WHERE-based scan runs with and without a matching index
Raw scan cost and index acceleration are reported separately. ArangoDB has no indexed results (shown as N/A): crud-bench's ArangoDB adapter does not yet create indexes, so it is only benchmarked on full table scans (crud-bench#261).
Mixed read/write scans interleave UPDATEs
At 15% and 50% write ratios, so sustained throughput is measured rather than pure-read performance.
Full-text BM25 queries on every engine that supports them
Single term, multi-AND and multi-OR, in the engine's idiomatic fulltext syntax.
System isolation
Every benchmark runs on bare metal
No virtualisation, no hypervisor overhead.
Each benchmark waits for a quiet machine
It starts once the 1-minute load average drops below 0.5.
Background services stopped, swap disabled, Transparent Huge Pages off
unattended-upgrades is the service that goes.
Disk caches dropped and memory compacted before and after every run
No database inherits a warmed cache from the previous one.
Process limits raised
65,536 file descriptors, unlimited processes, unlimited memory lock.
Priority and affinity pinned
Process priority with nice / ionice; CPU affinity with taskset.
Each database runs alone on the machine
Between runs the data directory is wiped and the Docker volume is recreated, so every database starts from an identical, empty state.
crud-bench compiled for release
cargo build --release, so harness overhead is minimised.
Durability & disk sync
Every persistent benchmark runs in full durability mode
Each committed transaction is flushed and fsync'd to disk before it is acknowledged, matching how these engines should be configured in production.
Every engine on its standard production-durable settings
SQLite, Postgres, MySQL, MongoDB, ArangoDB, Neo4j and SurrealDB all run this way, so no engine gains an advantage by skipping disk sync.
The common settings used to enforce this
fsync = on and synchronous_commit = on for Postgres; innodb_flush_log_at_trx_commit = 1 and sync_binlog = 1 for MySQL; and journaled write concern { j: true } for MongoDB.
SurrealDB runs with disk sync enabled
SurrealDB 2.x did not enable sync by default, whereas SurrealDB 3.x enables it by default - so the 3.x numbers reflect the same full-durability guarantee as the other engines.
What we capture
The full latency distribution per operation
min, p01, p25, p50, p75, p95, p99, max and IQR - so tail-latency regressions cannot hide behind a clean mean.
Resource accounting per benchmark
CPU avg/min/max, memory avg/min/max, disk read/write bytes, and system load.
All raw JSON output preserved and shipped with the page
A reader can re-derive every chart from the source numbers.
Hardware
Same single-node machine used across every comparison (last run 3 November 2026).
| Component | Specification |
|---|---|
| CPU | AMD Ryzen Threadripper 9970X (32 cores / 64 threads, x86_64) |
| RAM | 2 × Samsung DDR5 4800MHz 64GB RDIMM (128 GiB total) |
| SSD | Lexar EQ790 4TB NVMe |
| Motherboard | ASUS PRO WS TRX50-SAGE WIFI A |
| CPU cooler | Arctic Freezer 4U-M |
| Power supply | CORSAIR RM1000x |
| GPU | PowerColor AMD Radeon RX 7600 Fighter 8GB |
| Case | In-Win IW-R400-01N 4U |
| OS | Ubuntu 24.04 (kernel 6.8.0-111-generic) |
Caveats & reproducibility
All writes are fully durable (see Durability & disk sync above).
ArangoDB is not benchmarked with indexes, so its indexed-query results are N/A rather than a failure; see crud-bench#261.
SurrealDB's indexed query figures are projections: the measured throughput scaled by 1.63 (1.69 for the OR of two equalities), with latencies scaled to match. Every other figure is the measured result.
Embedded engines (SQLite, embedded SurrealDB) run in-process; networked engines (Postgres, MySQL, MongoDB, ArangoDB, Neo4j, networked SurrealDB) run in Docker over localhost TCP. Categories should be compared independently.
crud-bench is open source and the full workload spec lives in bench.toml. Any reader can run ./run.sh -d <db> on their own hardware to reproduce a comparison.
ON THE ROADMAP
More comparisons, on their way. The workloads and engines this page adds next.
Distributed database comparisons
Clustered configurations of CockroachDB, TiDB, MongoDB and Aerospike running the same workload across multiple nodes.
Vector search
HNSW vector similarity across the multi-model engines, with throughput and recall at varying index parameters.
Graph queries
Multi-hop graph traversal workloads against Neo4j and ArangoDB on the same dataset.
TPC-C
The standard TPC-C transactional workload, reported as transactions per minute (tpmC).
THE PLATFORM
Everything an application and its agents know. Five surfaces, one engine.
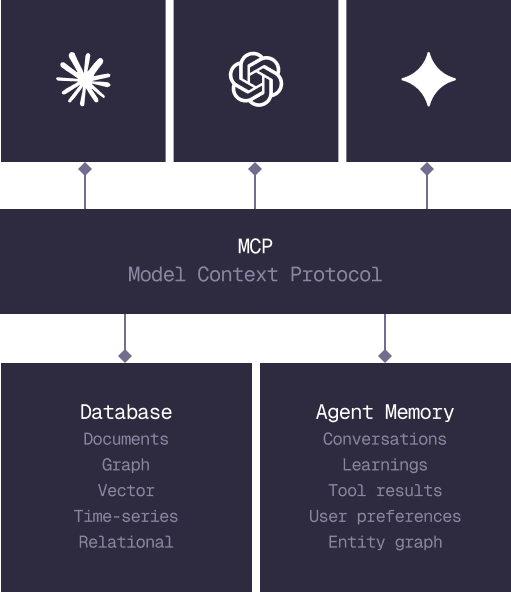
Database
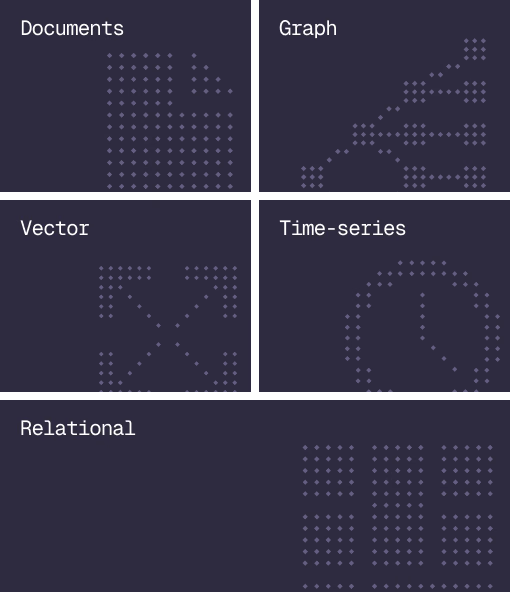
Document, graph, vector, time-series and relational in one engine.
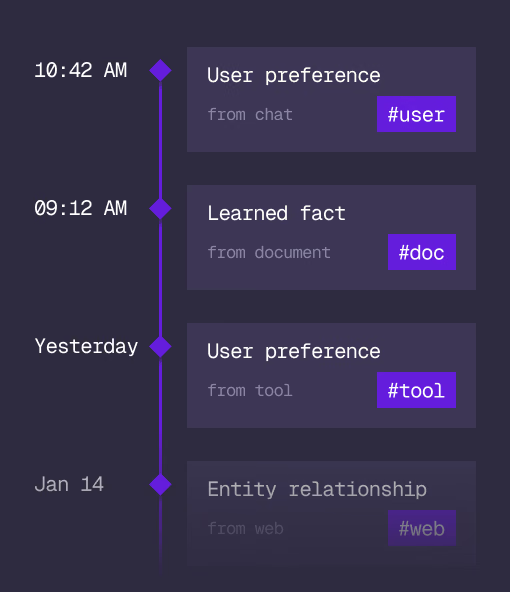
Agent Memory
What an agent learns, with its source and its time, in the same engine.
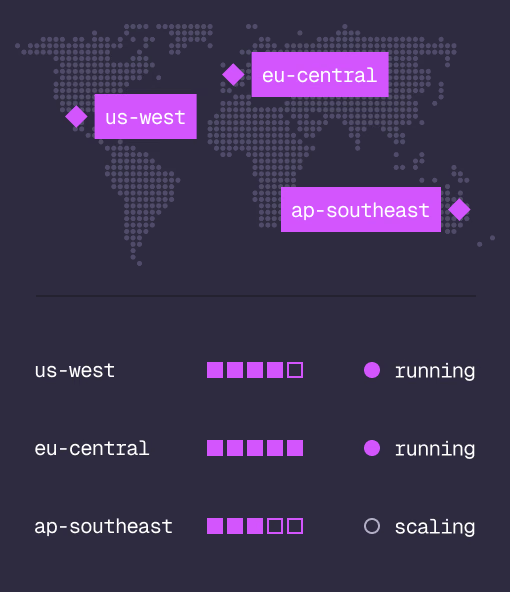
Cloud
Dedicated clusters by region, or serverless on SurrealDB Earth.
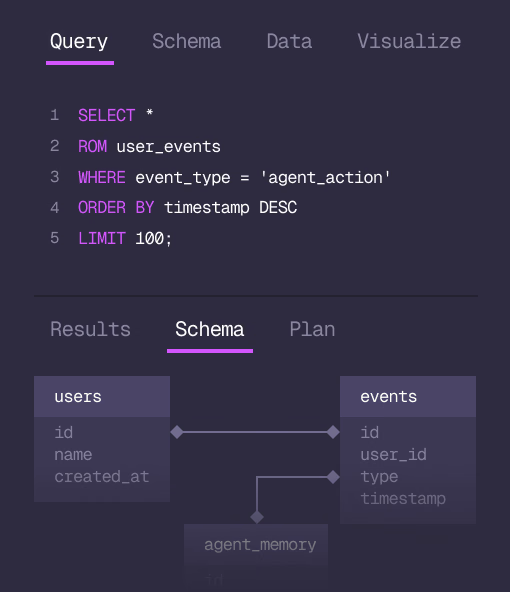
Studio
Query, explore and design the schema from the browser.
MCP
Every model that speaks MCP reaches the database and the memory directly.
IN PRODUCTION
Trusted at scale. Samsung, Nvidia, Verizon, Tencent, and Walmart run on SurrealDB.
14,000+
Developers building on SurrealDB Cloud
4M+
Developers building on SurrealDB worldwide
FROM THE TEAMS
SurrealDB gives us a foundation where we can unify semantic search, knowledge graphs, and AI-driven decision making without stitching together multiple systems. Collapsing responsibility into SurrealDB has become our default engineering posture.
VP of Engineering, Later
GET STARTED