


SURREALQL
One query, every model. Filters, a graph walk and hybrid ranking in one statement, on one snapshot.
Hybrid query in one statement
One statement: tenant and time filters, a graph walk, and hybrid vector and full-text ranking. One transaction, one snapshot.
Try SurrealQL in StudioIndexes built for each model
HNSW for vectors, BM25 for full-text, B-trees for lookups and the key layout itself for graph traversal. Execution streams, so a traversal feeds a vector ranking with nothing materialised between them.
Relationships are records
An edge is a full document with its own fields and permissions. Arrow syntax walks it in either direction, filtering as it goes.
A result set that keeps arriving
Add LIVE to a SELECT and every matching change streams to the client as it commits. DIFF sends only the change; KILL ends the stream.
DATA MODELS
Composable by design. Every model is a native primitive, and any statement can combine them: a graph walk scoped by a full-text match, ranked by vector distance and streamed live.
Documents
Schemaless or schemafull records. Record links replace foreign-key joins with references the engine resolves at query time.
Graphs
Edges made with RELATE and walked with arrow syntax. Every edge is a full document with its own fields and permissions.
Vectors
HNSW indexes queried with distance functions. A structured filter narrows the candidates before the search runs.
Time-series
Native duration arithmetic, temporal aggregation and point-in-time VERSION reads without blocking writers, on a versioned storage engine (experimental).
Full-text search
BM25-scored indexes with configurable analysers and the @@ match operator, composed with every other model.
Live queries
LIVE SELECT streams changes over WebSockets. DEFINE EVENT runs logic on writes. Changefeeds keep an ordered log per table.
CAPABILITIES
Beyond the core models. Geospatial, WebAssembly extensions, custom endpoints and a single binary that runs anywhere.
Geospatial
Native GeoJSON types with distance, bearing, area and containment functions, composed with the graph in one statement.
Extensions
WebAssembly modules written in Rust, loaded into a running database and callable from SurrealQL inside the transaction.
DEFINE API
HTTP endpoints defined inside the database, with its transactions, permissions and every model behind them.
Single binary
The same engine in the browser as WebAssembly, embedded at the edge, as a server or as a cluster on object storage.
Your questions,answered
It is one engine, so the models share a key-value substrate, a query planner and a transaction coordinator. Adding a graph traversal to a vector query costs one more step, in the same plan, against the same snapshot. A single-model database wins its own discipline in isolation. Production queries are rarely in isolation: they scope, traverse, rank and commit at once, and the round trips between separate systems cost more than the per-model difference saves.
THE PLATFORM
Everything an application and its agents know. Five surfaces, one engine.
Database
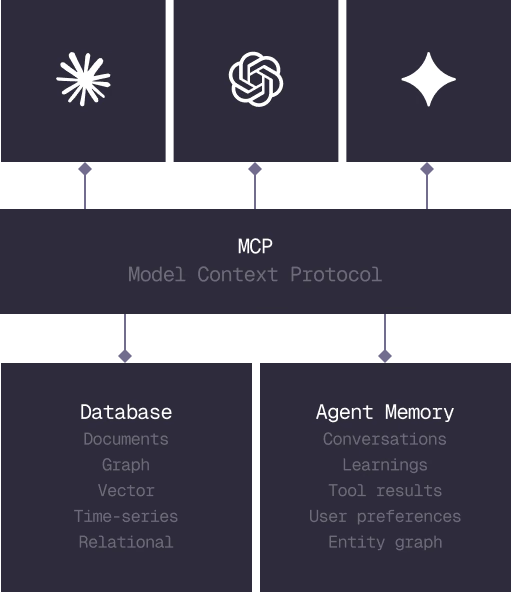
Document, graph, vector, time-series and relational in one engine.
Agent Memory
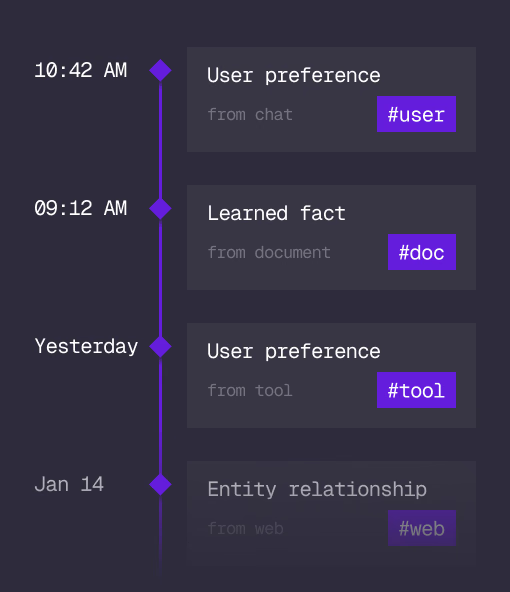
What an agent learns, with its source and its time, in the same engine.
Cloud
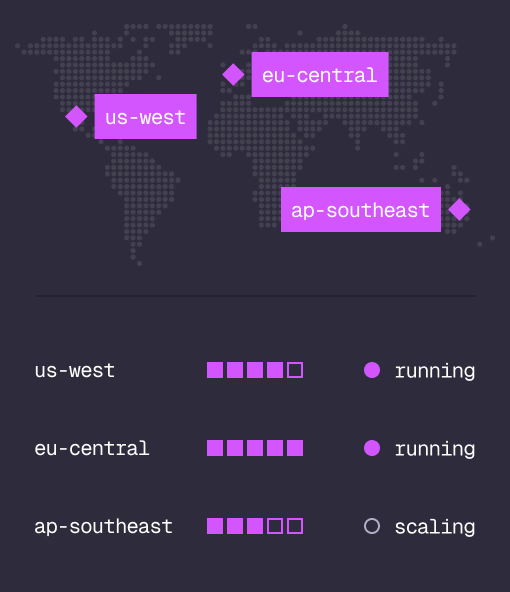
Managed clusters in the regions you choose, scaled on demand.
Studio
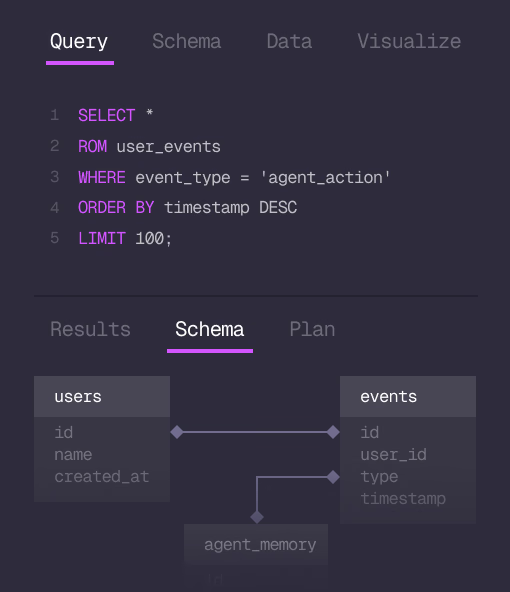
Query, explore and design the schema from the browser.
MCP
Every model that speaks MCP reaches the database and the memory directly.
IN PRODUCTION
Trusted at scale. Samsung, Nvidia, Verizon, Tencent and Walmart run on SurrealDB.
14,000+
Developers building on SurrealDB Cloud
4M+
Developers building on SurrealDB worldwide
FROM THE TEAMS
SurrealDB gives us a foundation where we can unify semantic search, knowledge graphs, and AI-driven decision making without stitching together multiple systems. Collapsing responsibility into SurrealDB has become our default engineering posture.
VP of Engineering, Later
GET STARTED