Multi-model RAG with SurrealDB & Langchain
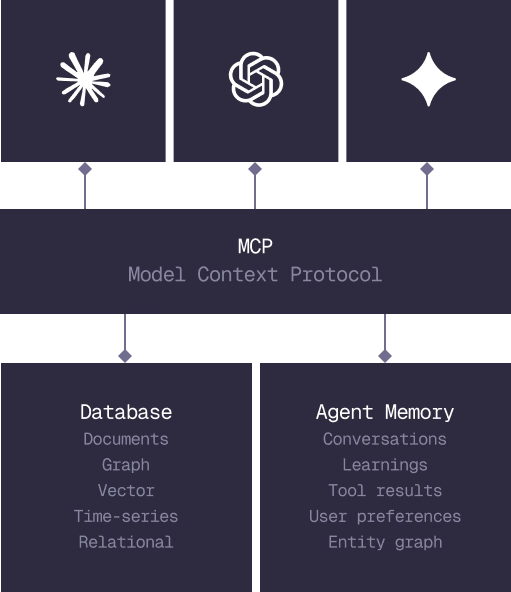
Learn how to build a multi-model RAG pipeline with SurrealDB & Langchain. We'll cover how to use SurrealDB & Langchain to build a multi-model RAG pipeline.
In the rapidly evolving field of AI, most of the time is spent optimising. You are either maximising your accuracy, or minimising your latency. Join our live SurrealDB webinar where we'll be showing some LangChain components, testing some prompt engineering tricks, and identifying specific use-case challenges.
We’ll walk through an experiment: a chatbot answering questions over chat-style conversations, showing when vector retrieval wins, when lightweight graphs help, and how to handle tricky bits like time awareness.
In this session you'll learn
- Set up SurrealDB as both a graph and vector store - one connection, one system
- Use LangChain to ingest documents
- Use LLMs to infer keywords
- Tune retrieval (k, thresholds) and compare vector-only, graph-only, and intersected results