The DEFINE TABLE statement allows you to declare your table by name, enabling you to apply strict controls to a table's schema by making it SCHEMAFULL, create a foreign table view, and set permissions specifying what operations can be performed on the table.
The fields of a table are not defined using DEFINE TABLE, but via individual DEFINE FIELD statements.
Requirements
You must be authenticated as a root owner or editor, namespace owner or editor, or database owner or editor before you can use the
DEFINE TABLEstatement.You must select your namespace and database before you can use the
DEFINE TABLEstatement.
Statement syntax
DEFINE TABLE [ OVERWRITE | IF NOT EXISTS ] @name
	[ DROP ]
	[ SCHEMAFULL | SCHEMALESS ]
	[ TYPE [ ANY | NORMAL | RELATION
		[ [ IN | FROM ] @table ] [ [ OUT | TO ] @table ]
		[ ENFORCED ] [ LIGHTWEIGHT ]]]
	[ AS SELECT @projections
		FROM @tables
		[ WHERE @condition ]
		[ GROUP [ BY @groups | ALL ] ]
	]
	[ CHANGEFEED @duration [ INCLUDE ORIGINAL ] ]
	[ INLINE EDGES @number ]
	[ INLINE REFERENCES @number ]
	[ PERMISSIONS [ NONE | FULL
		| FOR select @expression
		| FOR create @expression
		| FOR update @expression
		| FOR delete @expression
	] ]
    [ COMMENT @string ]
	[ GRAPHQL_ALIAS @string ]
	[ GRAPHQL_DEPRECATED @string ]
Each clause can be given once. From SurrealDB 4.0, a statement that repeats a clause, such as two PERMISSIONS clauses, or both SCHEMAFULL and SCHEMALESS, is a parse error that names both clauses: Conflicting clause on this table definition. Earlier versions kept the last of the repeated clauses.
Example usage
Below shows how you can create a table using the DEFINE TABLE statement.
-- Declare the name of a table.
DEFINE TABLE reading;
Comments
Add a COMMENT when the table's role is not obvious from the name alone. The text is returned by INFO and by agent-facing schema tools, so prefer operational detail (record-ID conventions, graph paths, invariants) over a one-line restatement of the table name. See Comments on definitions for a fuller pattern.
DEFINE TABLE person TYPE NORMAL SCHEMAFULL
	COMMENT "Deduplicated person. The record id is the canonical full name (person:`Alice Chen`); use record::id(id) to read it. Edges: person->attended->meeting.";
The following example uses the DROP portion of the DEFINE TABLE statement. Marking a table as DROP disallows creating or updating records.
DROP tables are useful in combination with events or foreign (view) tables, as you can compute a record and essentially drop the input.
-- By marking a table as DROP, you disallow any records to be created or updated.
-- Records that currently exist in the table will not automatically be deleted, you can still remove them manually.
DEFINE TABLE reading DROP;
The following expression shows how you can define a CHANGEFEED for a table. After creating, updating, and deleting records in the table as usual, using SHOW CHANGES FOR will show the changes that have taken place during this time.
If an entry holds a change to an existing record, the diff will show the operation needed to modify the record to the state immediately preceding its current state. In other words, the diff included is a reverse diff.
-- Define the changefeed and its duration
-- Optionally, append INCLUDE ORIGINAL to include info
-- on the current record before a change took place
DEFINE TABLE reading CHANGEFEED 3d;

-- Create some records in the reading table
CREATE reading SET story = "Once upon a time";
CREATE reading SET story = "there was a database";
UPDATE reading SET is_interesting = true;

-- Replay changes to the reading table since a certain date
-- Must be after the timestamp at which the changefeed began
SHOW CHANGES FOR TABLE reading SINCE d"2025-09-07T01:23:52Z" LIMIT 10;

-- Alternatively, show the changes for the table since a version number
SHOW CHANGES FOR TABLE reading SINCE 0 LIMIT 10;[
{
changes: [
{
define_table: {
changefeed: {
expiry: 3d,
original: false
},
drop: false,
id: 0,
kind: {
kind: 'ANY'
},
name: 'reading',
permissions: {
create: false,
delete: false,
select: false,
update: false
},
schemafull: false
}
}
],
versionstamp: 116395447100768256
},
{
changes: [
{
update: {
id: reading:bqlejs8fx4phgbo6g5ve,
story: 'Once upon a time'
}
}
],
versionstamp: 116395447100833792
},
{
changes: [
{
update: {
id: reading:fa8o65ccxykfxqqz91yo,
story: 'there was a database'
}
}
],
versionstamp: 116395447100833793
},
{
changes: [
{
update: {
id: reading:bqlejs8fx4phgbo6g5ve,
is_interesting: true,
story: 'Once upon a time'
}
},
{
update: {
id: reading:fa8o65ccxykfxqqz91yo,
is_interesting: true,
story: 'there was a database'
}
}
],
versionstamp: 116395447100833794
}
][
{
changes: [
{
define_table: {
changefeed: {
expiry: 3d,
original: true
},
drop: false,
id: 0,
kind: {
kind: 'ANY'
},
name: 'reading',
permissions: {
create: false,
delete: false,
select: false,
update: false
},
schemafull: false
}
}
],
versionstamp: 116395448975818752
},
{
changes: [
{
update: {
id: reading:kypj876yubk4fnnja93b,
story: 'Once upon a time'
}
}
],
versionstamp: 116395448975818753
},
{
changes: [
{
update: {
id: reading:0i2qwoi053nmrl4k2wm2,
story: 'there was a database'
}
}
],
versionstamp: 116395448975818754
},
{
changes: [
{
current: {
id: reading:0i2qwoi053nmrl4k2wm2,
is_interesting: true,
story: 'there was a database'
},
update: [
{
op: 'remove',
path: '/is_interesting'
}
]
},
{
current: {
id: reading:kypj876yubk4fnnja93b,
is_interesting: true,
story: 'Once upon a time'
},
update: [
{
op: 'remove',
path: '/is_interesting'
}
]
}
],
versionstamp: 116395448975818755
}
]Schemafull tables
The following example demonstrates the SCHEMAFULL portion of the DEFINE TABLE statement. When a table is defined as schemafull, the database strictly enforces any schema definitions that are specified using the DEFINE TABLE statement. New fields can not be added to a SCHEMAFULL table unless they are defined via the DEFINE FIELD statement.
Schemafull tables are implicitly type NORMAL tables by default.
-- Create schemafull user table.
DEFINE TABLE user SCHEMAFULL;

-- Define some fields.
DEFINE FIELD firstName ON TABLE user TYPE string;
DEFINE FIELD lastName ON TABLE user TYPE string;
DEFINE FIELD email ON TABLE user TYPE string
  ASSERT string::is_email($value);
DEFINE INDEX userEmailIndex ON TABLE user FIELDS email UNIQUE;

-- SEE IT IN ACTION
-- 1: Try to add a user with an undefined field, 'photoURI'.
CREATE user CONTENT {
    firstName: 'Tobie',
    lastName: 'Hitchcock',
    email: 'Tobie.Hitchcock@surrealdb.com',
    photoURI: 'photo/yxCFi22Jw2.webp'
};
-- 2: The statement fails: a schemafull table rejects any field that has
--    not been defined. (Before version 3.0, the undefined field was
--    silently dropped instead.)

-- 3: Create the user with defined fields only.
CREATE user CONTENT {
    firstName: 'Tobie',
    lastName: 'Hitchcock',
    email: 'Tobie.Hitchcock@surrealdb.com'
};

-- 4: Query the data
SELECT * FROM user;
Schemaless tables
The following example demonstrates the SCHEMALESS portion of the DEFINE TABLE statement. This allows you to explicitly state that the specified table has no schema.
-- Create schemaless user table.
DEFINE TABLE user SCHEMALESS;

-- Define some fields.
DEFINE FIELD firstName ON TABLE user TYPE string;
DEFINE FIELD lastName ON TABLE user TYPE string;
DEFINE FIELD email ON TABLE user TYPE string
  ASSERT string::is_email($value);
DEFINE INDEX userEmailIndex ON TABLE user FIELDS email UNIQUE;

-- SEE IT IN ACTION - Example 1
-- 1: Add a user with all required fields and an undefined one.
CREATE user:tobie SET firstName = 'Tobie', lastName = 'Hitchcock',
  email = 'Tobie.Hitchcock@surrealdb.com',
  photoURI = 'photo/yxCFi22Jw2.webp';
-- 2: Statement will succeed because user is a SCHEMALESS table.

-- SEE IT IN ACTION - Example 2
-- 1: Add a user with an invalid email address and include a new field that was never defined.
CREATE user:jaime SET firstName = 'Jamie', lastName = 'Hitchcock',
  email = 'Jamie.Hitchcock',
  photoURI = 'photo/yxCFi22Jw2.webp';
-- 2: Statement will fail because the value for email was not valid.
Interaction between fields
While a DEFINE TABLE statement represents a template for any subsequent records to be created, a DEFINE FIELD statement pertains to concrete field data of a record. As such, a DEFINE FIELD statement gives access to the record's other fields through their names, as well as the current field through the $value parameter.
DEFINE TABLE person SCHEMAFULL;

DEFINE FIELD first_name
  ON TABLE person TYPE string ASSERT string::len($value) < 20;
DEFINE FIELD last_name
  ON TABLE person TYPE string ASSERT string::len($value) < 20;
DEFINE FIELD name
  ON TABLE person             VALUE first_name + ' ' + last_name;

-- Creates a `person` with the name "Bob Bobson"
CREATE person SET first_name = "Bob", last_name = "Bobson";
Pre-computed table views
In SurrealDB, like in other databases, you can create views. The way you create views is using the DEFINE TABLE statement like you would for any other table, then adding the AS clause at the end with your SELECT query.
DEFINE TABLE review DROP;
-- Define a table as a view which aggregates data from the review table
DEFINE TABLE avg_product_review TYPE NORMAL AS
SELECT
	count() AS number_of_reviews,
	math::mean(<float> rating) AS avg_review,
	->product.id AS product_id,
	->product.name AS product_name
FROM review
GROUP BY product_id, product_name;

-- Query the projection
SELECT * FROM avg_product_review;
Pre-computed table views differ from a typical relational database view in a few important ways, and have a few limitations to keep in mind.
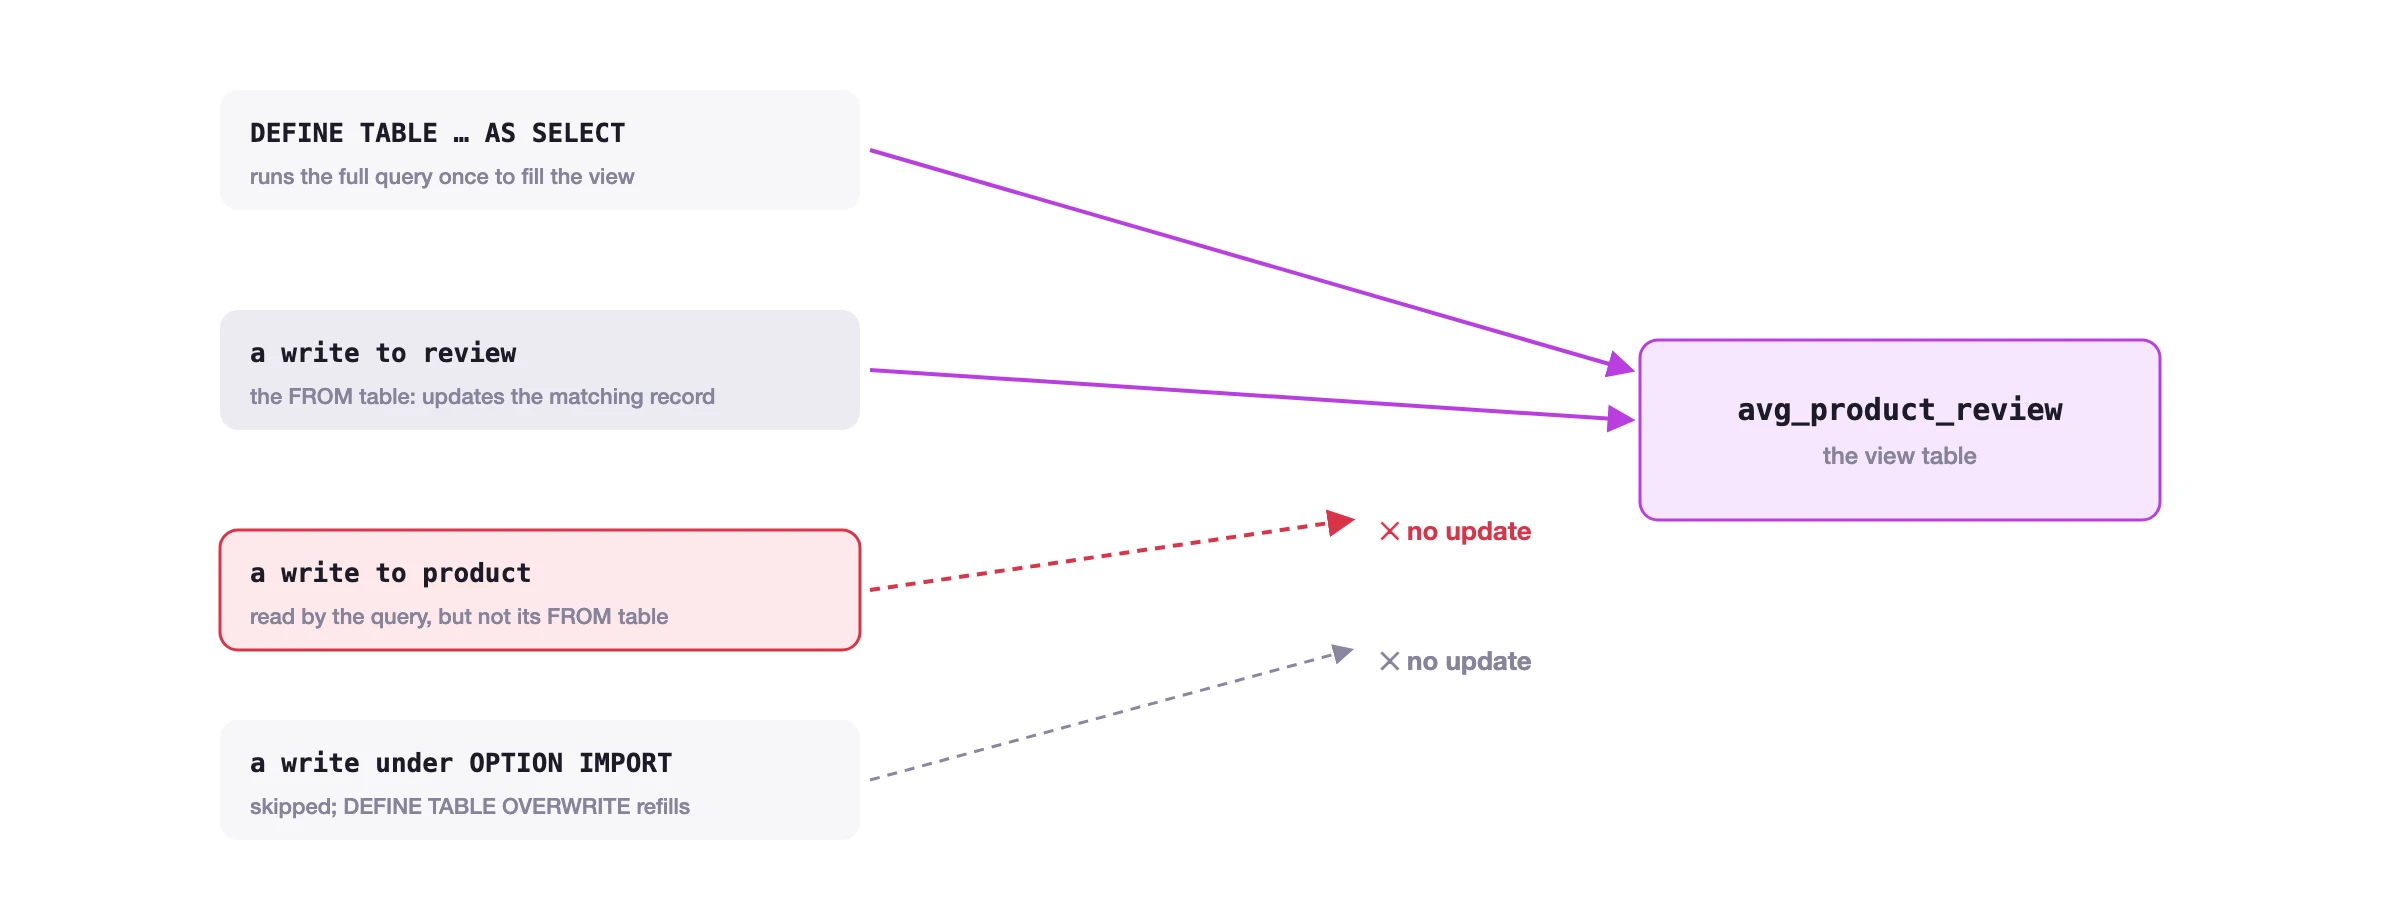
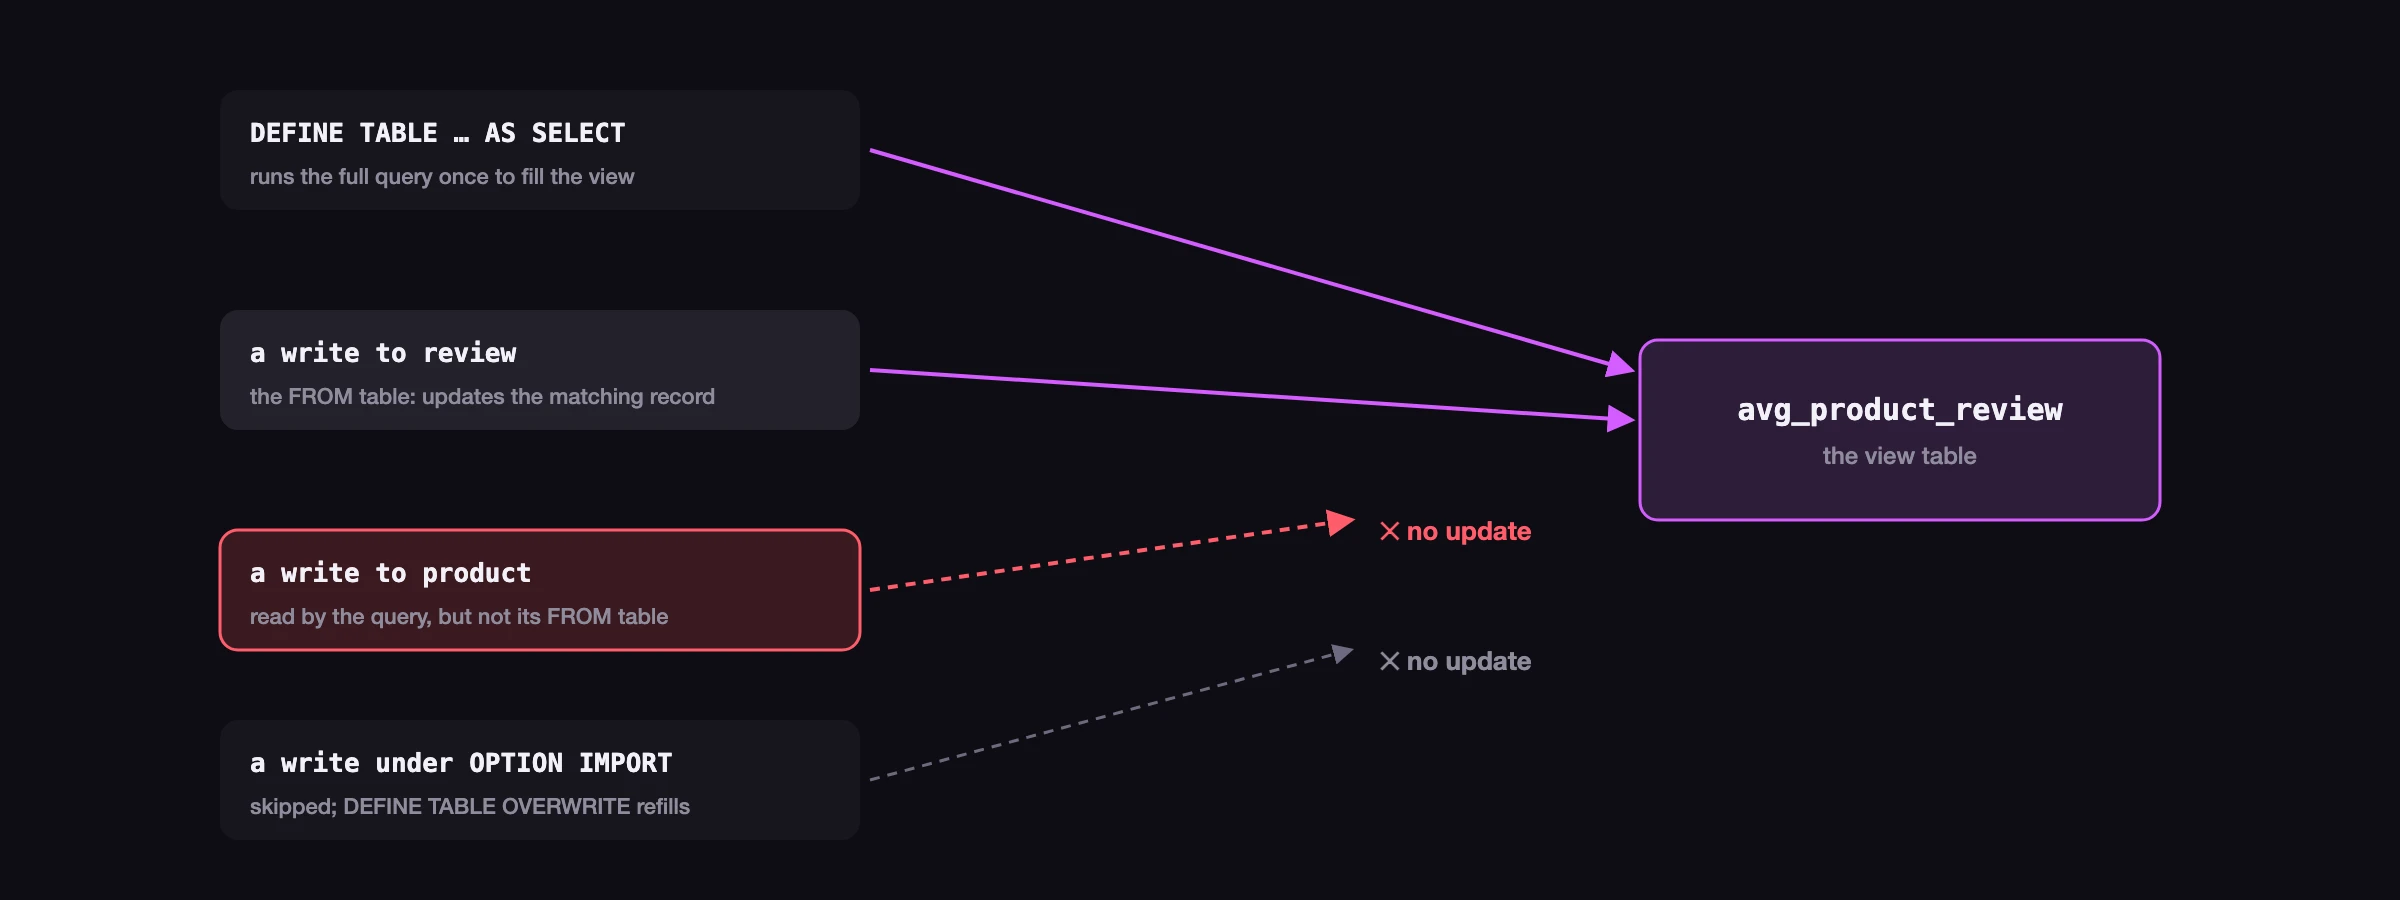
Pre-computed table views are most similar to event-based, incrementally updating, materialised views:
Event-based, meaning that when you add or remove data from the underlying table (in our example, the
reviewtable), it triggers a matching event on theavg_product_reviewtable view.Materialised view, meaning that the first time we run the table view query, it will run the query like a normal
SELECTstatement, but then materialise the result. Normal views, by contrast, behave like bookmarkedSELECTqueries that only look like tables to the user.Incrementally updating, meaning that for any subsequent run, it will listen for the event trigger and perform the most efficient operation possible to always keep the result up to date, instead of just running the
SELECTstatement again.
While this functionality can be replicated in many other databases, it is usually only done by expert users as it can be very complicated to set up and maintain. Pre-computed table views make this functionality available through a single DEFINE TABLE statement.
As mentioned though, there are a few limitations to keep in mind.
First, while subsequent runs are very efficient, the initial run of large analytical queries can be slow and use a lot of resources, because it is a normal
SELECTstatement. Therefore indexing and query optimisation are still very important.Second, while both graph relations and record links are supported, the table view update event is only triggered by the table in the
FROMclause. In our case, that is thereviewtable, not theproducttable that the query also uses. This means that if you delete areviewtheavg_product_reviewwill reflect that in near real-time. However if you delete aproduct, it will still show up inavg_product_review.Third, view tables are read-only. Since 3.2.0,
CREATE,INSERT,UPSERT,UPDATE,DELETE, andRELATEagainst a view table are rejected - records are computed from the source query only. The one exception is import: records emitted for a view during export can be re-applied underOPTION IMPORT, to allow export → import round-trips to keep working.
Filling a view from existing records
Defining a view runs its query over the records already in the source table, so the view starts with their results rather than empty. After that, only writes to the source table update it.
A view defined with GROUP ALL has its one record from the moment it is defined, also when the source table is empty, with the aggregates of no records: count() is 0. Deleting the last source record resets that record to the same values instead of deleting it. An event defined on such a view therefore receives UPDATE in $event for every change, and never CREATE or DELETE.
DEFINE TABLE sale;
DEFINE TABLE sales_total AS
	SELECT count() AS sales, math::sum(amount) AS total
	FROM sale GROUP ALL;
SELECT * FROM sales_total;[
{
id: sales_total:[],
sales: 0,
total: 0
}
]Writes made under OPTION IMPORT, which is how surreal db import loads data, do not trigger the view. To bring a view up to date after an import, define it again with OVERWRITE, which runs the query over every record in the source table:
CREATE news:1 SET tags = ["fr"];
DEFINE TABLE fr_feed AS SELECT * FROM news WHERE "fr" IN tags;

-- An import skips the view, so news:2 does not appear in fr_feed
OPTION IMPORT;
CREATE news:2 SET tags = ["fr"];
-- In a later query, rebuild the view from all of the news records
DEFINE TABLE OVERWRITE fr_feed AS SELECT * FROM news WHERE "fr" IN tags;
SELECT VALUE id FROM fr_feed;[fr_feed:1, fr_feed:2] Choosing the id of a view row
Each row of a view is keyed by the record it came from, or for a grouped view, by its group. A projection that sets id keys the rows by that value instead, which lets several source records feed one row, or gives a row a key that is meaningful on its own:
CREATE purchase:1 SET customer = 'ana', total = 10;
DEFINE TABLE spend AS SELECT customer AS id, total FROM purchase;

CREATE purchase:2 SET customer = 'ben', total = 25;
UPDATE purchase:1 SET total = 15;

SELECT * FROM spend;[
{ id: spend:ana, total: 15 },
{ id: spend:ben, total: 25 }
]The value becomes the key of the view row, so it can be a string, number, array, object or UUID. A write whose projected id changes moves the row to the new key, and a projected id of NONE fails the write.
Before SurrealDB 4.0, only the initial fill used the projected id. Later writes keyed the row by the source record, so the same query left spend:ana at 10 beside rows keyed spend:1 and spend:2, and an id that was not a record id failed the definition.
Defining permissions
Table PERMISSIONS control what record users (and guests, when guest access is enabled) may do with records in that table. They do not restrict system users at the root, namespace, or database level, as those users are governed by roles instead.
If you omit the clause, SurrealDB stores PERMISSIONS NONE. That denies SELECT, CREATE, UPDATE, and DELETE for record users until you grant access explicitly. The opposite shorthand is PERMISSIONS FULL, which allows all four operations.
CREATE some_table;
DEFINE TABLE some_other_table;

INFO FOR DB;{
accesses: {},
analyzers: {},
apis: {},
buckets: {},
configs: {},
functions: {},
models: {},
modules: {},
params: {},
sequences: {},
tables: {
some_other_table: 'DEFINE TABLE some_other_table TYPE ANY SCHEMALESS PERMISSIONS NONE',
some_table: 'DEFINE TABLE some_table TYPE ANY SCHEMALESS PERMISSIONS NONE'
},
users: {}
}You can also set independent rules for selecting, creating, updating, and deleting data. Each FOR clause is a SurrealQL expression, usually one that compares the record with $auth.
-- Specify access permissions for the 'post' table
DEFINE TABLE post SCHEMALESS
	PERMISSIONS
		FOR select
			-- Published posts can be selected
			WHERE published = true
			-- A user can select all their own posts
			OR user = $auth.id
		FOR create, update
			-- A user can create or update their own posts
			WHERE user = $auth.id
		FOR delete
			-- A user can delete their own posts
			WHERE user = $auth.id
			-- Or an admin can delete any posts
			OR $auth.admin = true
;
A table or field PERMISSIONS clause reads data with the authority of the schema that defines it, not with the caller's permissions. $auth and the record being checked are the caller's, but any other record the clause reads is read without checking the caller's permissions. This applies to following a record id such as $auth.admin, a subquery, record::exists() or .exists(), a graph traversal, and a function that the clause calls. So a clause can test fields of the user's own record even when the user may not select it. A field's VALUE, DEFAULT, ASSERT and COMPUTED clauses, and a function called from a query, run with the caller's permissions instead.
In SurrealDB 3.3, record::exists() and .exists() inside a FOR select clause were checked against the caller's permissions, so they returned false for a record the caller could not select, and the clause denied access. From SurrealDB 4.0 they read the record in the same way as the other forms.
Each write is checked only against its own clause: FOR create, FOR update or FOR delete. If that clause allows it, the record is written. The statement's result is then filtered by FOR select, so a record user who may create records in a table but not select them receives [], although the record was written. In the same way, UPDATE and DELETE with a WHERE clause can match records that the caller cannot select. To return a user's own writes to them, add a narrow select rule such as FOR select WHERE owner = $auth.
-- Defined by a system user: record users may create notes, but not select them
DEFINE TABLE note PERMISSIONS FOR create WHERE owner = $auth;

-- Run as a record user: the first note is written, the second is refused
CREATE note SET owner = $auth, text = 'Draft';
//- []

CREATE note SET owner = person:someone_else, text = 'Draft';
//- [] A write that its permission clause refuses does not raise an error. The statement returns [] with status OK (CREATE ONLY returns NONE), and the other statements in the transaction still commit. This result is the same as for a write that succeeded but that FOR select hides, and RETURN NONE gives the same result for both.
Field permissions work the same way but default to PERMISSIONS FULL instead of NONE. This is because the table is the main access gate, while field permissions only narrow further when you need to (for example hiding a password). With FULL, a field follows the table's rules without adding its own. See DEFINE FIELD and Permissions & row-level security.
Writes inside a permission clause
A permission clause decides whether an operation is allowed, and must not write data itself, whether directly or through a custom function. This applies to every clause, FOR create, FOR update and FOR delete included. The definition is refused:
DEFINE FUNCTION fn::audit($id: record) -> bool { CREATE audit SET record = $id, at = time::now(); RETURN true; };

DEFINE TABLE post PERMISSIONS
FOR create, update WHERE fn::audit($value.id) AND user = $auth.id;'The PERMISSIONS clause must not have effects: it calls `fn::audit`, in whose body `CREATE` writes data'Use DEFINE EVENT for a write that should follow a change, such as an audit log. An event runs without permission checks, so it can write to a table such as audit that the caller cannot access. It also states the side effect where a reader expects to find it, and does not run on every access check:
DEFINE TABLE post PERMISSIONS FOR create, update WHERE user = $auth.id;

DEFINE EVENT audit ON post WHEN $event IN ['CREATE', 'UPDATE'] THEN {
	CREATE audit SET record = $after.id, at = time::now();
};
The full list of what a clause may not do is in Clauses that must not have effects.
This behaviour changed in 4.0. In 3.3, a FOR create, FOR update or FOR delete clause could write, and a FOR select clause that wrote was stored and failed the first time a read reached the write. A permission clause stored by 3.3 that writes now fails with the error above each time it is evaluated, and writes nothing.
Using IF NOT EXISTS clause
The IF NOT EXISTS clause can be used to define a table only if it does not already exist. You should use the IF NOT EXISTS clause when defining a table in SurrealDB if you want to ensure that the table is only created if it does not already exist. If the table already exists, the DEFINE TABLE statement will return an error.
It's particularly useful when you want to safely attempt to define a table without manually checking its existence first.
On the other hand, you should not use the IF NOT EXISTS clause when you want to ensure that the table definition is updated regardless of whether it already exists. In such cases, you might prefer using the OVERWRITE clause, which allows you to define a table and overwrite an existing one if it already exists, ensuring that the latest version of the table definition is always in use.
-- Create a TABLE if it does not already exist
DEFINE TABLE IF NOT EXISTS reading;
Using OVERWRITE clause
The OVERWRITE clause can be used to define a table and overwrite an existing one if it already exists. You should use the OVERWRITE clause when you want to modify an existing table definition. If the table already exists, the DEFINE TABLE statement will overwrite the existing table definition with the new one.
-- Create an TABLE and overwrite if it already exists
DEFINE TABLE OVERWRITE example;
Table with specialized TYPE clause
When defining a table in SurrealDB, you can specify the type of data that can be stored in the table. This can be done using the TYPE clause, followed by either ANY, NORMAL, or RELATION.
With TYPE ANY, you can specify a table to store any type of data, whether it's a normal record or a relational record.
With TYPE NORMAL, you can specify a table to only store "normal" records, and not relations. When a table is defined as TYPE NORMAL, it will not be able to store relations. This can be useful when you want to restrict the type of data that can be stored in a table in schemafull mode.
Finally, with TYPE RELATION, you can specify a table to only store relational type content. This can be useful when you want to restrict the type of data that can be stored in a table.
DEFINE TABLE person TYPE ANY;
DEFINE TABLE person;
With TYPE NORMAL, you can specify a table to only store "normal" records, and not relations.
-- Since it's default, we can also omit the TYPE clause
DEFINE TABLE person TYPE NORMAL;
With TYPE RELATION, you can specify a table to only store relational type content, and restrict what kind of relations can be stored.
-- Just a RELATION table, no constraints on the type of table
DEFINE TABLE likes TYPE RELATION;

-- Define a relation table, and constrain the type of relation which can be stored
DEFINE TABLE likes TYPE RELATION FROM user TO post;
-- OR use IN and OUT alternatively to FROM and TO
DEFINE TABLE likes TYPE RELATION IN user OUT post;
-- To allow a link to one of a possible set of record types, use the | operator
DEFINE TABLE likes TYPE RELATION FROM user TO post|video;
DEFINE TABLE likes TYPE RELATION IN user OUT post|video;
-- Define a relation table, and constrain the type of relation which can be stored
DEFINE TABLE assigned_to SCHEMAFULL TYPE RELATION IN tag OUT sticky
PERMISSIONS
FOR create, select, update, delete
WHERE in.owner == $auth.id AND out.author == $auth.id;Using ENFORCED to ensure that related records exist
As relations are represented by standalone tables, they can be constructed before any linked records exist.
RELATE city:one->road_to->city:two SET
    distance = 12.4,
slope = 5.4;[
{
distance: 12.4f,
id: road_to:pacwucj25a056hhs2s5h,
in: city:one,
out: city:two,
slope: 5.4f
}
]As such, a query on the relation will return nothing until the records it has been defined upon are created.
SELECT ->road_to->city FROM city;

CREATE city:one, city:two;
SELECT ->road_to->city FROM city;-------- Query --------
[]
-------- Query --------
[
{
"->road_to": {
"->city": [
city:two
]
}
},
{
"->road_to": {
"->city": []
}
}
]If this behaviour is not desirable, the ENFORCED clause can be used on a table of TYPE RELATION to disallow a RELATE statement from working unless it points to existing data.
DEFINE TABLE road_to TYPE RELATION IN city OUT city ENFORCED;

RELATE city:one->road_to->city:three SET
    distance = 5.5,
slope = 30.0;"The record 'city:one' does not exist"The endpoint check is an admission gate on the write path, so it is deferred during an import, alongside the field, event, view and changefeed checks that already defer there. An export writes tables in name order, which can place an enforced relation table before the tables it points at, and the check would otherwise reject every edge as its endpoints did not yet exist.
Before SurrealDB 3.3.0, restoring an export of a database containing an ENFORCED relation table silently dropped its edges whenever the relation table sorted before its endpoint tables - knows before person, for example. The vertices and their counts restored correctly, so the loss only showed up on a traversal. If you restored such an export on an earlier version, check the edge counts before relying on the result.
Using LIGHTWEIGHT for relations without properties
Available since: v3.3.0
A relation can be specified as LIGHTWEIGHT, in which it becomes an edge that stores nothing but the connection between its two endpoints. There is no edge record, so the edge cannot carry properties, and the table cannot take a DEFINE FIELD, a DEFINE INDEX or a DEFINE EVENT.
DEFINE TABLE follows TYPE RELATION IN person OUT person LIGHTWEIGHT;The saving in storage is the reward for opting into these constraints. The reason is that the edge's id becomes the pair of endpoints, written follows:[in, out], so identity and connection are the same value. That makes RELATE idempotent:
CREATE person:one, person:two RETURN NONE;
RELATE person:one->follows->person:two;[{ id: follows:[person:one, person:two], in: person:one, out: person:two }]Running that RELATE again returns the same record, because the id it would write is the one already there. On a classic relation the same two statements produce two separate edges with two generated ids. Supplying your own non-canonical id on a lightweight table is rejected, so the guarantee holds however the edge is written.
This is the behaviour that the unique-key pattern builds by hand on a classic relation, using a composite id or a field plus a unique index. LIGHTWEIGHT makes it a property of the table, with no index to define and keep in step.
LIGHTWEIGHT implies ENFORCED, because a vertex deletion is the only cleanup a record-less edge has. IN and OUT are therefore required, and can be widened but not narrowed while the table holds edges. The pair renders canonically as ENFORCED LIGHTWEIGHT and parses in either order.
What a lightweight relation rejects
The clause is a promise that the edge will never need a record, and everything that assumes one raises an error rather than failing quietly:
| Rejected | Why |
|---|---|
A data clause on RELATE, and CREATE / INSERT RELATION / UPDATE / UPSERT | There is no record to write fields to |
DEFINE FIELD, DEFINE INDEX, DEFINE EVENT on the table | Same, and an index has no record to point at |
SCHEMAFULL, CHANGEFEED, DROP, and AS clauses | Each presumes stored records |
A LIVE SELECT subscription on the table | Not supported on a record-less relation |
| Clearing the flag on a table that holds edges | The edges have no records to fall back to |
| Setting it on a table that already holds edges | The existing edges have non-canonical ids |
Narrowing IN or OUT while edges exist | The endpoint tables are what make a full scan possible |
REMOVE TABLE while edges exist | The edges live under the endpoint tables' keys, which a table wipe cannot reach |
| Using a lightweight edge as the endpoint of another relation | An edge on an edge would break the record-less scan |
Reads are unaffected, because the engine synthesizes the record a query expects. A point read by canonical id returns the endpoints as well as the id:
SELECT * FROM ONLY follows:[person:one, person:two];{ id: follows:[person:one, person:two], in: person:one, out: person:two }Idiom access resolves against that same synthesized record, so follows:[person:one, person:two].out.id returns person:two, and record::exists answers as it would for a stored edge. Counts, record ranges and ordering all work, reading the relation from its endpoint tables, and table-level PERMISSIONS are enforced as they are on a classic relation.
DELETE works in every form: by id, by traversal, by whole table, and through a vertex cascade. Only writes are not permitted:
UPDATE follows:[person:one, person:two] SET weight = 1;"a LIGHTWEIGHT relation's edges cannot be updated: they carry no data beyond `id`, `in` and `out`"Using INLINE EDGES and INLINE REFERENCES to cache adjacency
Available since: v3.3.0
A graph traversal normally reads the edges of each record it starts from by scanning a range of keys, one scan per record. INLINE EDGES @number keeps a cache for every record of the table: one value that holds all of the record's edges in one direction, for records with at most that number of edges in that direction. A traversal that starts from many records then reads all of their caches in one batched lookup. INLINE REFERENCES @number does the same for the incoming record references that a <~ lookup reads.
The clauses go on the table of the records that the edges or references connect, not on the relation table:
DEFINE TABLE person INLINE EDGES 64 INLINE REFERENCES 32;
DEFINE TABLE likes TYPE RELATION IN person OUT post;
Here each person record caches up to 64 edges in each direction, such as the likes edges that a person->likes->post traversal reads, and up to 32 records that reference it. Queries return the same results with or without a cache, because every write that adds or removes an edge or a reference updates the cache in the same transaction.
A few details:
A record's cache is built the first time one of its edges or references is written after the clause is set. Until then, the traversal scans the keys as it would without the clause.
A record with more entries than the cap stops using its cache and goes back to the scan. It keeps using the scan even if entries are removed later, until the cap is changed.
The cap can be from 0 to 256, and
0turns the cache off in the same way as leaving the clause out. Each edge or reference written rewrites the record's whole cache value, so a larger cap costs more to maintain. A cap above 256 fails withan INLINE cache cap cannot exceed 256.Changing or removing a cap, with
DEFINE TABLE OVERWRITEorALTER TABLE, discards the table's existing caches of that kind, which are then rebuilt as edges or references are written.A traversal over a range of edge record IDs (
->likes:a..b), aVERSIONquery, and a filter on anINLINEfield read the keys rather than the cache.
Under EXPLAIN ANALYZE, a GraphEdgeScan or ReferenceScan reports how many lookups were served from a cache as cache_hits, and how many went back to the scan as cache_misses.
Separately from these caches, a background task packs recently written adjacency keys into blocks, which a traversal reads faster than separate keys. It runs when writes or reads queue work for it, and at least once in every interval set by the --graph-fold-interval option of surreal db start (SURREAL_GRAPH_FOLD_INTERVAL), which is 5 seconds by default. Under EXPLAIN ANALYZE, a GraphEdgeScan reports the entries it read from blocks as block_hits and from separate keys as delta_hits.
Inserting data from undefined fields on a SCHEMAFULL table
Available since: v3.0.0
Previously, an insert into a SCHEMAFULL table would work even if extra data was present. The query below shows this behaviour, in which the data inside unneeded_data is simply filtered out.
DEFINE TABLE user SCHEMAFULL;
DEFINE FIELD name ON user TYPE string;
DEFINE FIELD user_num ON user TYPE int;

CREATE ONLY user CONTENT {
    name: "Billy",
    user_num: 100,
    unneeded_data: {
        some: "other",
        needless: "data"
    }
};{
id: user:r38bg4fnp9nurksd06nl,
name: 'Billy',
user_num: 100
}While convenient, this led to the possibility of a typo leading to unexpected results.
DEFINE TABLE user SCHEMAFULL;
DEFINE FIELD name ON user TYPE string;
DEFINE FIELD user_num ON user TYPE option<int>;

CREATE ONLY user CONTENT {
    name: "Billy",
    User_num: 100 // Note: field is capitalized
};
The output shows that the user lacks a value for user_num even though the query above intended to provide this data.
{
	id: user:jn4762t7oyure86fe3qk,
	name: 'Billy'
}
The same query in SurrealDB 3.0 now returns an error.
"Found field 'User_num', but no such field exists for table 'user'"To avoid an error when working with data that contains unneeded fields, use .{} (the destructuring operator) to pass on only the necessary fields.
DEFINE TABLE user SCHEMAFULL;
DEFINE FIELD name ON user TYPE string;
DEFINE FIELD user_num ON user TYPE int;

CREATE ONLY user CONTENT {
    name: "Billy",
    user_num: 100,
    unneeded_data: {
        some: "other",
        needless: "data"
    }
}.{
    -- Only pass on the name and user_num data
    name,
    user_num
};
GraphQL names and deprecation
Available since: v3.1.0
GRAPHQL_ALIAS sets the name that the GraphQL schema uses for a table, in place of the table name. The alias replaces the table name in the query fields, the mutation fields and the connection types, so the example below gives member, members, members_aggregate, membersConnection and createMember. The object type, the input types and the filter and order types keep the table's own name. It must be a valid GraphQL name, matching [_A-Za-z][_0-9A-Za-z]*, and any other value is rejected when the table is defined.
GRAPHQL_DEPRECATED takes a reason, which the schema adds to the start of the description of the fetch and list queries and of the mutations as [Deprecated: reason]. The aggregate and connection queries do not carry it.
DEFINE TABLE person
	GRAPHQL_ALIAS "member"
	GRAPHQL_DEPRECATED "Use the account table instead";