A single node of SurrealDB can be run with data persisted to the filesystem, using SurrealKV (surrealkv://) as the storage engine. It uses the same transaction and isolation semantics as every other SurrealDB deployment.
SurrealKV is the only on-disk engine. SurrealDB 4.0 removed the RocksDB engine. A rocksdb:// path is still accepted as a deprecated spelling of surrealkv://: the server opens it with SurrealKV, converts any RocksDB data in the directory, and logs a warning to use surrealkv:// instead. See Moving a RocksDB database to SurrealKV.
Start the server
surreal db start surrealkv://mydatabase.dbThe default logging level for the database server is info. To control the logging verbosity, specify the --log argument. The following command starts the database with debug level logging, resulting in more logs being output to the terminal. If extra verbosity is not needed, specify a lower level or simply remove the flag, which will default to the info level.
surreal db start --log debug surrealkv://mydatabase.dbThe SurrealDB server runs with authentication enabled by default. To disable it, the --unauthenticated flag can be passed in.
surreal db start --unauthenticated surrealkv://mydatabase.dbHowever, for anything but simple testing, it is better to configure your initial root-level user by setting the --user and --pass command-line arguments. The following command starts the database with a top-level user named root with a password set to secret. The root user will be persisted in storage, which means you don't have to include the command line arguments next time you start SurrealDB.
surreal db start --user root --pass secret surrealkv://mydatabase.dbIn order to change the default port that SurrealDB uses for web connections and from database clients you can use the --bind argument. The following command starts the database on port 8080.
surreal db start --user root --pass secret --bind 0.0.0.0:8080 surrealkv://mydatabase.dbAfter running the above command, you should see the SurrealDB server start up successfully.
INFO surrealdb::core::kvs::ds: Starting kvs store at relative path surrealkv://mydatabase.db
INFO surrealdb::core::kvs::ds: Started surrealkv kvs store
INFO surrealdb::core::kvs::ds: This is a new SurrealDB instance. Initialising default namespace 'main' and database 'main'
INFO surrealdb::core::kvs::ds: Credentials were provided, and no root users were found. The root user 'root' will be created
INFO surrealdb::net: Started web server on 0.0.0.0:8080
For details on the different commands available, visit the CLI tool documentation.
Run your first query
With the server running, open a second terminal and connect to it with the surreal db sql command. This starts a SurrealQL REPL against the server, using the credentials from the step above.
surreal db sql --endpoint http://localhost:8000 --username root --password secret --namespace main --database main --prettyCreate a record. There is no need to define the table first, because SurrealDB creates it on the first write.
CREATE person:tobie SET name = "Tobie", city = "London";[
{
city: 'London',
id: person:tobie,
name: 'Tobie'
}
]Select it back to confirm the round trip.
-- Setup from the example above
CREATE person:tobie SET name = "Tobie", city = "London";

SELECT name, city FROM person;[
{
city: 'London',
name: 'Tobie'
}
]When you finish, exit the REPL with Ctrl+C. The record persists on disk, so it is still there the next time you start the server against the same path.
SurrealKV
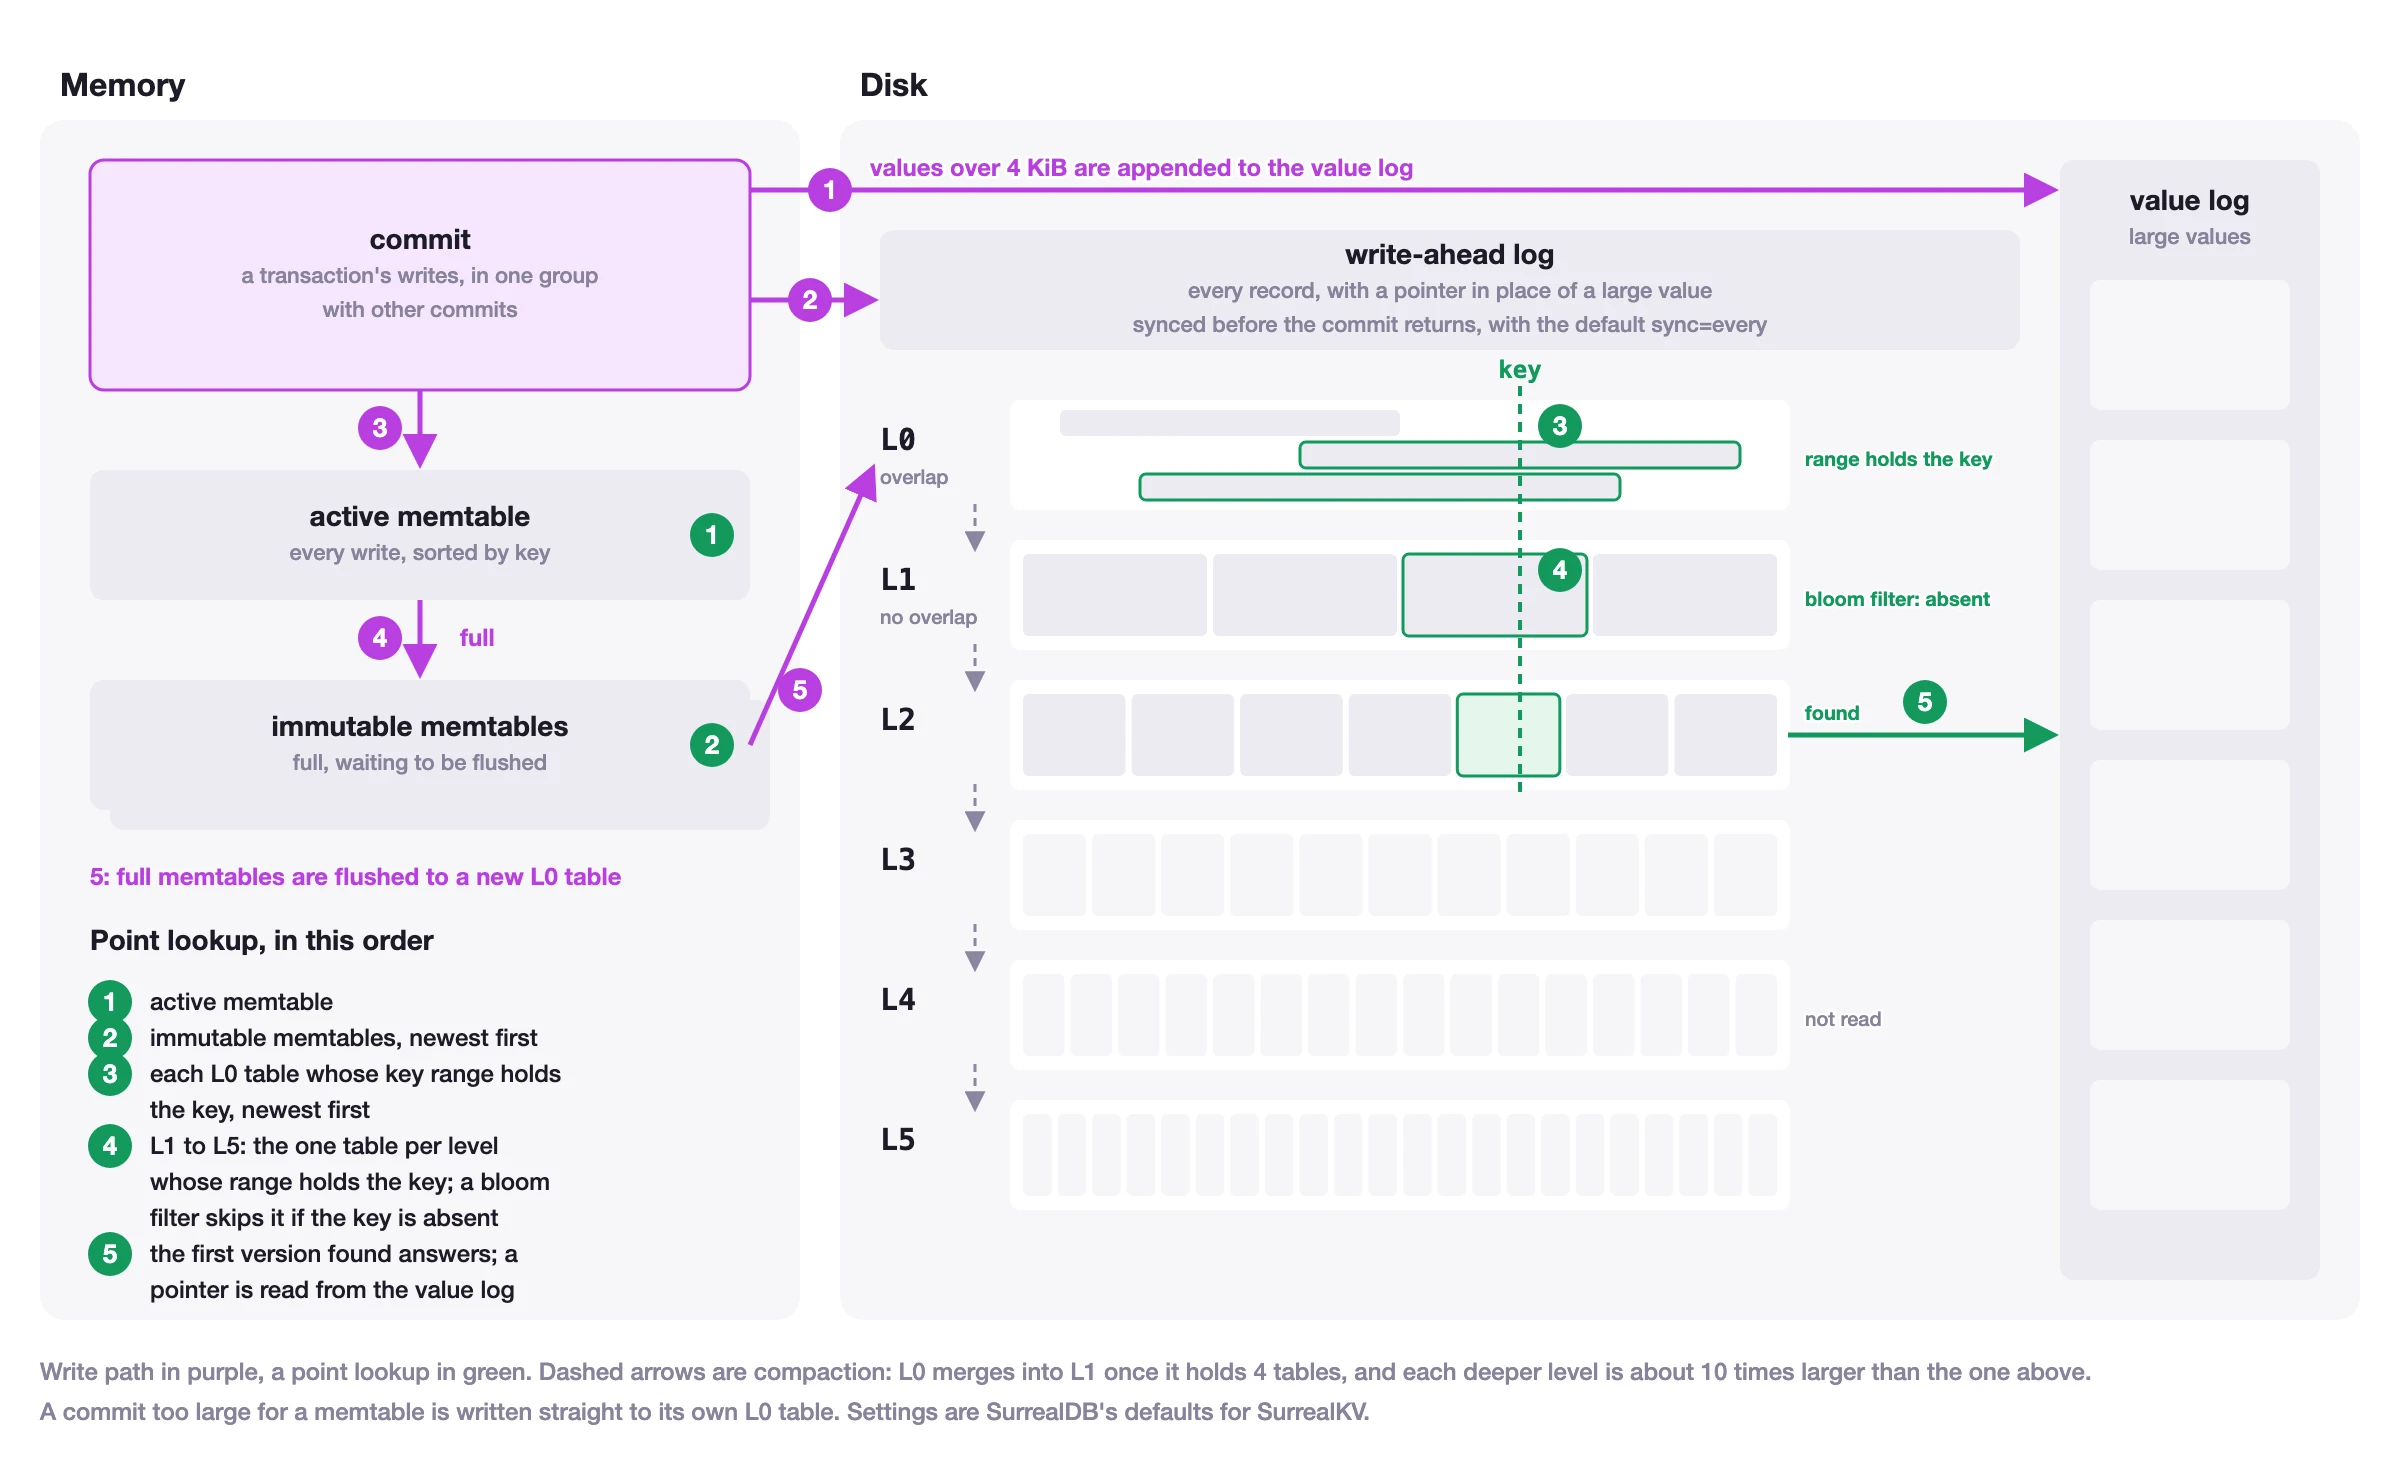
SurrealKV is the storage engine SurrealDB develops for on-disk data: a versioned key-value store built on an LSM (log-structured merge) tree, written in Rust and released together with SurrealDB.
SurrealDB 4.0 uses SurrealKV 1.0, whose on-disk format is stable from that release. The first time it opens a data directory written by RocksDB or by an earlier SurrealKV release, it converts the directory. The conversion is one-way, so take a copy of the directory first, or convert ahead of time into a new directory with skv migrate, which leaves the original unchanged. See Moving a RocksDB database to SurrealKV and Converting ahead of time with skv.
Key features
Concurrent reads and writes: MVCC snapshots let readers proceed without waiting for writers. The isolation a query sees is defined by the query layer.
Durability settings: a commit is synced to disk before it returns, or flushed in the background, depending on the
syncsetting.Versioning: with versioning enabled, every write keeps its timestamp, so a query can read the data as it was at an earlier time. See versioned startup and the
VERSIONclause.LSM structure: writes collect in memtables and flush to sorted tables (SSTables) on disk.
Value log: large values are stored apart from the LSM tree, so compaction does not rewrite them, and space they no longer use is reclaimed by garbage collection.
Checksums: SSTable blocks and write-ahead log records carry checksums, which are verified when they are read from disk.
Checkpoints: the engine can take and restore consistent snapshots. See the SurrealKV repository.
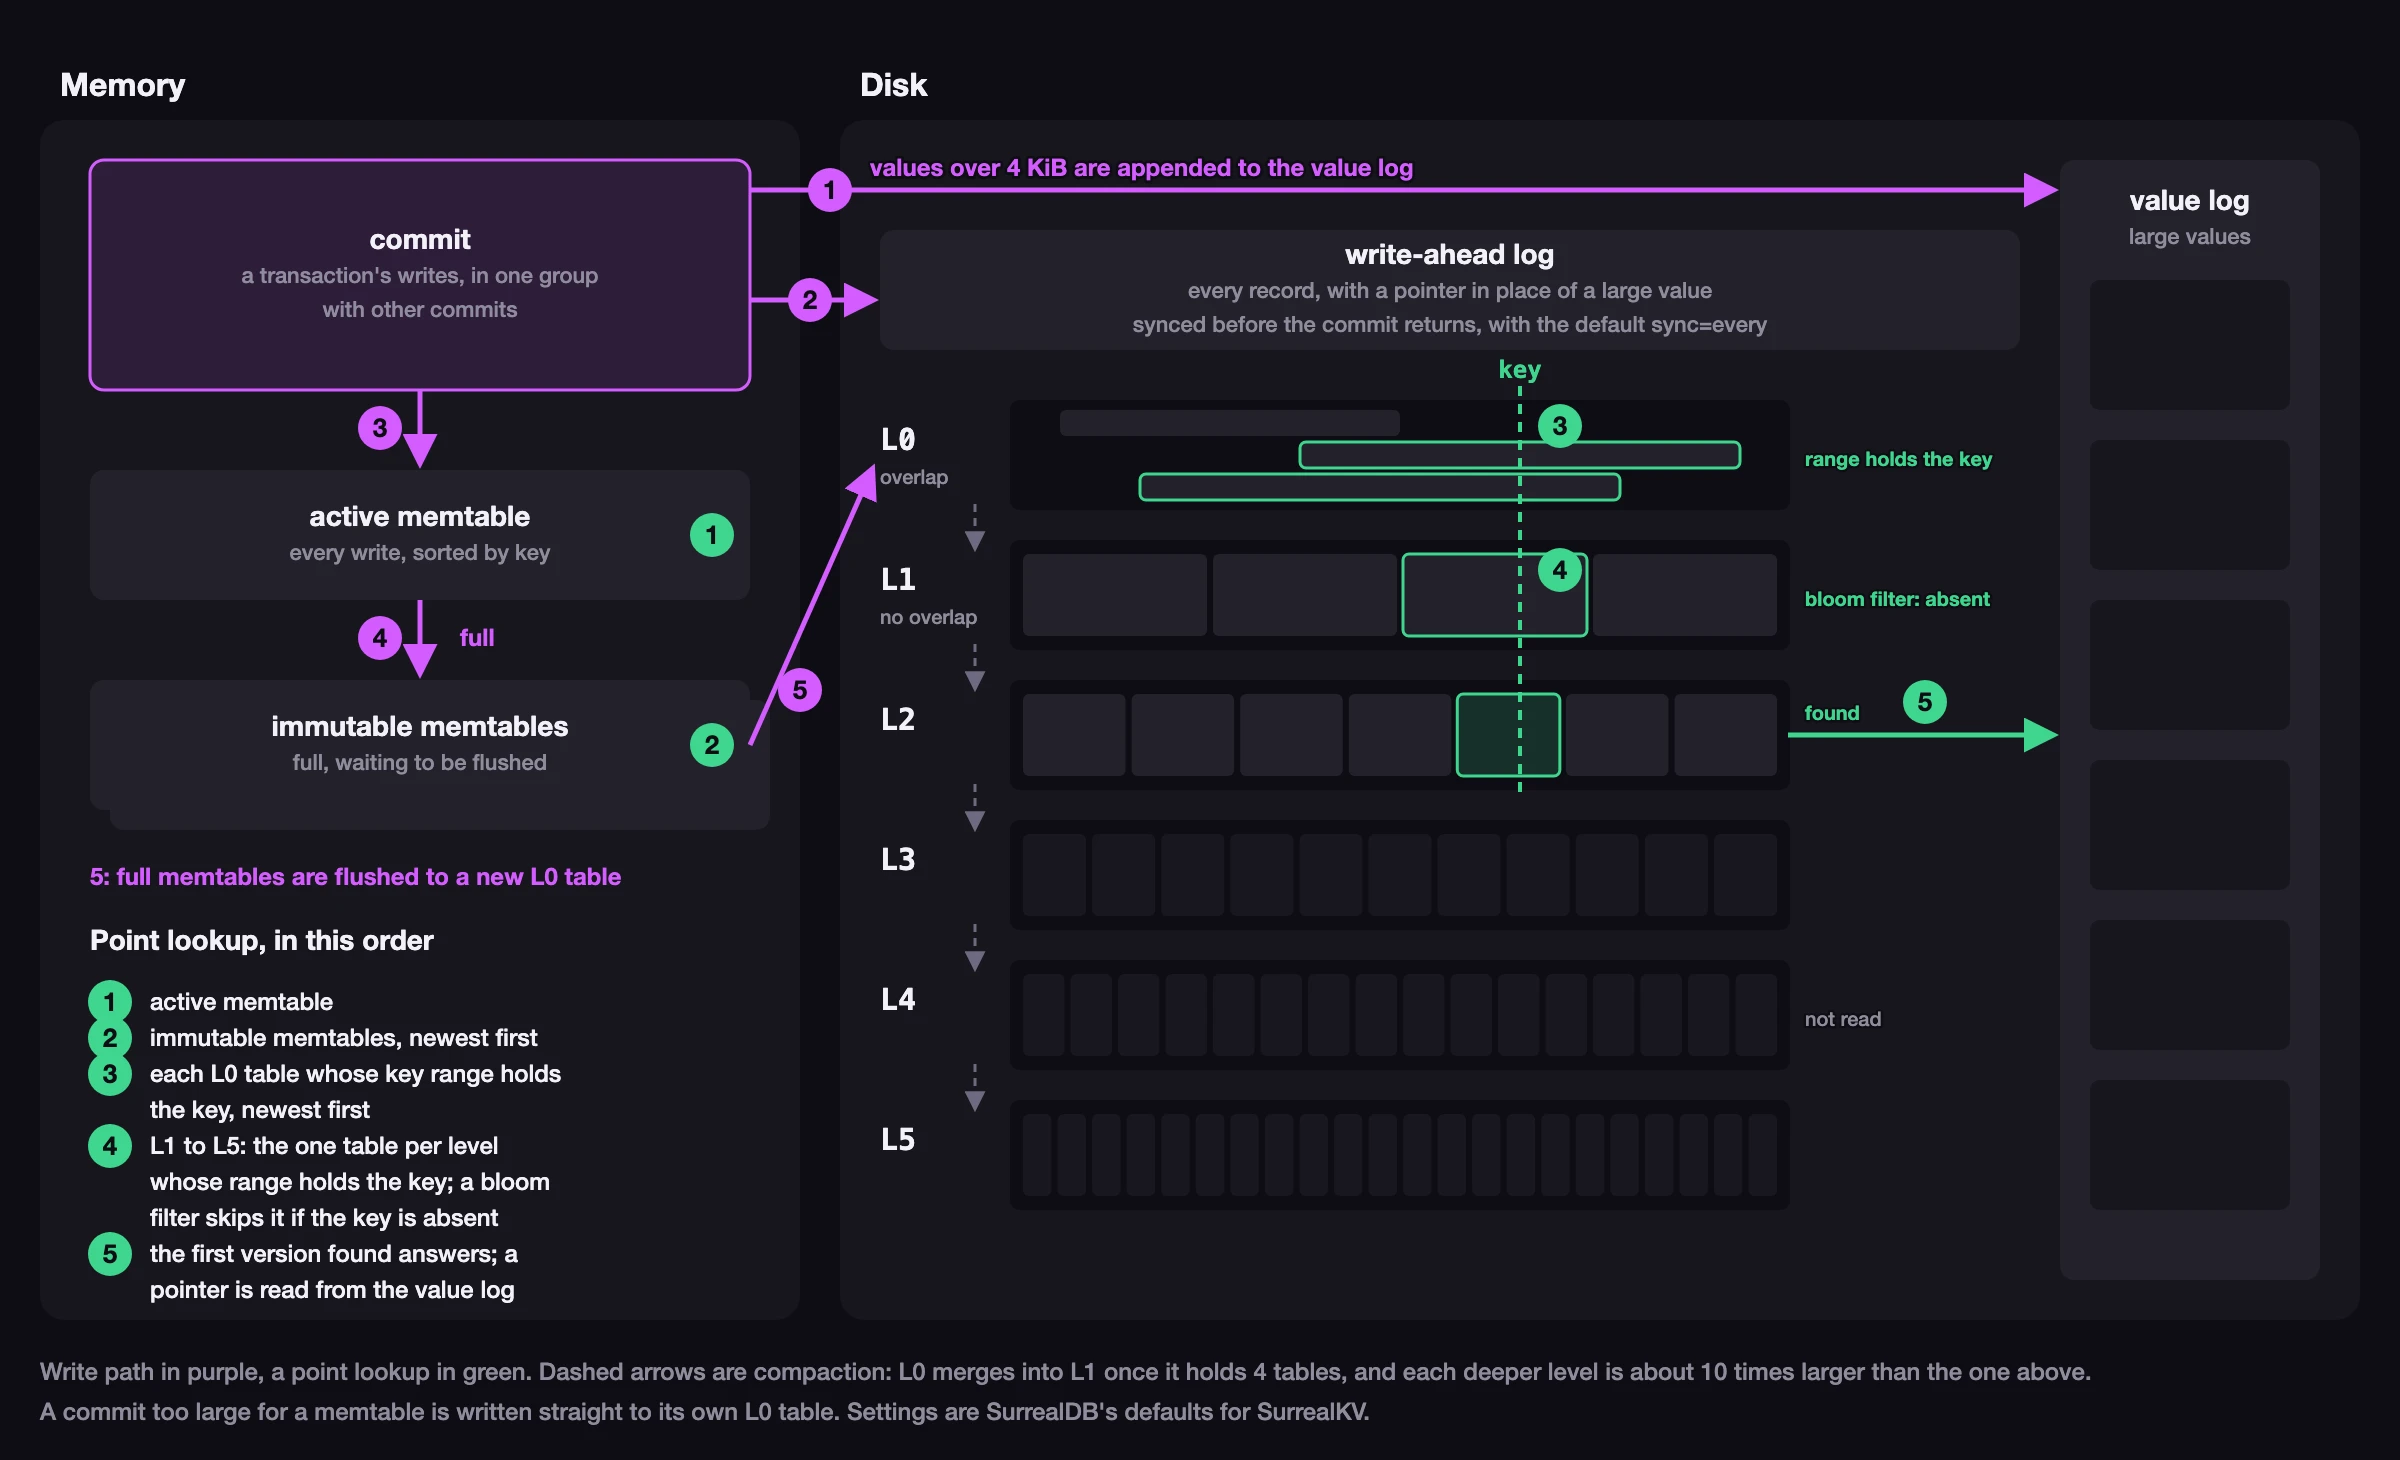
The diagram below follows a commit to disk, and a point lookup back through the memtables and levels.
Parameters on startup
Parameters such as versioned and sync control versioning and durability. See Supported parameters for SurrealKV and SurrealKV environment variables.
Performance characteristics
SurrealKV suits write-heavy workloads, access by key prefix, and time-series or versioned data, where writes append and keys arrive in order.
Writes: commits are batched into memtables and written to disk as sorted tables, which keeps disk writes sequential.
Reads: a point lookup checks the memtables, then the tables that can hold the key, and a bloom filter skips a table that does not hold it. A wide range scan reads across several tables and levels, so a record ID or index that keeps related records together keeps a scan short.
Data larger than memory: the working set stays in memtables and the block cache, and the rest is read from disk.
Compaction: merging tables reclaims space, and uses extra disk I/O and temporary disk space while it runs.
Platforms: SurrealKV runs on Linux, macOS and Windows, and in the browser, where it keeps its files in the Origin Private File System and runs in a dedicated worker (see the Wasm engine). The platform support table in the SurrealKV repository lists which targets are tested on every change.
Next steps
Query from your application with an SDK - each language guide starts with a connect-and-query walkthrough.
Try SurrealQL without a server in the Studio Sandbox.
Learn the query language, starting with the
SELECTstatement.