SurrealDB is ACID-compliant, so the work inside a transaction either commits as a whole or rolls back with no partial effect. By default each SurrealQL statement runs in its own transaction, including side effects such as defined events. A single CREATE, UPDATE or SELECT is therefore atomic on its own.
This page covers manual transactions, which group statements that must succeed or fail together, and the isolation guarantees that apply when many clients read and write at the same time.
Implicit transactions
BEGIN is not the only thing that groups statements. Blocks and function bodies each run as one transaction, despite the lack of BEGIN or COMMIT, which is why they are described as implicit. Each behaves like any other transaction: it commits when it finishes, and rolls back if anything inside it fails.
Implicit transactions commit on normal completion, including an early RETURN. An early return is control flow rather than a failure, so the work already done is kept:
{
    CREATE shipment:shp_5501 SET order = order:ord_8412, carrier = 'DHL';
	-- the caller only wants the id
    RETURN shipment:shp_5501;
	-- never runs
    UPDATE order:ord_8412 SET status = 'shipped';
};
Implicit transactions also roll back on errors, whether that is a THROW or a statement that simply fails, such as a schema violation. Nothing inside survives:
{
    -- rolled back
    CREATE order:ord_8412 SET item = product:keyboard, quantity = 2;
    THROW "Insufficient stock";
    -- never runs
    UPDATE product:keyboard SET stock -= 2;
};
Without the braces the order would persist while the stock it reserved never moved, which is the inconsistency a transaction exists to prevent.
In a bare sequence of statements, each one is its own transaction. Here the THROW reports an error, and both records still exist afterwards, because the statements either side of it committed independently:
CREATE product:keyboard SET stock = 40;   -- commits
THROW "Stop the import";                  -- errors, and stops nothing
CREATE product:mouse SET stock = 25;      -- commits
Both products exist afterwards. A bare THROW reports an error without halting the statements around it, so it cannot be used as a guard clause outside a block.
So wrapping statements in braces is enough to make them atomic.
A block does not, however, give a failure somewhere to be contained. There is one transaction per query rather than a stack of them, so a block inside a manual transaction is part of that transaction rather than a nested one. A THROW inside the block aborts the whole thing, including the statements that ran before it:
BEGIN;
UPDATE account:one SET balance -= 100;    -- rolled back as well
{
    CREATE ledger_entry:le_9001 SET amount = 100, account = account:one;
    THROW "Ledger rejected the entry";
};
UPDATE account:two SET balance += 100;    -- never runs
COMMIT;                                   -- fails: the transaction was already aborted
Manual transactions
Three statements control a manual transaction:
BEGIN [ TRANSACTION ];
COMMIT [ TRANSACTION ];
CANCEL [ TRANSACTION ];
BEGIN opens the transaction. COMMIT makes every change inside it a permanent part of the database. CANCEL rolls those changes back instead. If any statement inside the transaction fails, the whole transaction is rolled back and no change survives.
-- Create two accounts for bank customers
CREATE account:one SET balance = 135605.16;
CREATE account:two SET balance = 91031.31;

-- Start a manual database transaction
BEGIN TRANSACTION;

-- Update the balances of each customer involved in the wire transfer
UPDATE account:one SET balance += 300.00;
UPDATE account:two SET balance -= 300.00;

-- Apply both updates together. Had either statement failed, the database
-- would remain in its initial state.
COMMIT TRANSACTION;
Replacing COMMIT TRANSACTION with CANCEL TRANSACTION in the example above leaves both balances untouched.
Client SDKs expose the same model through transaction handles. See the transactions guide for your language under SDKs.
THROW to conditionally cancel a transaction
A transaction rolls back on its own when a statement errors. THROW breaks out of one deliberately, at any point. THROW can be followed by any value, which serves as the error message, and is usually a string.
CREATE account:one SET dollars =  100;
CREATE account:two SET dollars =  100;

LET $transfer_amount = 150;

BEGIN TRANSACTION;

UPDATE account:one SET dollars -= $transfer_amount;
UPDATE account:two SET dollars += $transfer_amount;
IF account:one.dollars < 0 {
    THROW "Insufficient funds, would have $" + <string>account:one.dollars + " after transfer"
};
COMMIT TRANSACTION;
SELECT * FROM account;'An error occurred: Insufficient funds, would have $-50 after transfer'[
{
dollars: 50,
id: account:one
},
{
dollars: 150,
id: account:two
}
]Control flow inside a transaction
THROW is the way to abandon a transaction. To change course without abandoning it, put the statements that depend on a condition inside a block. A block inside BEGIN ... COMMIT is part of the same transaction, so everything it writes commits or rolls back with the rest. Inside it, RETURN leaves the block early, IF chooses between branches, and FOR with CONTINUE and BREAK controls a loop. None of these is an error, so the transaction still commits.
Skipping the rest of the work
An early RETURN works as a guard clause. In the following example, a vote is recorded every time, but the item's score total only changes when the vote's score changes. The block returns a value that says which happened:
DEFINE TABLE vote;
CREATE item:lamp SET score_total = 0;

BEGIN;
{
    LET $previous = (SELECT VALUE score FROM ONLY vote:ana_lamp);
    UPSERT vote:ana_lamp SET score = 4, voted_at = time::now();
    IF $previous == 4 {
        RETURN "unchanged";
    };
    UPDATE item:lamp SET score_total += 4 - ($previous ?? 0);
    RETURN "counted";
};
COMMIT;'counted''unchanged'On the second run the vote's voted_at is still updated and committed, while item:lamp keeps its total of 4. A THROW in place of the RETURN would have rolled back the vote as well, and reported an error.
RETURN leaves the block, not the transaction: statements after the block still run, and COMMIT commits them. Use a block for a guard clause like this one, rather than a RETURN placed directly between BEGIN and COMMIT.
Loops
CONTINUE moves to the next item of a FOR loop, and BREAK ends the loop. In the following example, order lines with no quantity are skipped, and shipping stops at the first line the stock cannot cover:
CREATE product:keyboard SET stock = 5;
LET $lines = [
    { order: order:a, quantity: 2 },
    { order: order:b, quantity: 0 },
    { order: order:c, quantity: 2 },
    { order: order:d, quantity: 3 },
    { order: order:e, quantity: 1 }
];

BEGIN;
FOR $line IN $lines {
    IF $line.quantity == 0 { CONTINUE };
    IF product:keyboard.stock < $line.quantity { BREAK };
    UPDATE product:keyboard SET stock -= $line.quantity;
    CREATE shipment SET order = $line.order, quantity = $line.quantity;
};
COMMIT;

SELECT VALUE order FROM shipment ORDER BY order;[order:a, order:c]Order d needs three keyboards when one is left, so the loop stops there, and order e is not shipped even though it would fit. To skip lines that do not fit and keep going, use CONTINUE in place of BREAK.
BEGIN, COMMIT and CANCEL themselves only take effect as statements of their own, not inside a block or a loop. See Cancelling a transaction.
Snapshot isolation
Every SurrealDB transaction runs under snapshot isolation unless it asks for serializable isolation. When a transaction starts, it sees a consistent point-in-time view of the database. That snapshot stays stable for the lifetime of the transaction, so reads inside the transaction do not observe concurrent writes from other transactions until commit.
SurrealDB does not offer weaker isolation levels. You cannot downgrade to read committed or read uncommitted.
On commit, the engine checks for write conflicts. If two concurrent transactions modified the same key, the later commit fails with a transaction conflict error and must be retried. There is no silent last-writer-wins merge at the storage layer.
Records that a transaction only reads are outside that check by default. The FOR UPDATE clause brings them into it.
Snapshot isolation applies on every deployment model and storage backend: embedded and server, single-node and distributed, SurrealKV, SurrealMX, SurrealDS and TiKV. The query layer enforces the same contract whichever engine persists the keys underneath. Some engines also offer a stronger level, listed in Isolation by storage engine.
What you get in practice
Snapshot isolation with conflict detection on commit protects against the anomalies most application developers plan for:
| Anomaly | Protected? | Notes |
|---|---|---|
| Dirty reads | Yes | A transaction never reads uncommitted data from another transaction. |
| Non-repeatable reads | Yes | Re-reading the same data inside a transaction returns the same values. |
| Lost updates (same key) | Yes | Concurrent writes to the same key cannot both commit; one transaction must retry. |
| Write skew | Opt in | Covered per record with FOR UPDATE; see write skew below. |
In database terms, snapshot isolation sits between read committed and serialisable. It matches the default isolation level in MySQL (InnoDB REPEATABLE READ) and PostgreSQL's optional REPEATABLE READ level. For the specific records a transaction names, FOR UPDATE closes the remaining gap on every engine, and on an engine that offers it, serializable isolation closes it for the whole transaction.
Compared with PostgreSQL REPEATABLE READ
PostgreSQL's REPEATABLE READ is snapshot isolation too, so the two protect against the same anomalies. The mechanisms differ in ways that decide where an application handles a conflict.
PostgreSQL REPEATABLE READ | SurrealDB | |
|---|---|---|
| Snapshot taken | At the first statement in the transaction | At the start of the transaction |
| Competing writer | Blocks on a row lock until the first transaction resolves | Never blocks; proceeds and commits |
| Conflict surfaces | At the conflicting statement, as could not serialize access due to concurrent update | At COMMIT, as a transaction conflict error |
SELECT ... FOR UPDATE | Takes a row lock, and raises straight away if the row moved since the snapshot | Registers the record, and raises at COMMIT if it moved |
| Write skew | Needs explicit locking, or the SERIALIZABLE level | Needs FOR UPDATE, or the SERIALIZABLE level |
| Blanket serialisable level | SERIALIZABLE covers predicate-based anomalies as well | SERIALIZABLE on SurrealMX and SurrealDS; FOR UPDATE covers named records only |
Two consequences follow for application code. Conflicts arrive later in SurrealDB: a FOR UPDATE read never fails on account of a concurrent write, so retry logic wraps the whole transaction rather than guarding individual statements. And because FOR UPDATE cannot register a predicate, an invariant that depends on a set of records rather than on named ones needs either serializable isolation, on an engine that offers it, or a record that stands in for the set, such as a counter or a parent record that every participant reads for update.
Write conflicts and retries
When a commit fails because another transaction wrote the same key first, SurrealDB returns a transaction conflict error. Your application, or your client's retry logic, should run the transaction again.
From SurrealDB 4.0, a statement that runs in a transaction of its own, outside BEGIN and COMMIT, is run again by the server when it loses a write conflict. The server makes up to 10 attempts, with a short random wait between them, all within the statement's one timeout. Each attempt reads the data as it is when that attempt starts. The conflict error reaches the client only when every attempt fails or the timeout runs out. The server does not run a statement again when:
it is part of a
BEGIN...COMMITblock, where the conflict applies to the whole transaction and the client decides whether to run it again;it did something outside the transaction, such as an
http::request or a write to a file bucket, which a second attempt would repeat;the outcome of its commit is unknown.
The same applies to a FOR UPDATE read inside a statement of its own. When another transaction writes the record between the read and the commit, the server runs the statement again, and the new attempt reads the new value, so the statement commits a result based on current data instead of returning the conflict. Inside BEGIN ... COMMIT, the same change makes COMMIT fail with a conflict that the client retries.
So retry logic in an application is needed for transaction blocks, and for statements that still return a conflict after the server's attempts.
This is normal under concurrent load, not a sign of data corruption. At scale, rising conflict rates show up in metrics such as surrealdb_transaction_conflicts_total - see Observability for monitoring guidance.
Keep transactions short and touch the fewest keys necessary. Long-running transactions that overlap on hot keys see more conflicts.
Defining or rebuilding an index can also cause a retryable conflict, because the build has to see every write to its table. Before it reads the table, a build waits for the write transactions that began before the index was defined or rebuilt, for up to 60 seconds. A transaction that is still open after that, such as one that a client holds open, is refused at commit if it writes the table being indexed, and its retry sees the new index. A transaction that writes only other tables commits as usual.
One case makes a writer wait instead of failing at commit. While a transaction that has defined an index without CONCURRENTLY is open, such as a DEFINE INDEX inside BEGIN ... COMMIT, writes to that table from other sessions on the same node wait for it to end, for at most 60 seconds. See Defining an index inside a transaction.
Unique indexes under concurrent writes
A UNIQUE index is the way to make an insert happen exactly once, for example so that two overlapping workers in a job queue cannot both enqueue the same notification. The index makes this safe because each index entry is a key, so two transactions that write the same indexed value write the same key, and the write conflict check on commit applies to it.
When two concurrent transactions insert records with the same value for a UNIQUE index, neither waits for the other. Each checks the index against its own snapshot, in which the other's uncommitted record does not exist, so both statements succeed. The first transaction to commit wins. The second fails at COMMIT with a transaction conflict error that says the transaction can be retried, and none of its writes are kept. When the losing transaction runs again, its snapshot now holds the committed record, and the insert fails straight away with the unique index error:
DEFINE INDEX unique_key ON notification FIELDS key UNIQUE;

-- Run by two workers at the same time; one commit fails with a
-- transaction conflict, and its retry fails with the index error
BEGIN;
CREATE notification SET key = 'invoice-2041-sent';
COMMIT;Database index `unique_key` already contains 'invoice-2041-sent', with record `notification:...`INSERT IGNORE and INSERT ... ON DUPLICATE KEY UPDATE are safe in the same way. They never produce a duplicate under concurrency, but they decide against the transaction's snapshot. A concurrent insert of the same record id or indexed value that commits first makes the other transaction fail with the retryable conflict error, rather than skipping its record or updating the existing one. On retry, the statement sees the committed record and skips or updates it as usual.
An existence check written into the query gives no such guarantee. Without a unique index, both of the following transactions see no matching task in their snapshots, so both create one and both commit:
DEFINE TABLE task;

BEGIN;
IF !(SELECT * FROM task WHERE key = 'nightly-report') {
    CREATE task SET key = 'nightly-report';
};
COMMIT;
This is the same rule as in PostgreSQL, where INSERT ... WHERE NOT EXISTS (...) is not safe on its own and a unique index is the fix. The difference is in how the conflict arrives: PostgreSQL makes the second inserter wait for the first and then raises the conflict, while SurrealDB lets both proceed and raises it at COMMIT. Retry logic therefore wraps the whole transaction.
A unique index that applies to only some records, such as PostgreSQL's partial unique index, is covered under conditional uniqueness.
Write skew
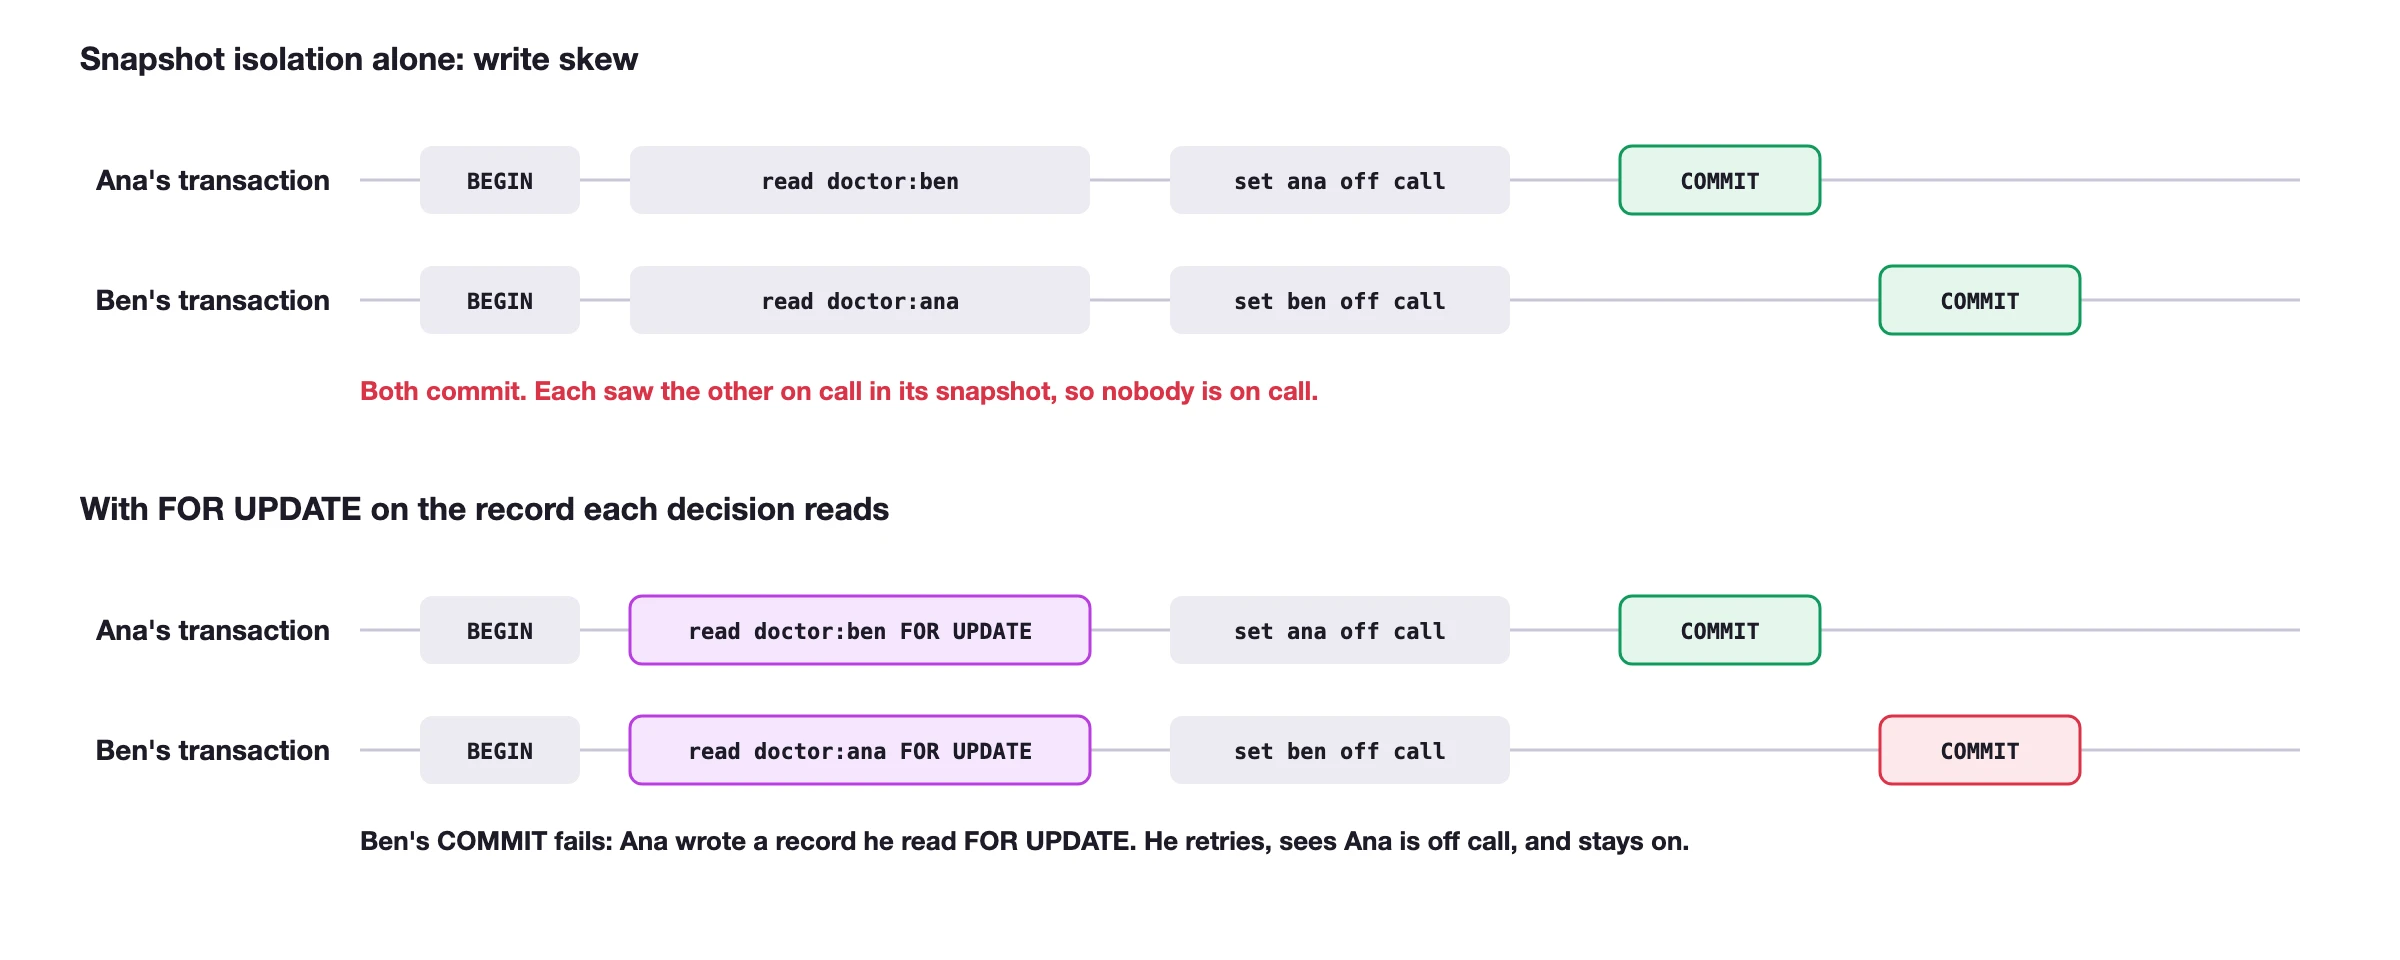
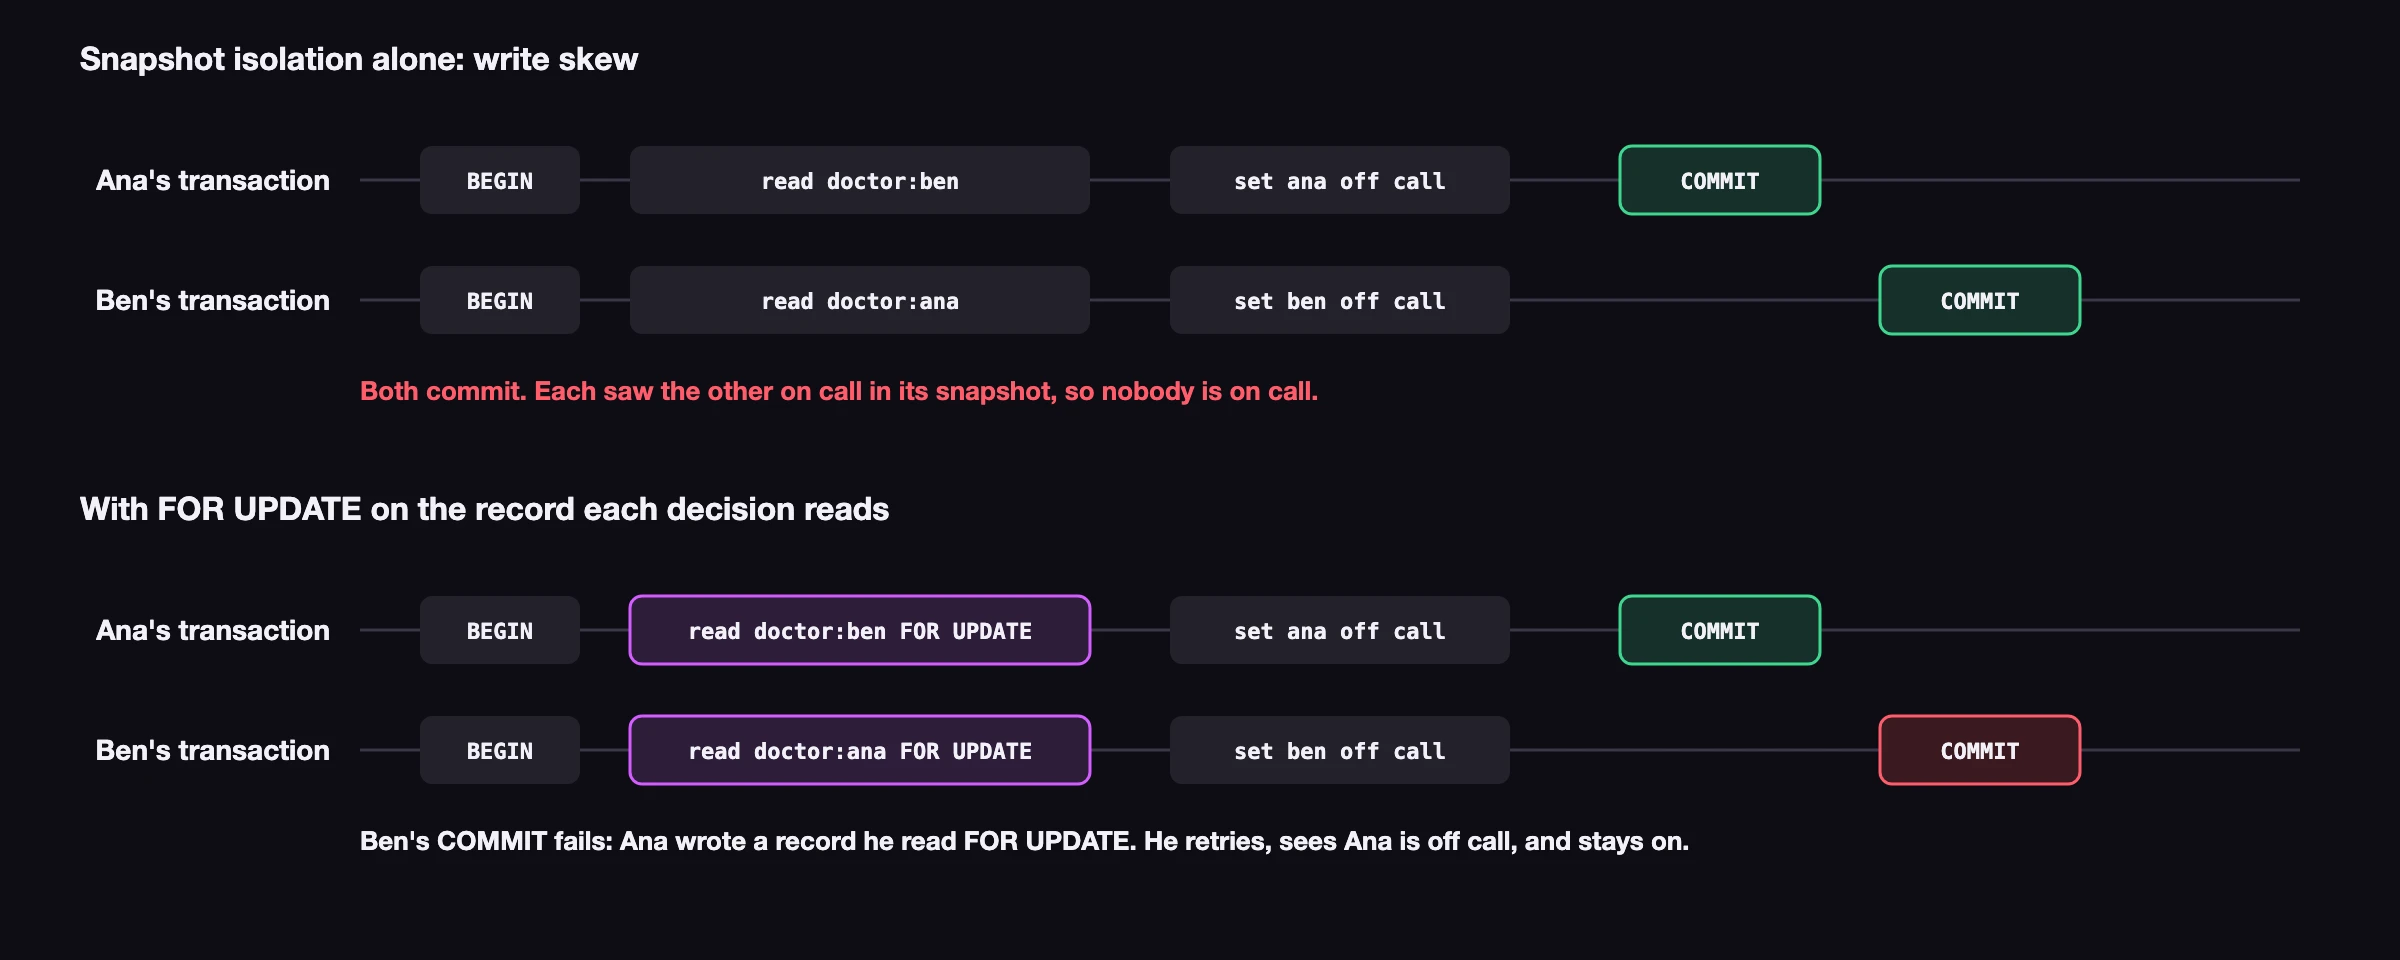
Snapshot isolation does not prevent write skew. Write skew occurs when two transactions each read overlapping state, make independent decisions, and both commit even though their combined effect breaks an invariant.
An everyday example is two doctors on call for the same night, where at least one of them must stay on call. Each checks that the other is still on call and then signs off. Each transaction read a consistent snapshot in which the other doctor was on call, but together they left nobody on call.
Where write skew matters for your workload, read the records the rule depends on with SELECT ... FOR UPDATE. Each doctor's transaction then registers the other doctor's record, which the other transaction writes, so whichever transaction commits second fails. Its retry sees that the other doctor has signed off, and stays on call:
Writing every record the rule depends on has the same effect, because a write is conflict-checked already. That remains the natural choice where the transaction was going to update the record anyway, and conditional updates work on the same principle.
Where the rule depends on a query rather than on named records, such as "no other booking exists for Monday", use serializable isolation on an engine that offers it.
Locked reads with FOR UPDATE
Available since: v3.3.0
The FOR UPDATE clause on SELECT enrols a record that the transaction only reads into the same commit-time conflict check that already covers writes. The transaction commits only if no other transaction wrote that record after the snapshot was taken. Otherwise COMMIT fails with a transaction conflict error and the transaction can be retried.
BEGIN;

-- Register the other doctor's record for commit-time conflict detection
LET $other = SELECT * FROM ONLY doctor:ben FOR UPDATE;

-- The decision below rests on a record that is read but never written,
-- which is exactly the case FOR UPDATE covers
IF $other.on_call {
    UPDATE doctor:ana SET on_call = false;
};

COMMIT;
Three further properties apply beyond the basic guarantee:
Concurrent writers are not blocked. The clause takes no lock. Another transaction can write a registered record and commit normally, and the cost lands on the reading transaction, whose own
COMMITthen fails and must be retried. Readers coming from a database whereSELECT ... FOR UPDATEholds a row lock should plan for retries rather than for waiting.An absent record is still covered. Reading a record id that does not exist registers that id, so a concurrent transaction creating it also invalidates the commit. This is what makes
FOR UPDATEsafe for get-or-create paths.The enclosing statement becomes write-classified. A
FOR UPDATEread nested inside an expression promotes its statement to a write transaction, because the registration can only be validated at commit time.
| Aspect | Behaviour |
|---|---|
| Targets | Record ids only, written literally or passed through a parameter. Tables, record ranges, subqueries and parameters holding a table are rejected. |
| Concurrency model | Optimistic. No lock is taken and no transaction waits; a conflict surfaces at COMMIT on the transaction that read the record. |
| Granularity | One record at a time. Tables, ranges and query predicates are not locked, so a concurrent transaction can still create a new record that matches a predicate. |
| Transaction type | Requires a transaction that commits. A read-only context rejects the clause, since the registration would never be validated. |
| Storage backends | Supported on every storage backend. Where an engine has no conflict-tracked read path the clause is refused outright, so the guarantee is never quietly downgraded. |
| Clause conflicts | Cannot be combined with VERSION, GROUP BY or SPLIT, or with LIMIT across multiple targets. |
FOR UPDATE is used for a record the transaction reads but never writes. A record the transaction also writes is covered already by the write conflict check, so adding the clause there changes nothing.
Serializable isolation
Available since: v4.0.0
A transaction started with BEGIN ISOLATION LEVEL SERIALIZABLE adds every record and range it reads to the commit-time conflict check, not only the records it writes. If another transaction wrote anything it read after its snapshot was taken, its COMMIT fails with a transaction conflict and the transaction can be retried. This rules out write skew, including the cases that depend on a query rather than on named records.
The example below books a doctor for Monday only if no booking exists for that day. Under snapshot isolation, two of these transactions running at the same time both see no booking and both commit, which gives Monday two doctors. Under serializable isolation, the second COMMIT fails, because the first transaction created a record that the second one's SELECT read:
-- Defined once, outside the transaction
DEFINE TABLE booking;

BEGIN ISOLATION LEVEL SERIALIZABLE;

LET $booked = SELECT VALUE id FROM booking WHERE day = 'monday';
IF $booked.is_empty() {
    CREATE booking SET doctor = doctor:ana, day = 'monday';
};

COMMIT;"Cannot COMMIT: Transaction conflict: Read conflict, retry the transaction. This transaction can be retried"Because every read is checked, a serializable transaction conflicts more often than a snapshot one under the same load. Use it for transactions whose correctness depends on what they read, and keep the rest at the default. A few further rules apply:
Statements outside
BEGINalways run at snapshot isolation. Only a transaction started withBEGIN, or with thebeginRPC method and itsisolationoption, can ask for the serializable level.A read-only transaction is unaffected. It commits nothing, so there is nothing to check, and it reads one consistent snapshot at either level.
SERIALIZABLEcannot be combined with aMAX STALENESSabove zero.The level is never quietly lowered. On an engine that does not offer it, the transaction fails with an error naming the levels the engine offers, instead of running at snapshot isolation.
Isolation by storage engine
Every engine runs transactions at snapshot isolation by default. The table shows which also offer the serializable level, and which publish snapshots that a MAX STALENESS read can use:
| Storage engine | Default | SERIALIZABLE | Published snapshots for MAX STALENESS |
|---|---|---|---|
| In-memory (SurrealMX) | SNAPSHOT | Yes | No |
| SurrealDS | SNAPSHOT | Yes | Yes |
| SurrealKV | SNAPSHOT | No | No |
| TiKV | SNAPSHOT | No | No |
On an engine without the serializable level, BEGIN ISOLATION LEVEL SERIALIZABLE fails with:
"The isolation level SERIALIZABLE is not available on this datastore; it offers SNAPSHOT"On those engines, use FOR UPDATE for the records a decision depends on.
Choosing between FOR UPDATE and SERIALIZABLE
Both prevent write skew, and they differ in what they check, where they can be used, and how often they cause a retry:
FOR UPDATE | SERIALIZABLE | |
|---|---|---|
| What is checked at commit | The records the query names | Every record and range the transaction reads |
| A decision based on a query, such as "no booking exists for Monday" | Not covered | Covered |
| Storage engines | Every engine | SurrealMX and SurrealDS |
| Where it can be used | Any statement, including a block, a function body and an event | Only a transaction started with BEGIN or the begin RPC method |
| Retries under load | Only when another transaction writes a registered record | When another transaction writes anything the transaction read |
Use FOR UPDATE when a decision rests on specific records, when the check has to run inside a function or a single statement, or when the engine does not offer the serializable level. Use SERIALIZABLE when a decision rests on the result of a query, and keep those transactions short, because a transaction that reads a large table conflicts with any write to it.
ACID at a glance
| Property | In SurrealDB |
|---|---|
| Atomicity | A transaction's statements commit together or roll back together. |
| Consistency | Schema, permissions, and statement semantics apply on every commit; you define business invariants in SurrealQL and application code. |
| Isolation | Snapshot isolation on all storage backends, and serializable isolation on request on SurrealMX and SurrealDS; write conflicts abort on commit, and FOR UPDATE extends that check to records the transaction only reads. |
| Durability | Committed data persists according to your storage engine and sync settings - see File-backed storage and Deployment models. |
Some features deliberately step outside the triggering transaction's ACID boundary. ASYNC events, for example, run after commit in a separate transaction. Use them only when that trade-off is acceptable.