The same SurrealQL, APIs, and client SDKs work across embedded devices, single-node servers, distributed clusters, and managed instances - so you can change how the database runs without rewriting application code.
This page explains the available deployment options, storage engines, and how to choose the right architecture for your workload. For how the query engine and the storage engines fit together, see Architecture.
Deployment models summary
| Deployment model | Storage engine(s) | Scaling | High availability | Versioning (VERSION) | Best for | Managed option |
|---|---|---|---|---|---|---|
| Managed | Start (single-node) to Scale (multi-node cluster) | Vertical and horizontal (by plan) | Fully managed HA on Scale | Where enabled | Production without operating infrastructure | Yes |
| Single node | SurrealKV | Vertical | Filesystem backups | Where enabled (see engine docs) | Development and single-node production | Self-hosted (Community Edition) |
| Multi-node | Distributed storage; SurrealDS when self-hosted | Horizontal; distributed storage | High (replication across nodes and zones) | Where enabled on the storage tier | Large-scale production workloads | Scale plan; self-hosted Enterprise |
| Embedded | SurrealMX (memory), SurrealKV (on disk and in the browser) | Application-bound | Application-bound | Where enabled | Offline, edge, browser, and low-latency local apps | No |
Managed instances
Managed instances provide a fully managed deployment platform built on scalable, fault-tolerant infrastructure. SurrealDB operates the clusters, so your team does not have to.
Plans range from Start (single-node, vertically scalable instances) to Scale (multi-node clusters on distributed storage, minimum three compute units). Start is enough for many workloads; Scale is aimed at business-critical production where a single-node outage would stop the application and where operating HA yourself (Kubernetes, replication, patching, and backups) would otherwise consume platform team time. See Architecture and Pricing.
Features
Managed SurrealDB infrastructure
Vertical and horizontal scaling without rebuilding the cluster
High availability
Managed backups
Secure connectivity
Multi-node distributed architecture on the Scale plan
Production monitoring and operations
Best for
Managed infrastructure
Rapid production deployment
Scaling applications
SaaS platforms
Enterprise workloads
Benefits compared to self-hosting
| Feature | Self-hosted | Managed |
|---|---|---|
| Infrastructure management | Required | Managed |
| Backups | Manual | Managed |
| Scaling | Manual | Managed resize, no cluster rebuild |
| HA setup | Manual | Built-in |
| Upgrades | Manual | Managed |
| Cluster operations | Manual | Managed |
Single-node
Single-node deployments run SurrealDB as a standalone server process that stores its data on local disk, using SurrealKV (surrealkv://). This is the simplest and most widely used production architecture on disk. Before 4.0, SurrealDB also had a RocksDB engine (rocksdb://), which was the recommended engine at the time. See Moving a RocksDB database to SurrealKV.
Best for
Small to medium production workloads
Internal tooling
Development environments
Applications without horizontal scaling or built-in cluster fault tolerance
Limitations
Vertical scaling only
No built-in distributed fault tolerance
For setup examples, see Run a single-node, on-disk server.
Common deployment methods
CLI
surreal db start surrealkv://path/to/databaseDocker
docker run --rm \
  -p 8000:8000 \
  surrealdb/surrealdb:latest \
  start --user root --pass secret surrealkv:/data/database.db
See also Self-hosted for Docker, Kubernetes, and platform guides.
On-disk storage engine
SurrealKV is SurrealDB’s own LSM-backed storage engine, developed together with the database rather than as a third-party dependency, and it is the on-disk engine for single-node and embedded workloads. It has a comparatively small configuration surface and environment variable set, and the same engine runs in the browser over the Origin Private File System.
SurrealKV reached 1.0 before SurrealDB 4.0, and its on-disk format is stable from that release. New storage features are tried on SurrealKV first, such as temporal reads with the VERSION clause. From 3.3.0, the in-memory SurrealMX backend does not support versioned queries.
For the startup options of each engine, see Run a single-node, on-disk server and the surreal db start storage parameters.
Moving a RocksDB database to SurrealKV
Available since: v4.0.0
SurrealDB 4.0 has no RocksDB engine, so a server that ran on rocksdb:// moves to SurrealKV when it is upgraded. SurrealKV converts a RocksDB data directory written by SurrealDB the first time it opens it, so the move needs no export and import. Stop the server, take a copy of the data directory, and start it again with the surrealkv:// path in place of rocksdb://:
surreal db start --user root --pass secret surrealkv://path/to/databaseThe conversion reads the RocksDB tables, blob files and write-ahead log directly, and does not need RocksDB to be installed. A database that ran with versioning enabled keeps its versions and their timestamps, so start SurrealKV with versioned=true as well (for example "surrealkv://path/to/database?versioned=true") to keep answering VERSION queries for them. Any other database keeps the current value of each key, which is everything RocksDB stored for it.
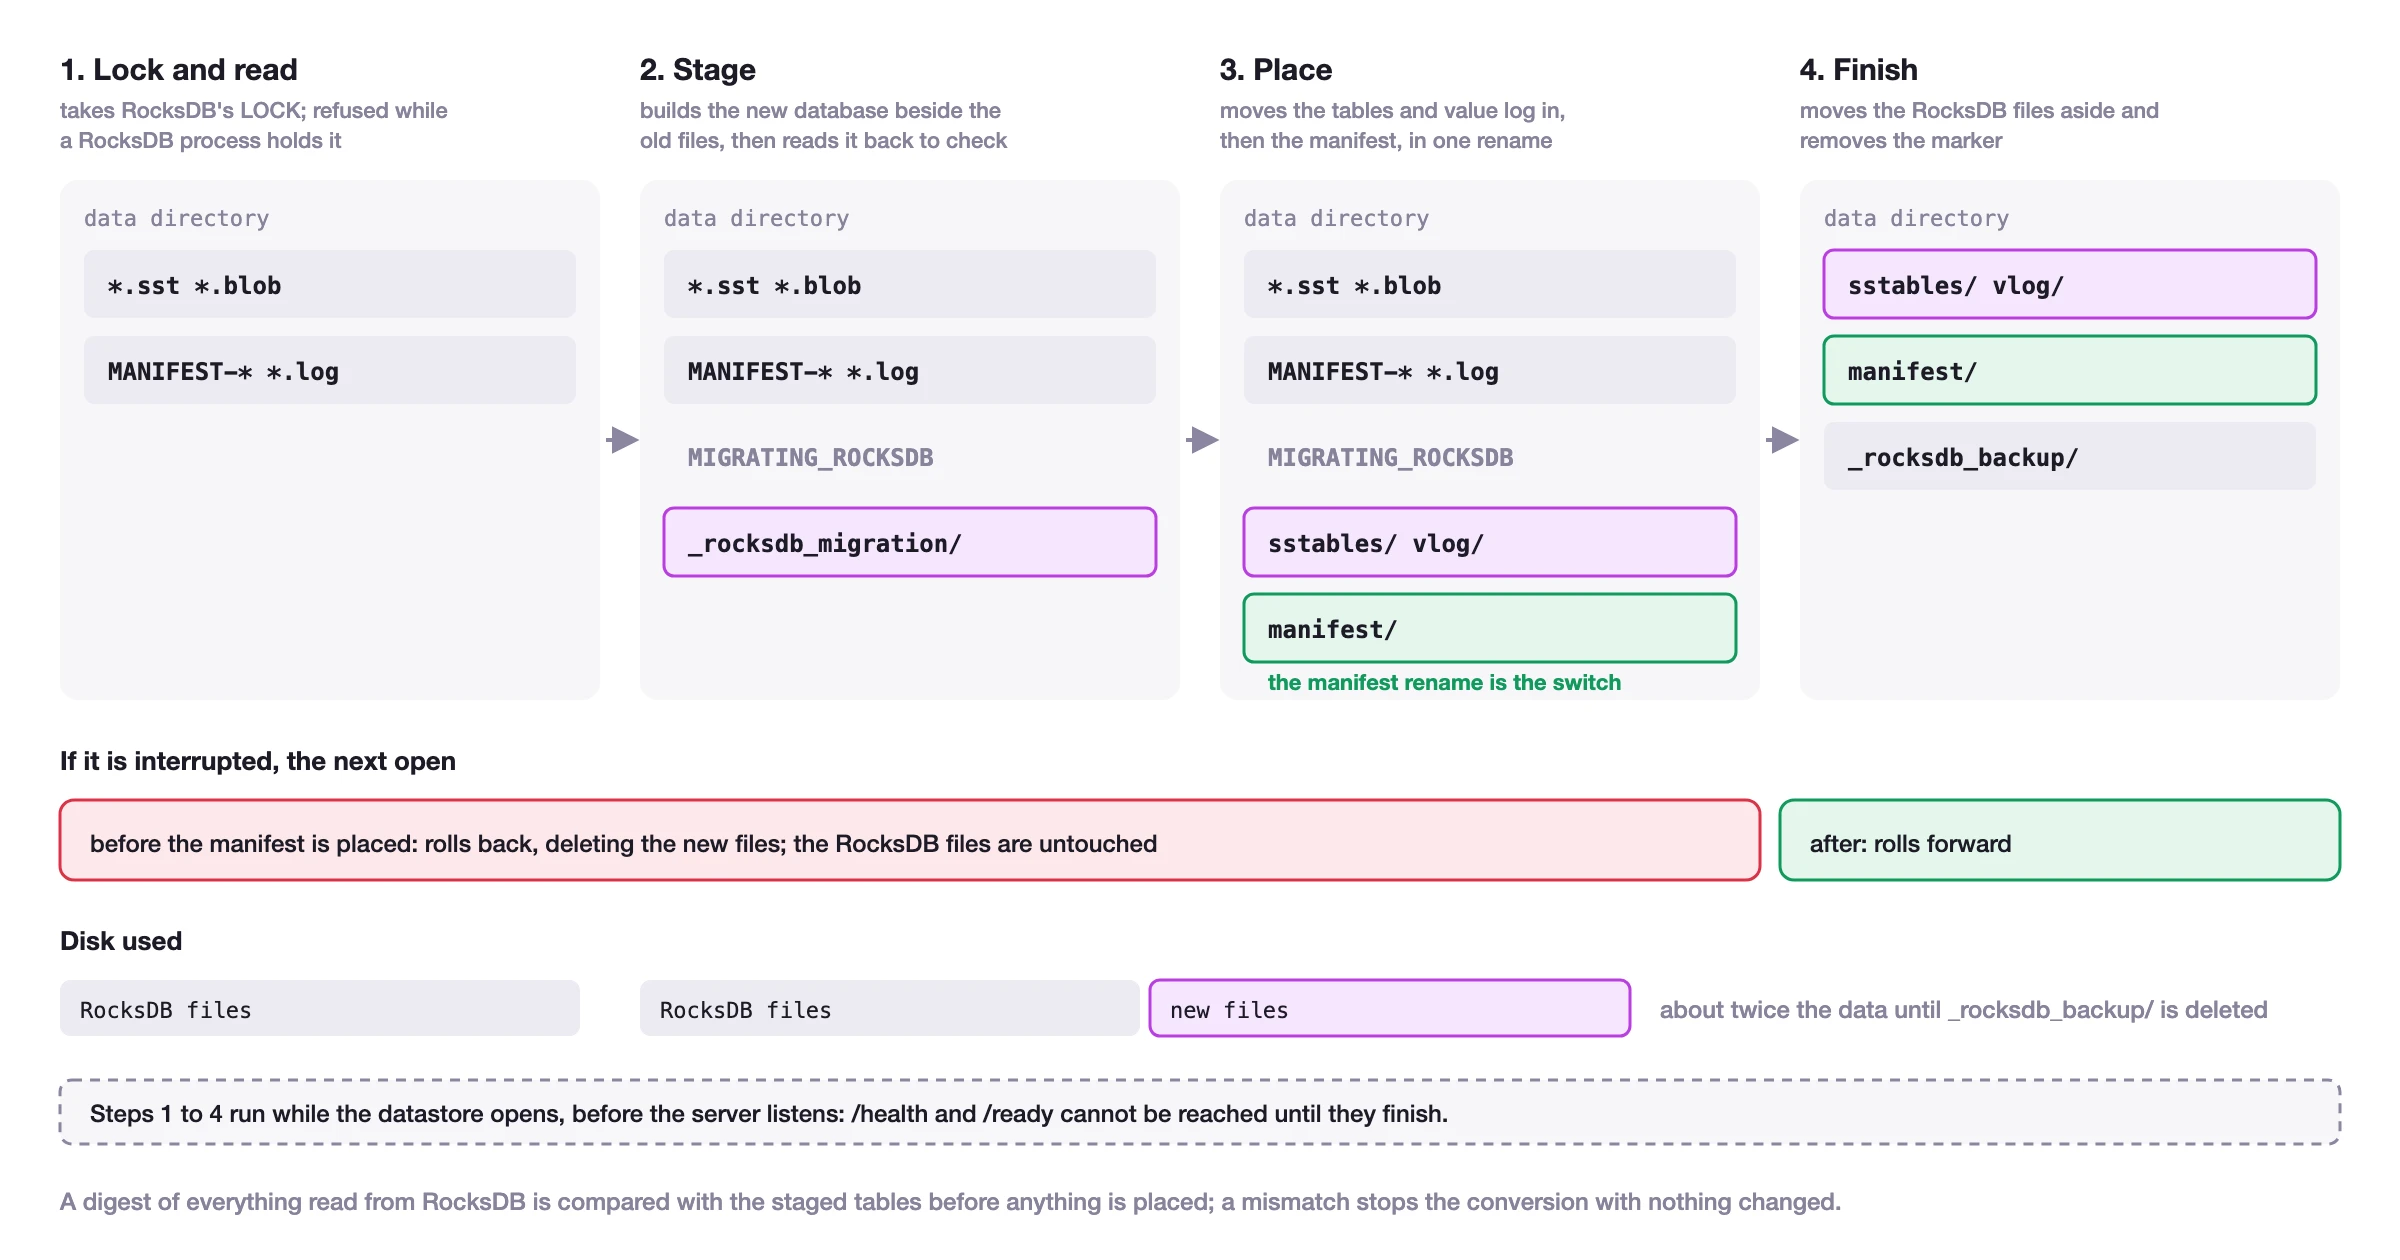
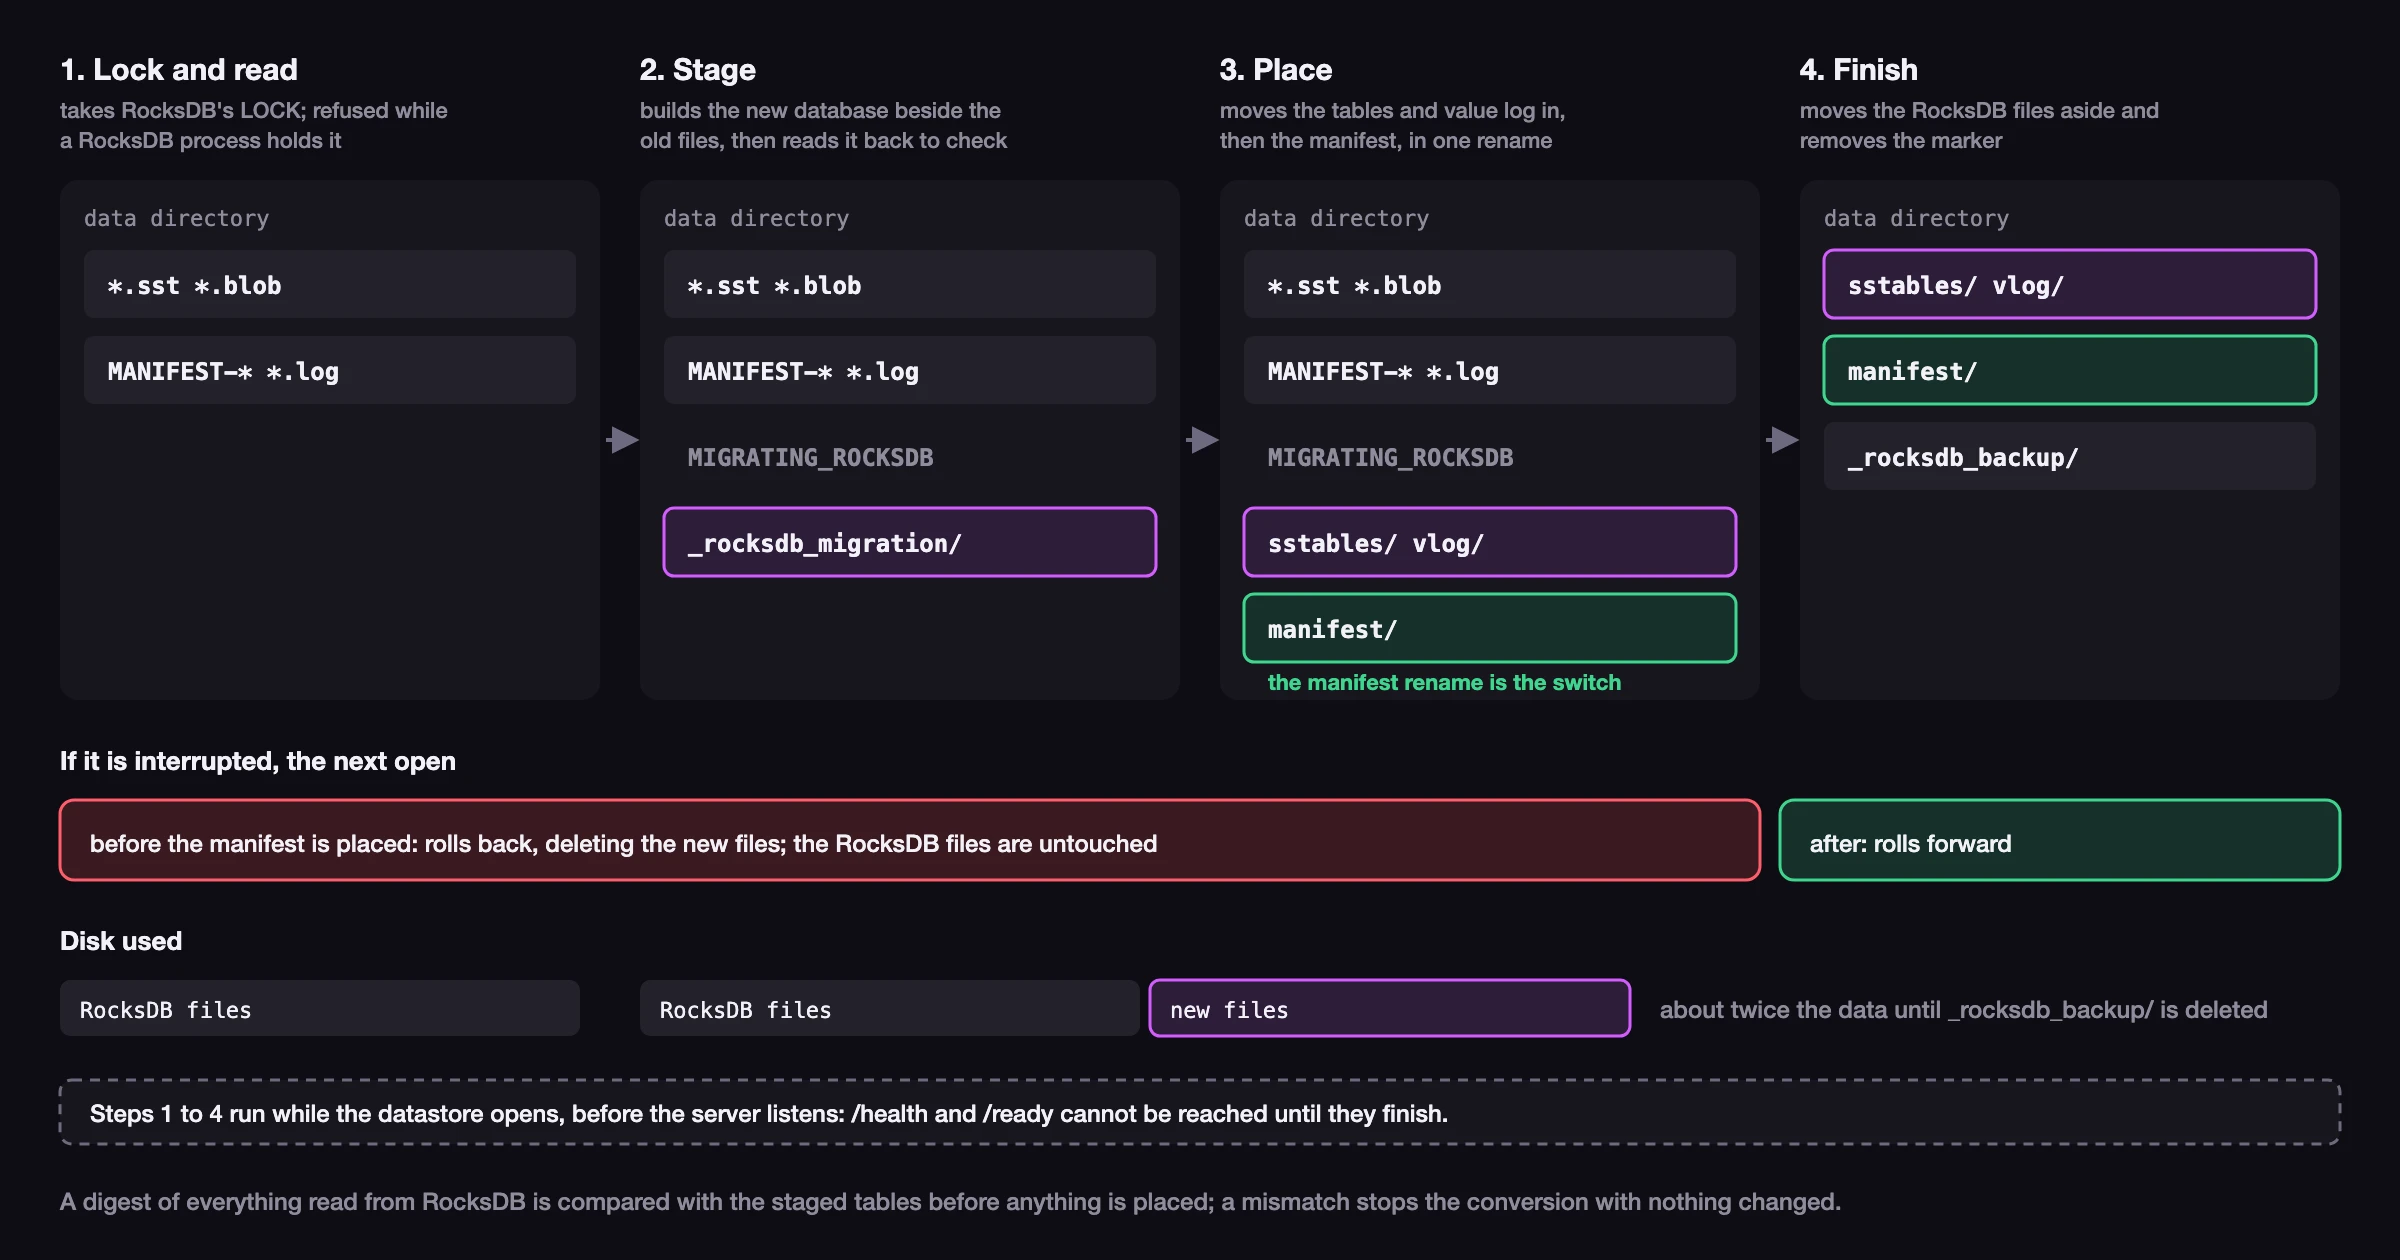
The conversion is one-way. The RocksDB files are moved to _rocksdb_backup/ inside the data directory, but that folder is not a rollback point, and RocksDB cannot open the converted directory. Keep the copy taken before the first start until the converted database has been checked.
A few more details apply:
No RocksDB process can have the directory open. The conversion takes the same lock that RocksDB takes, so it cannot start while a RocksDB process is running on the directory.
The directory needs room for about twice its current size. The new files are written to a staging folder beside the old ones, and the old files are kept afterwards.
An interrupted conversion is safe. Opening the directory again finishes it, or rolls it back if it had not yet reached the final step.
The server does not answer until the conversion finishes. The conversion runs while the datastore opens, before the server listens for connections, so
/healthand/readycannot be reached for as long as it takes, which grows with the size of the data. Give a liveness probe or a service manager enough time, so that it does not restart the server part-way through and start the conversion again.A
rocksdb://path still works. SurrealDB 4.0 acceptsrocksdb://as a deprecated spelling ofsurrealkv://, opens the directory with SurrealKV, and logs a warning. Change the path tosurrealkv://when convenient.
The diagram below shows the data directory at each step of the conversion.
SurrealKV databases from releases before 1.0 (v0.20 and v0.21) are converted in the same way when they are opened, and keep their versions. A SurrealKV database converted this way cannot be opened by an earlier release.
A RocksDB deployment that was tuned with SURREAL_ROCKSDB_* environment variables or path parameters needs its settings reviewed after the move, because SurrealKV reads none of them. The chart below shows each setting that the two engines read, one square for each, grouped by what it controls. RocksDB had 53 and SurrealKV has 10, not counting the versioned, retention and sync settings that both share. In the SurrealKV rows, a dashed square stands for a RocksDB setting that SurrealKV leaves to the engine, and the dashed square for RocksDB versioning shows how each engine keeps versions. Select a square to see its environment variable, or the reason no setting is needed. The SurrealKV environment variables reference describes each SurrealKV setting.
Best viewed full screen. Press Esc to come back to this page.
Converting ahead of time with skv
You do not need a separate tool to convert: starting SurrealDB on the old directory is enough. The skv tool that ships with SurrealKV is for when you want to convert the data ahead of time, before starting the new server. It writes the converted database to a new directory and leaves the original directory unchanged, so the earlier release can still start on it until you switch. Install the tool with cargo install surrealkv-cli, stop the server (the tool refuses a directory that a running server holds), convert the directory into a new one, and then start SurrealDB on the new directory. The tool converts a SurrealKV directory from an earlier release in the same way:
skv migrate path/to/rocksdb-database path/to/surrealkv-database
surreal db start --user root --pass secret surrealkv://path/to/surrealkv-database
The new directory needs as much free space as the data it holds. When SurrealDB starts on it, it still applies its own data migration and switches the datastore to the 4.0 record format, as it does for any datastore from 3.x.
Multi-node clusters
For high availability and horizontal scalability, SurrealDB supports distributed deployments backed by a distributed transactional storage layer built for large-scale clusters.
Architecture
In distributed deployments:
Several nodes serve queries, so query capacity grows as nodes are added
The storage layer manages replication, consensus, fault tolerance, and distributed transactions
Object-storage backing (rolling out on Scale) places transactional data in commodity object storage while frequently accessed data stays on local disk
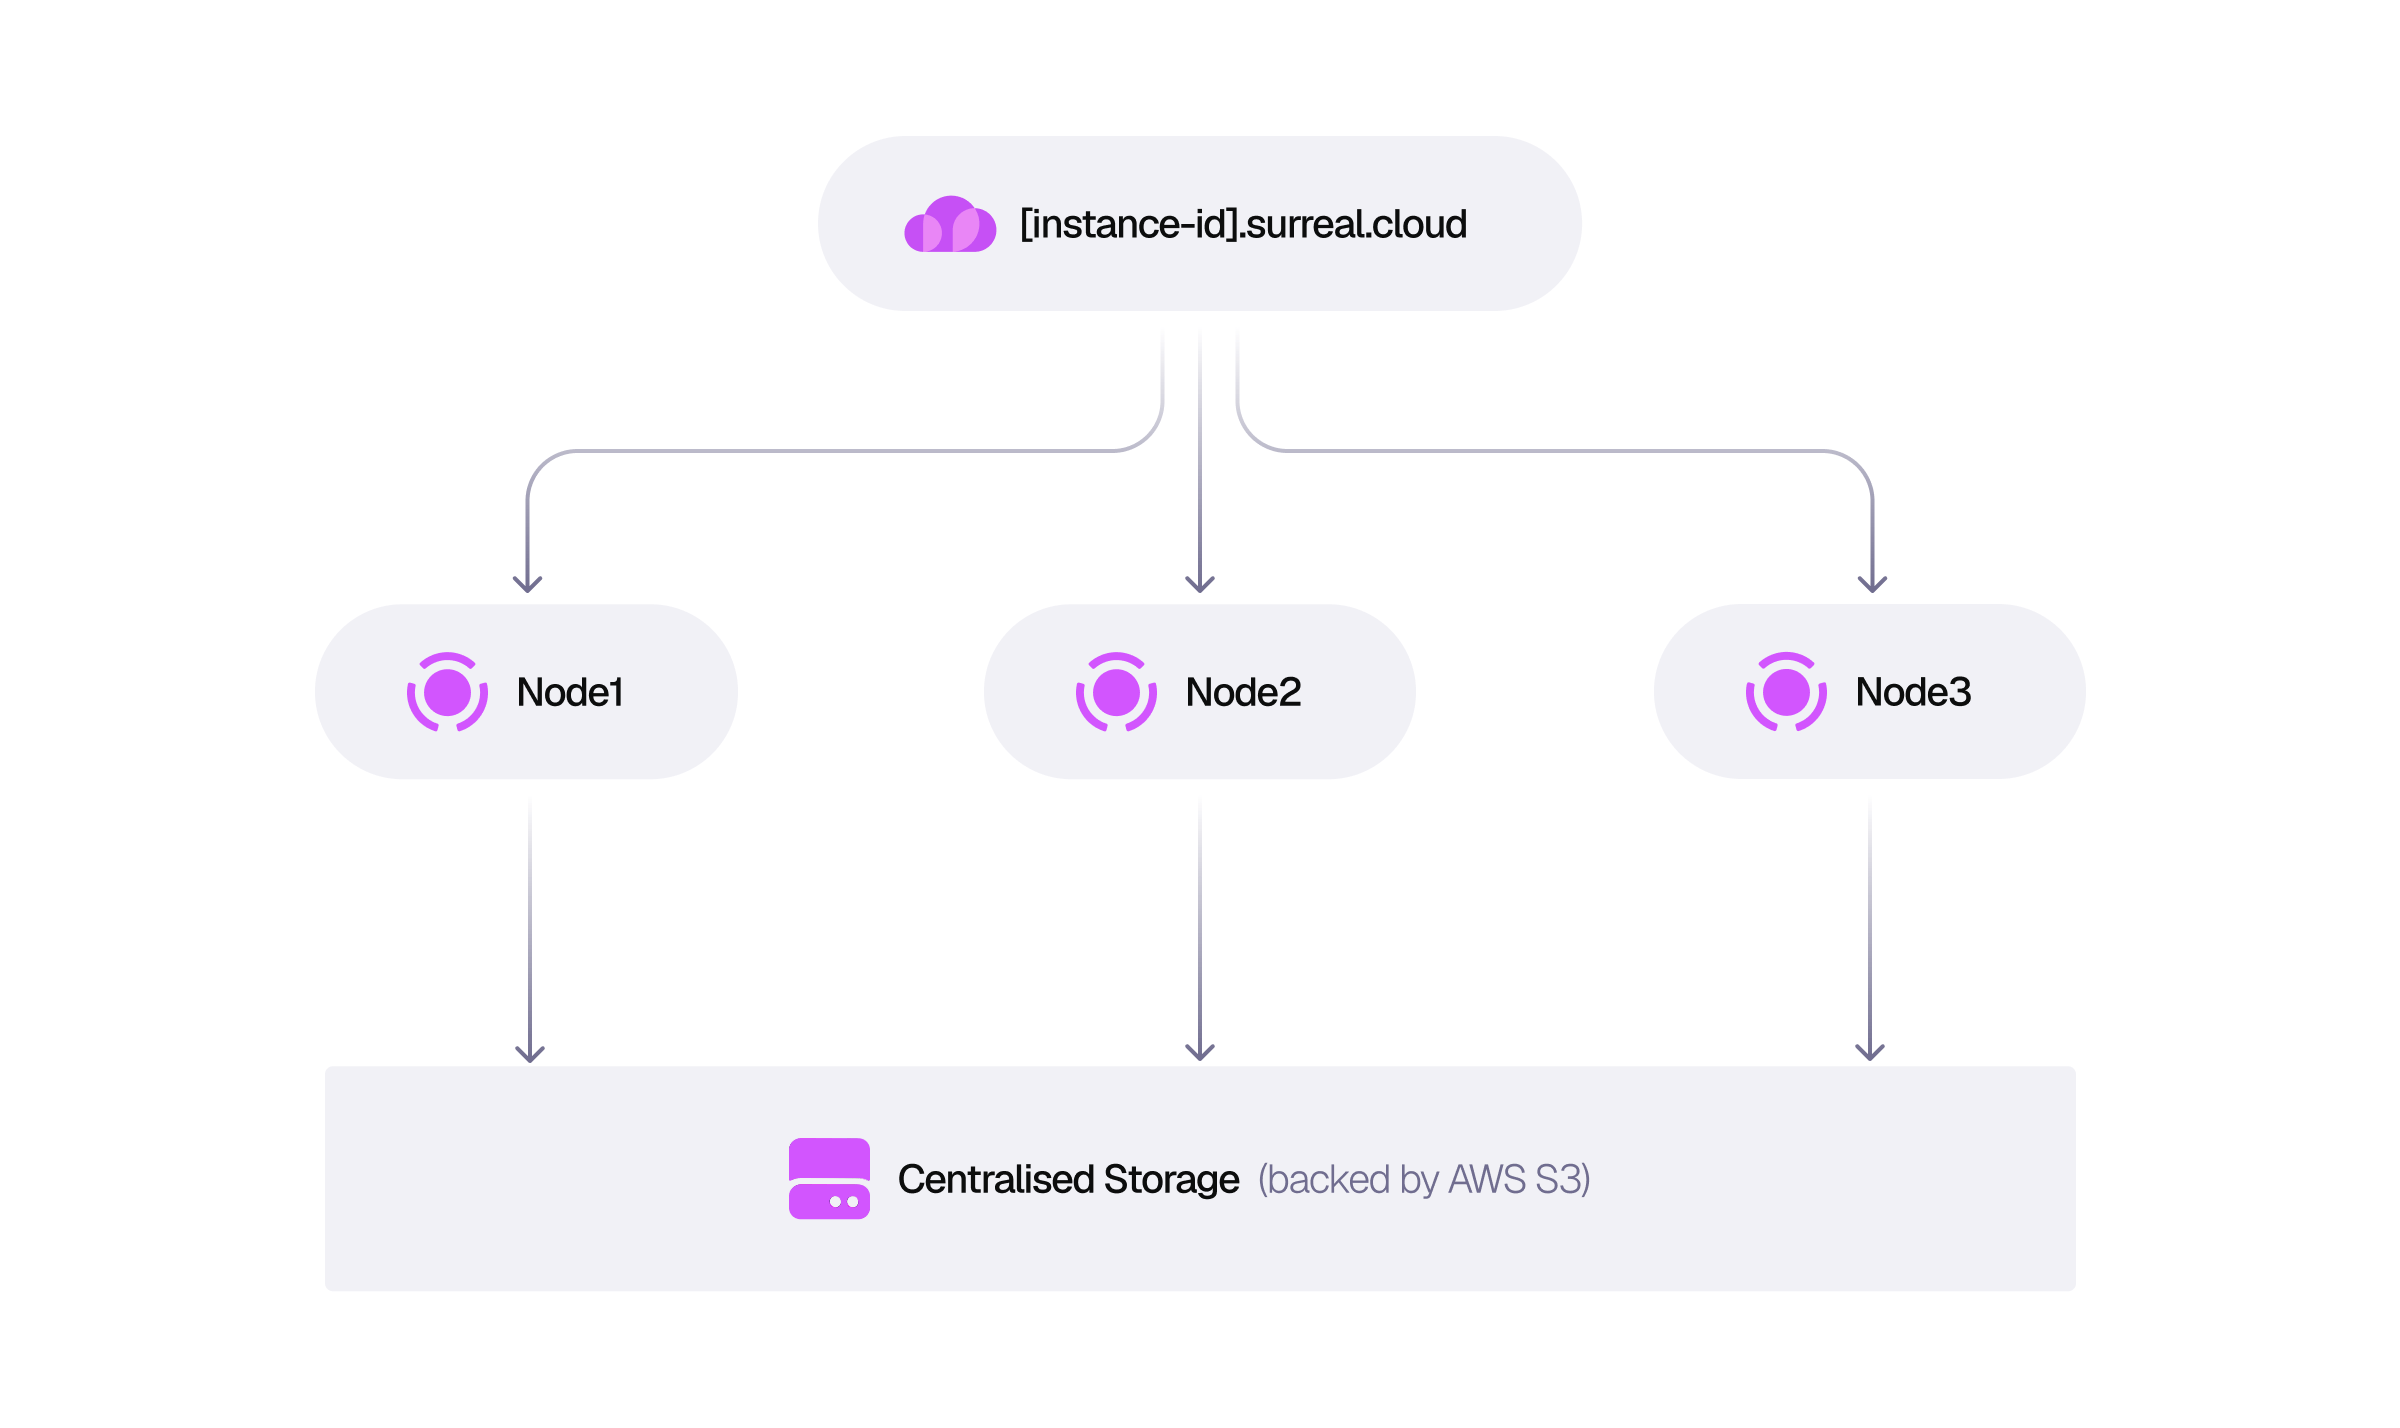
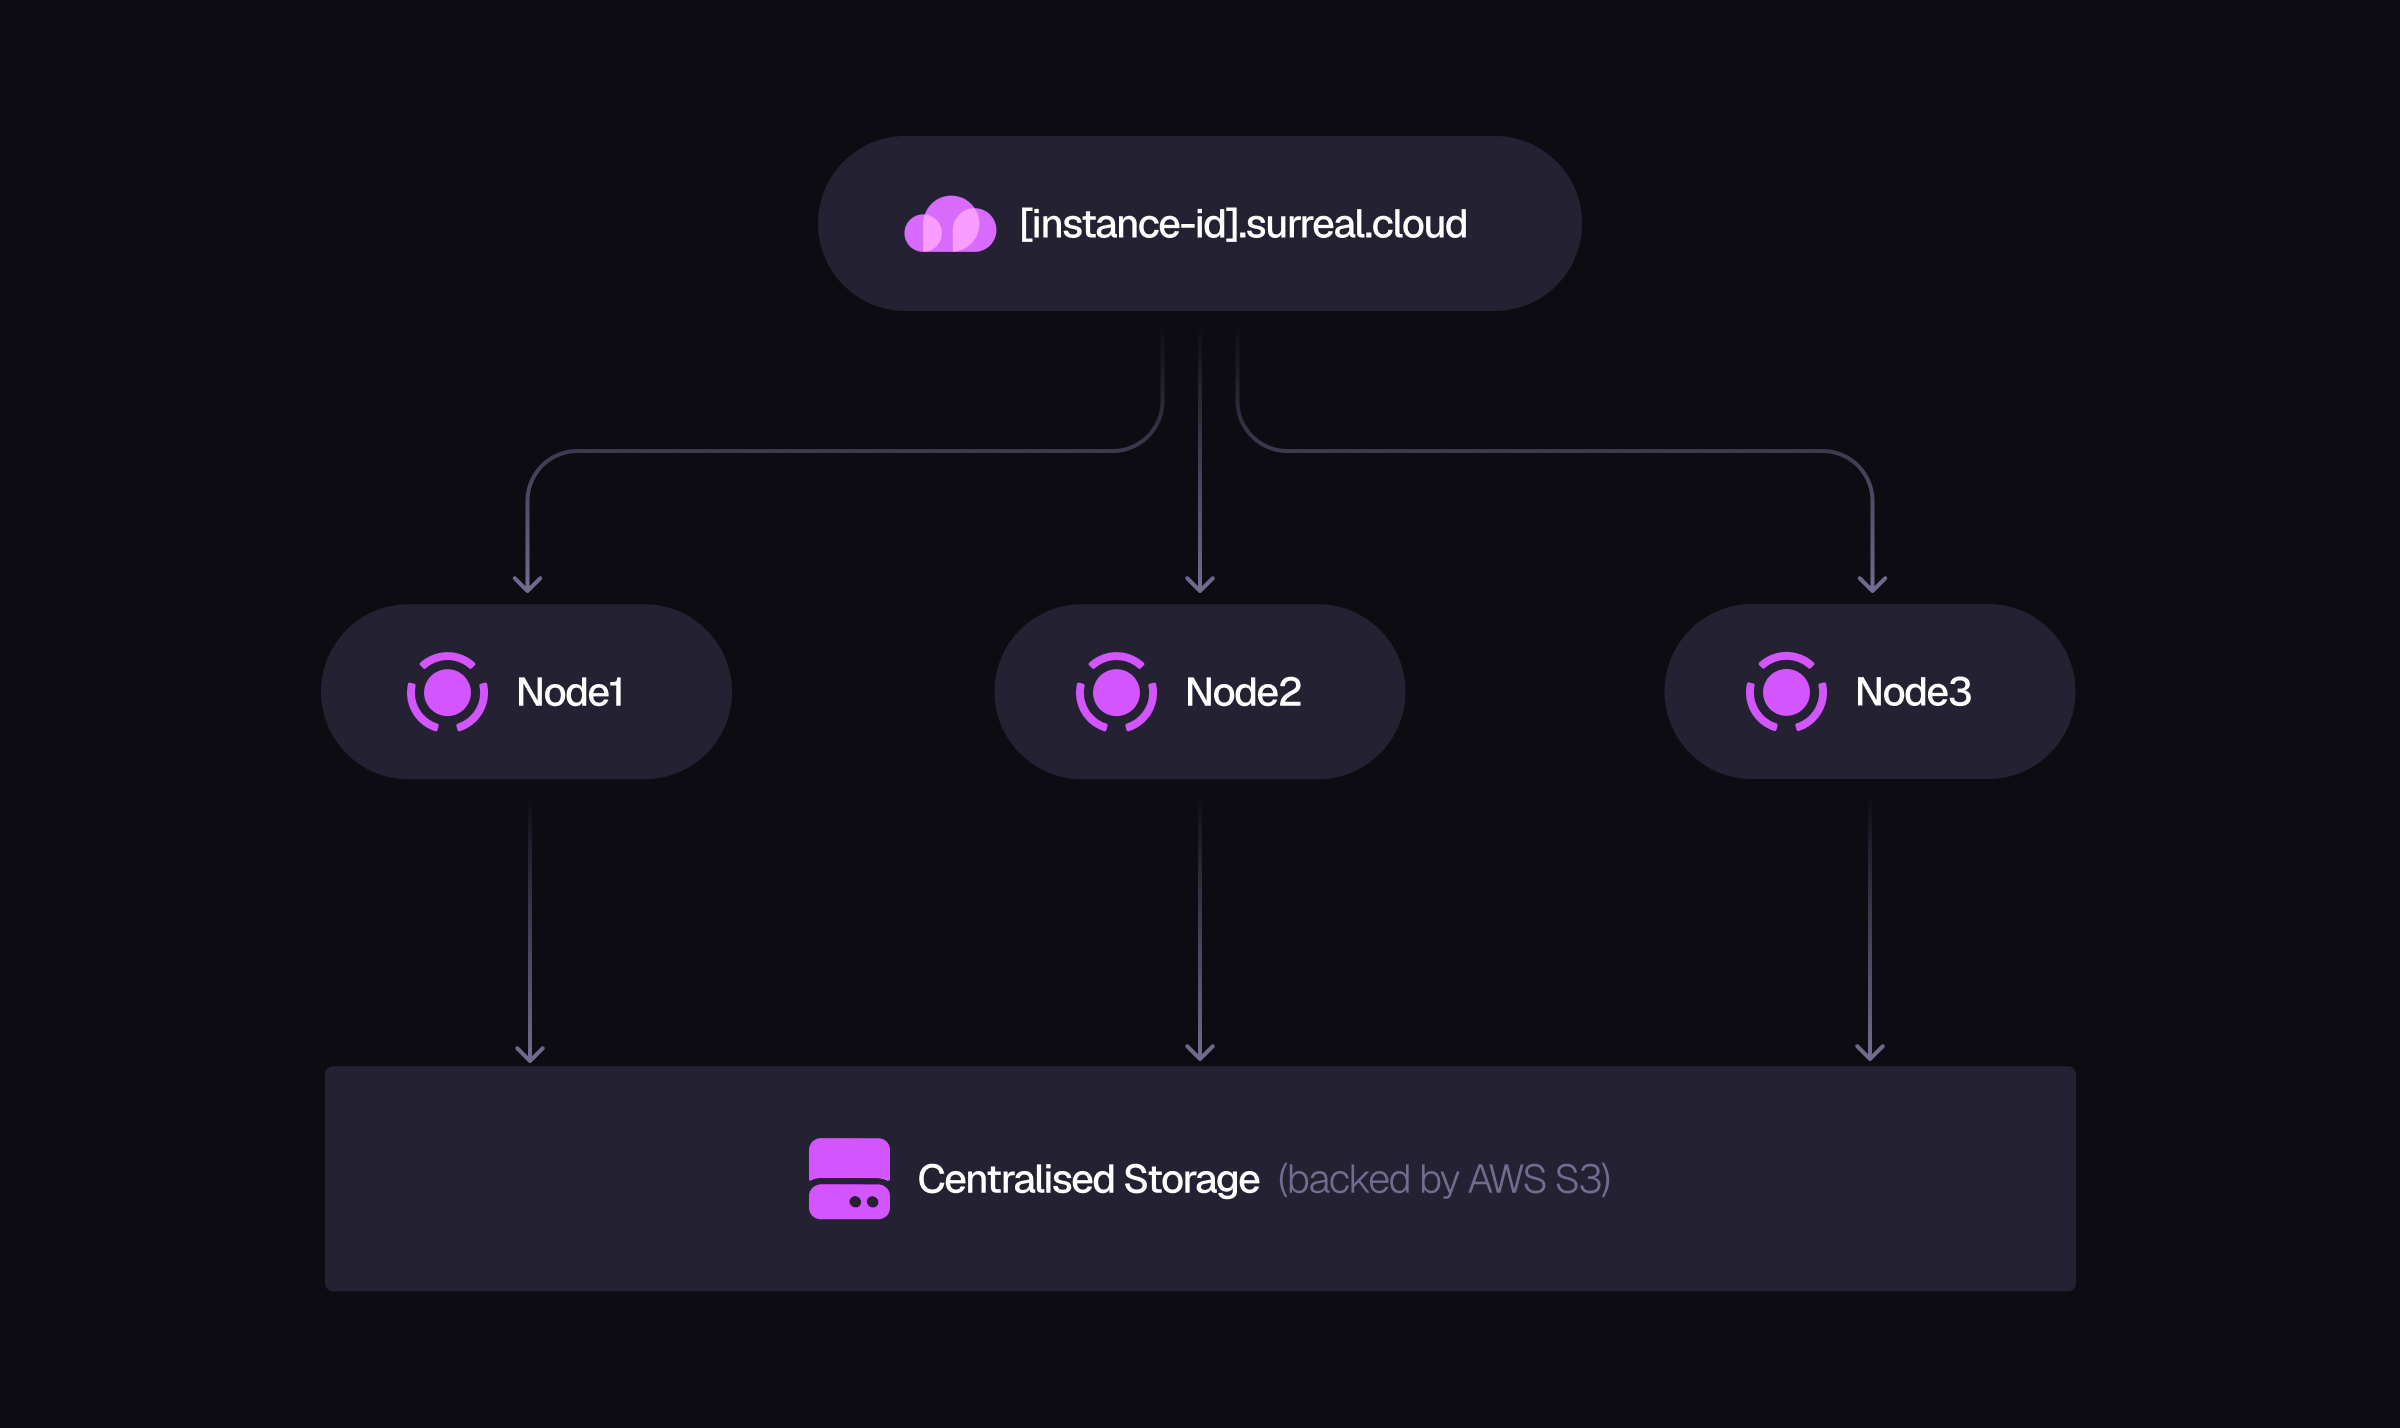
This architecture enables zero-downtime scaling, resilient clusters, high-throughput workloads, geographically distributed applications, and (as Scale features roll out) database branching, instant replication and recovery, and lower storage costs at scale.
For managed multi-node clusters, use the Scale plan on a managed instance. For self-hosted multi-node clusters, use SurrealDS in SurrealDB Enterprise, on Kubernetes with the operator or on your own machines. In SurrealDS, each node keeps a commit log on its local disk and all nodes keep the data in one object store bucket. See Run a multi-node cluster for how the model itself works.
Features
Horizontal scalability - Add nodes to add query and read capacity. Storage grows separately from the number of nodes.
Fault tolerance - Replication and consensus allow clusters to tolerate node failures.
ACID transactions - Transactions keep their guarantees across nodes. SurrealDS runs them with snapshot isolation by default, or with serializable isolation on request.
Large-scale storage - Designed for very large datasets and high-concurrency production workloads.
Best for
Enterprise deployments
High-availability applications
Systems that must keep serving when a zone fails
Large graph workloads
Real-time platforms
AI-native distributed systems
Operational considerations
Distributed deployments add cluster orchestration, node management, monitoring, and replication management. Teams that want distributed scalability without operating that stack should consider managed instances.
Embedded deployments
Embedded deployments run SurrealDB inside your application process without a separate database server. The query and storage layers share the process (and, in the browser, the same runtime), which removes network latency between your app and the database. This model suits edge computing, mobile and desktop software, offline-first apps, browser PWAs, and AI workflows that need minimal latency.
For language-specific setup, see Embedding SurrealDB and Storage engines.
Supported runtimes
SurrealDB supports embedded operation in Rust, Go, JavaScript / TypeScript, WebAssembly, Python, and .NET. Capabilities vary by SDK and storage backend - check the embedding guide for your language.
Storage options
In-memory (SurrealMX) - Default in-memory backend since SurrealDB 3.0, with optional snapshots or append-only persistence. From 3.3.0 it does not support versioned queries. See Run a single-node, in-memory server.
SurrealKV - The on-disk engine, the same as in single-node server deployments. It suits embedded and local-first in-process workloads where smaller resident memory and simple operational behaviour matter most. See File-backed storage.
SurrealKV in the browser - The same engine keeps a browser database in the Origin Private File System, for PWAs and local-first web apps. It runs in a dedicated worker. See the Wasm engine.
SurrealDB 4.0 removed the RocksDB and IndexedDB engines, and data in either is converted to SurrealKV when it is opened.
Choosing the right deployment model
Use a managed instance when
You want managed infrastructure instead of operating clusters yourself
You need production-ready HA quickly - especially on the Scale plan for multi-node fault tolerance
Your team prefers building applications over provisioning servers, Kubernetes, replication, and upgrade runbooks
Use single-node deployments when
Simplicity matters most
Scaling requirements are moderate
You run small-to-medium production workloads without cluster-level fault tolerance
Use multi-node deployments when
High availability is required
Workloads need horizontal scaling
Infrastructure spans multiple nodes or availability zones
For managed clusters, use the Scale plan. For self-hosted clusters, see SurrealDS.
Use embedded deployments when
You run on edge devices or in the browser
Offline operation is required
Minimising latency between app and database is critical
Next steps
Managed instances
Provision a managed SurrealDB instance with built-in monitoring, network access controls and operations tooling.
Self-hosted
Run SurrealDB on Docker, Kubernetes (AKS, EKS, GKE) or as a standalone binary with full control over storage and configuration.
Observability
Metrics, OTLP and Prometheus access, audit logs and slow-query logs for both Community and Enterprise editions.