The simplest way to search through your vector embeddings and data in SurrealDB is the brute force approach.
Brute force search compares a query vector against all vectors in the dataset to find the closest match. As this is a brute-force approach, you do not create an index for this approach.
The brute force approach for finding the nearest neighbour is generally preferred in the following use cases:
Small datasets / limited query vectors: For applications with small datasets, the overhead of building and maintaining an index might outweigh its benefits. In such cases, the brute force approach is optimal.
Guaranteed accuracy: Since the brute force method compares the query vector against every vector in the dataset, it guarantees finding the exact nearest vectors based on the chosen distance metric (like Euclidean, Manhattan, etc.).
Benchmarking models: The brute force approach can be used as a reference to help benchmark the performance of other approximate alternatives like HNSW or DISKANN.
While brute force can give you exact results, it's computationally expensive for large datasets.
In most cases, you do not need a 100% exact match, and you can give it up for faster, high-dimensional searches to find the approximate nearest neighbour to a query vector.
Vector indexes provide this kind of approximate search.
HNSW and DISKANN
SurrealDB offers two approximate graph indexes for k-nearest-neighbour search:
| Index | Best for | Storage |
|---|---|---|
HNSW (DEFINE INDEX … HNSW) | Low-latency ANN when the graph fits comfortably in memory with headroom for the bounded vector cache | In-memory hot graph + persistence |
DISKANN (DEFINE INDEX … DISKANN) (SurrealDB 3.1+) | Very large corpora where RAM cannot hold the full graph - full-precision vectors and graph stay in the key-value store and are paged through a bounded cache | Key-value-backed graph + bounded in-memory cache (64-bit platforms and WebAssembly builds) |
Both are proximity graph-style indexes. Queries use the same <|K, …|> KNN operator shapes; the optimiser picks the index when distances and types line up.
Vector search cheat sheet
HNSW - efficient in-memory approximation for high dimensions or large in-RAM datasets.
DISKANN - disk-oriented approximation for embeddings that exceed practical memory for a pure HNSW graph.
Brute force - when you do not define an index, when you want exact nearest neighbours, or when you pass an explicit distance function to the query that does not route to your index.
HNSW index
| Parameter | Default | Options | Description |
|---|---|---|---|
| DIMENSION | Size of the vector | ||
| DIST | EUCLIDEAN | EUCLIDEAN, COSINE, MANHATTAN | Distance function |
| TYPE | F32 | F64, F32, I64, I32, I16 | Vector type |
| EFC | 150 | EF construction | |
| M | 12 | Max connections per element | |
| M0 | 24 | Max connections in the lowest layer | |
| LM | 0.40242960438184466f | Multiplier for level generation. This value is automatically calculated with a value considered as optimal. |
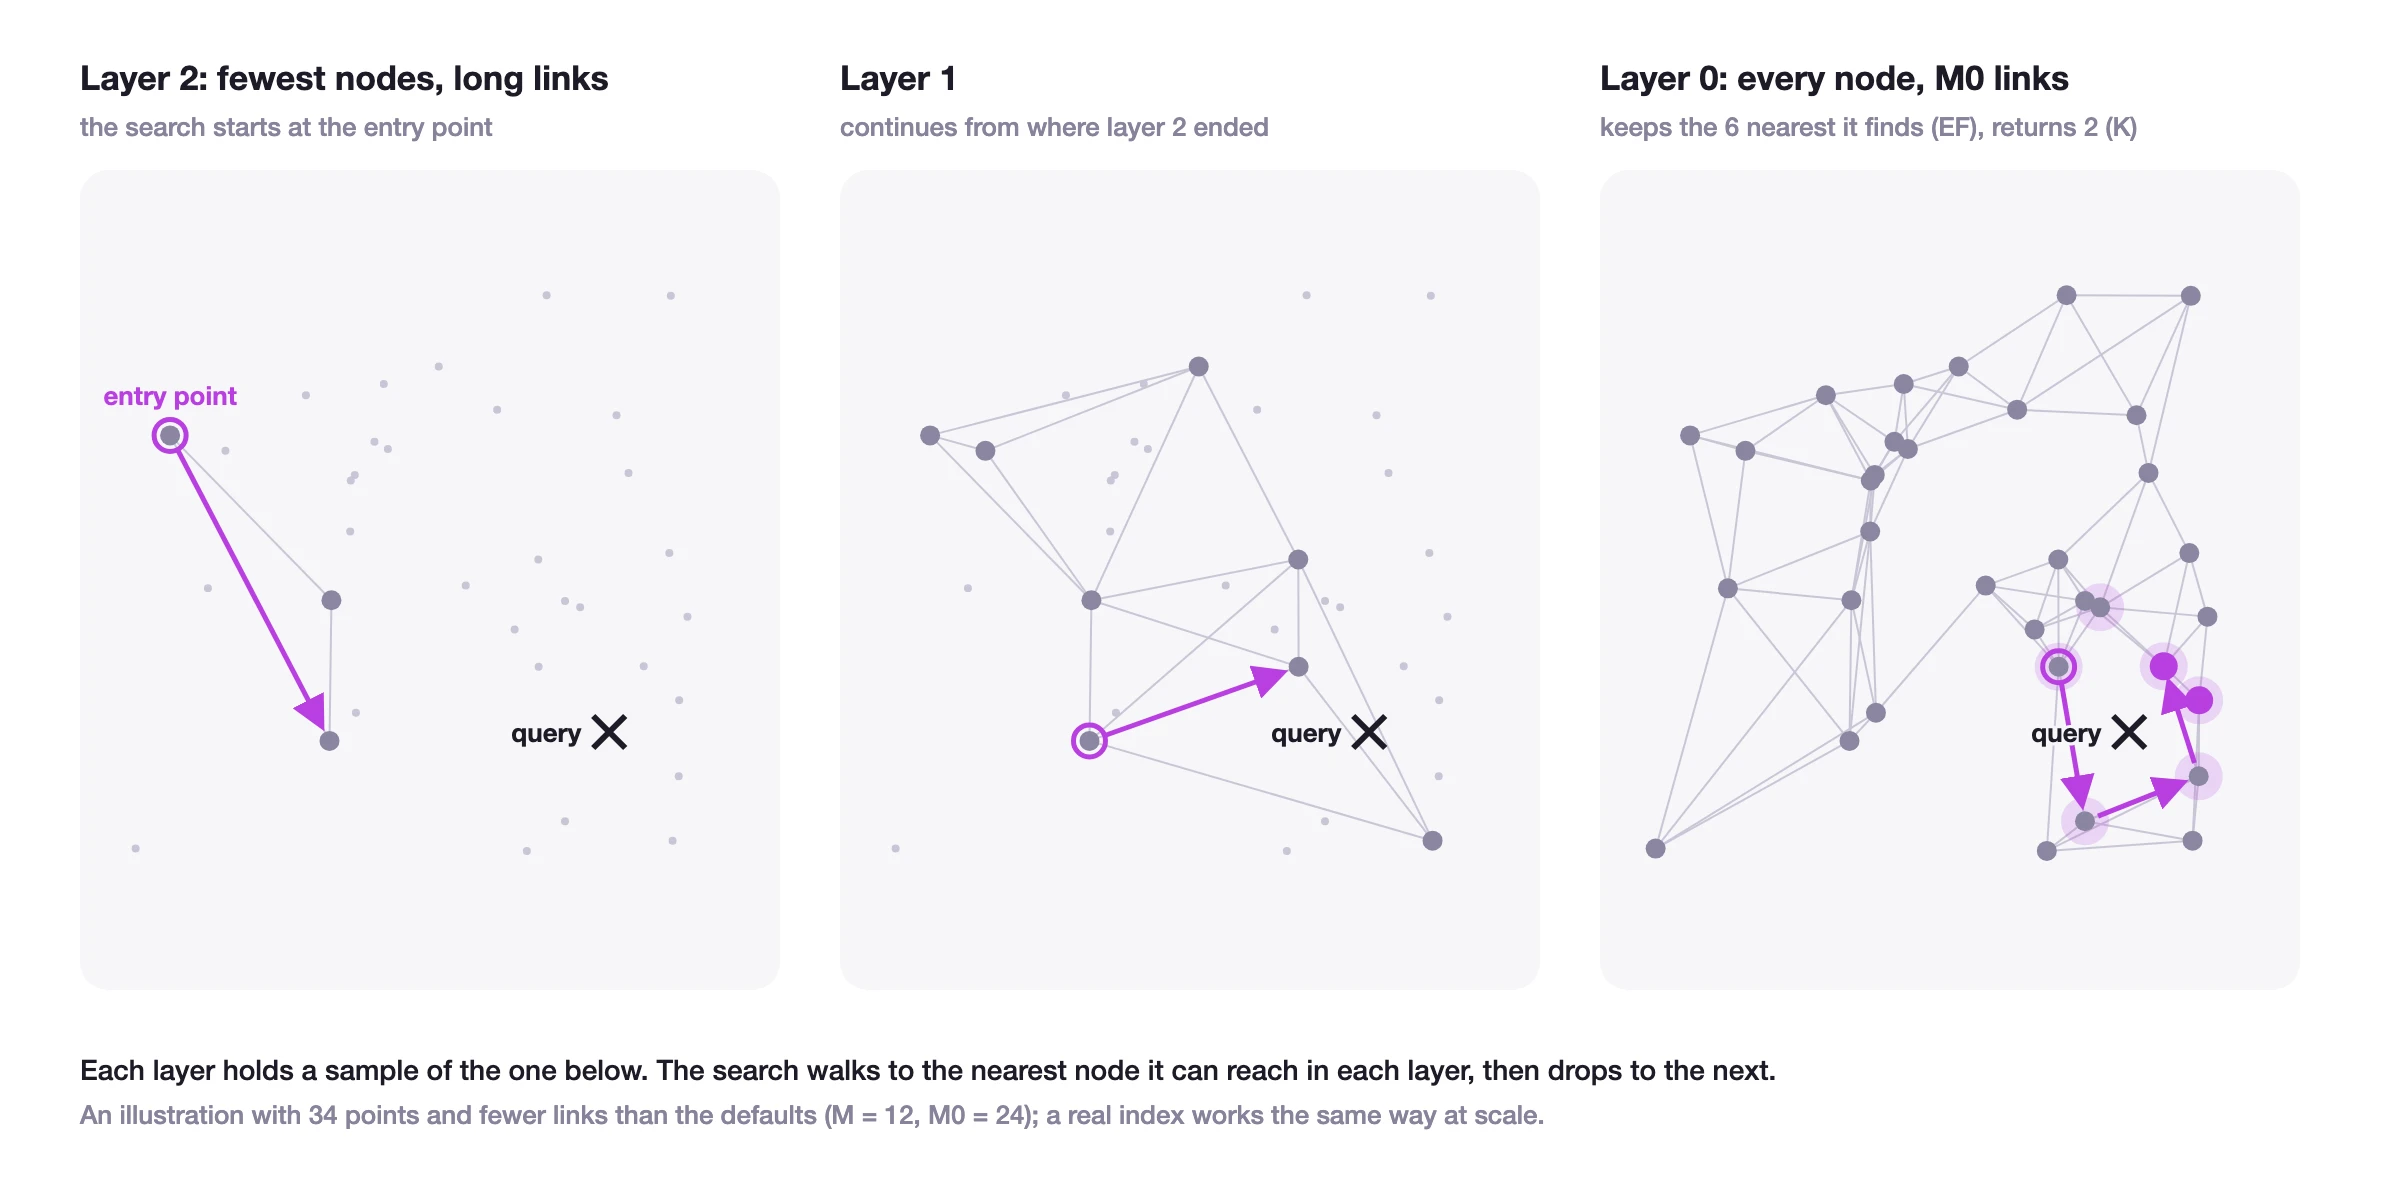
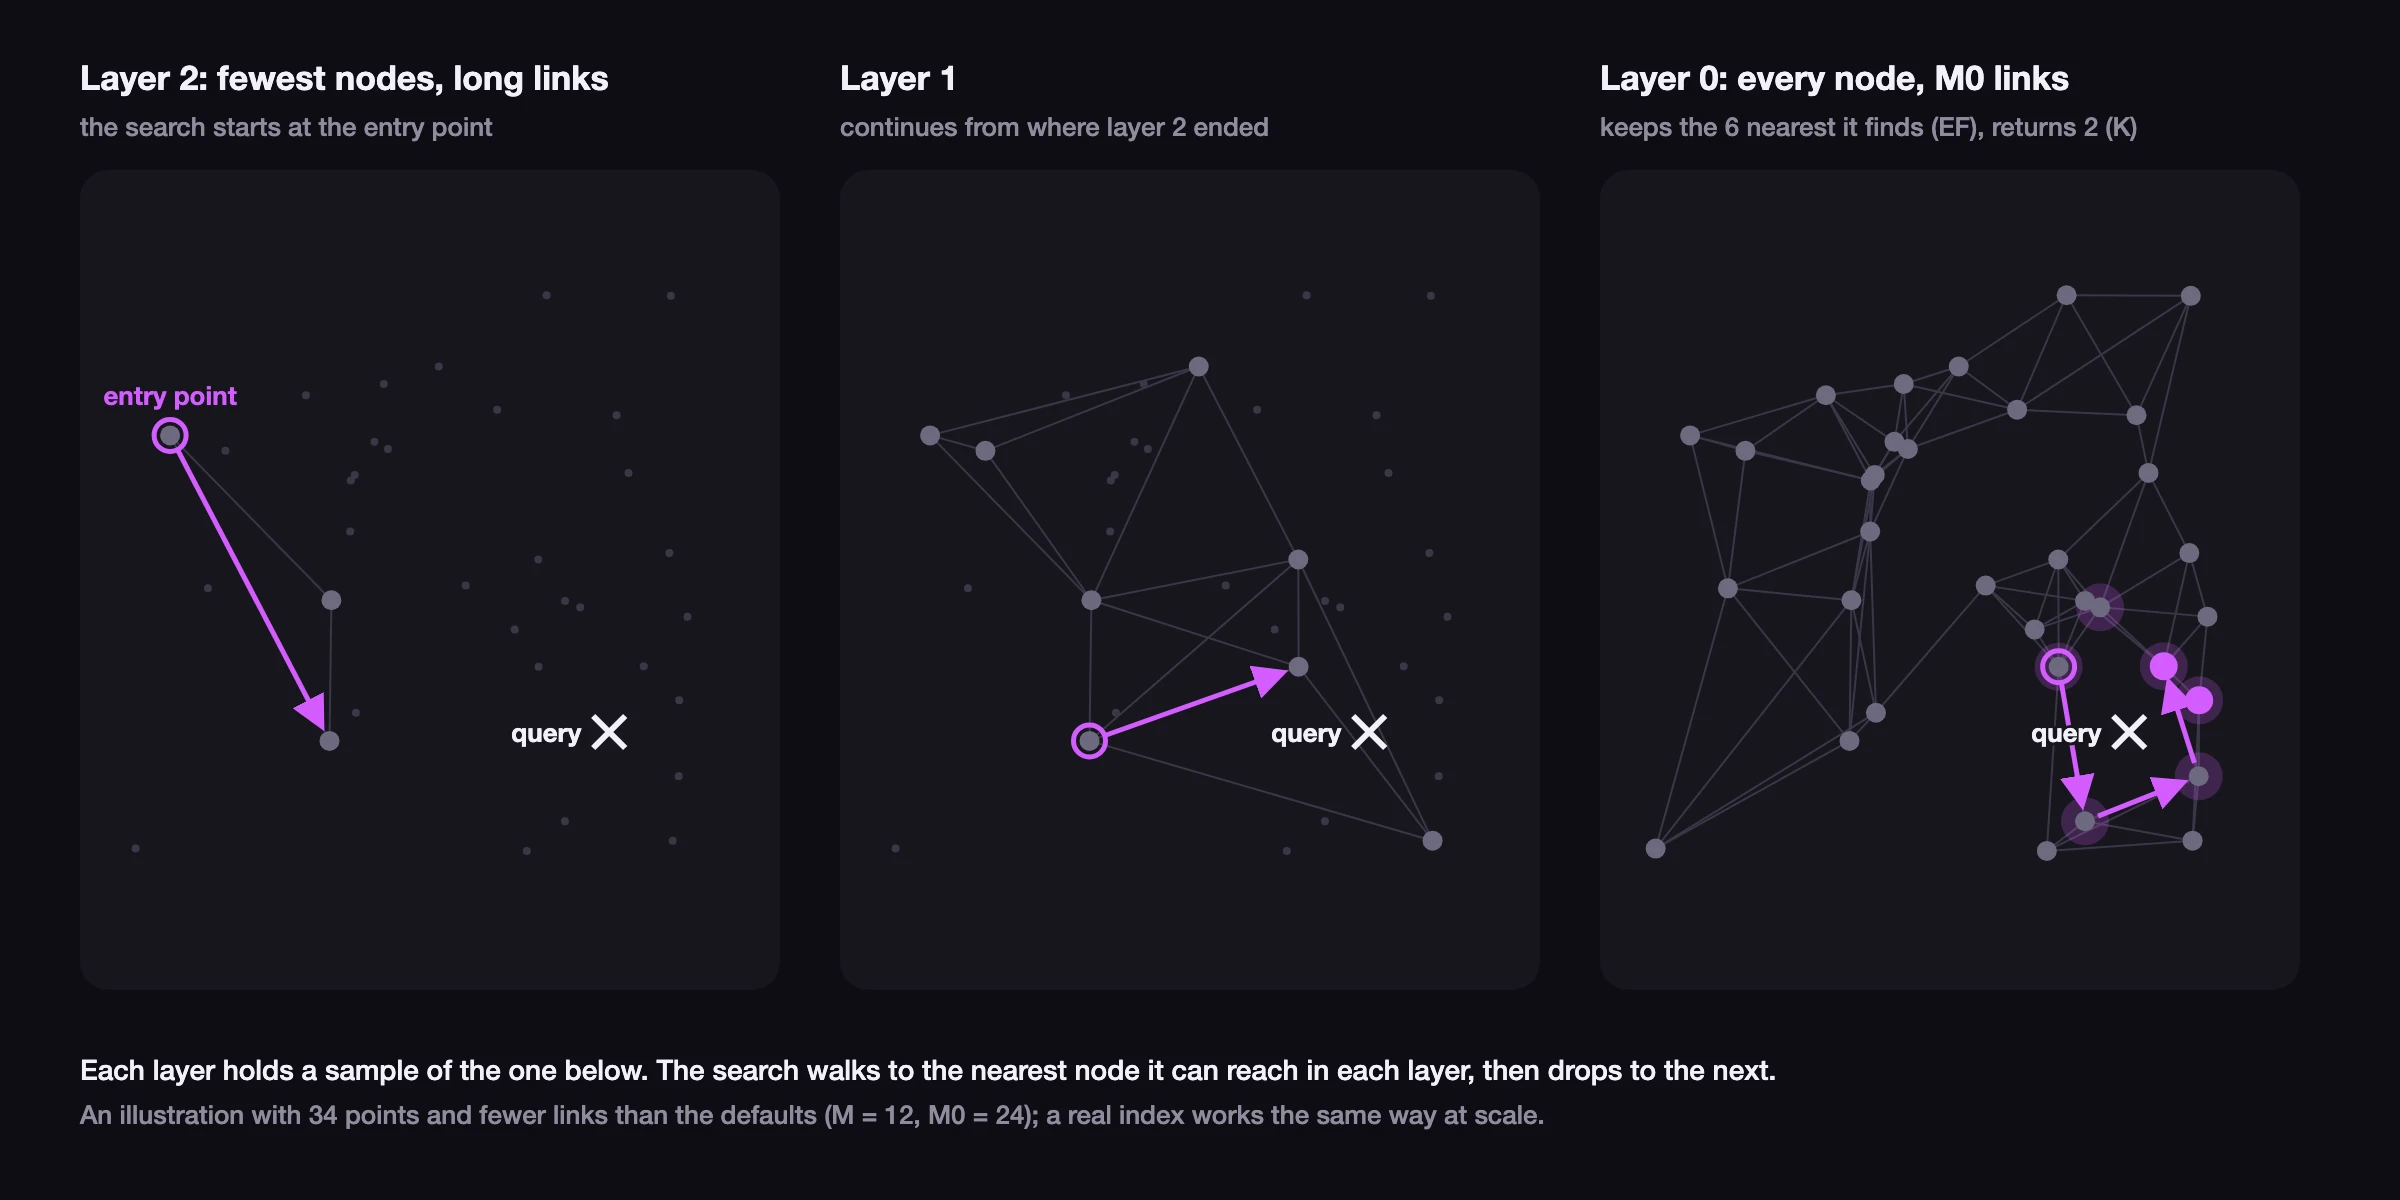
An HNSW index stores its graph in layers. Every vector is in layer 0, and each higher layer holds a smaller sample of the layer below, with links that span longer distances. M limits the links per node in the upper layers and M0 in layer 0. A search enters at the top, walks towards the query in each layer and drops to the next, then keeps the EF nearest nodes it finds in layer 0 and returns the K nearest of them:
Examples:
-- User statement:
DEFINE INDEX hnsw_idx ON pts FIELDS point HNSW DIMENSION 4;
-- Defaults to:
DEFINE INDEX hnsw_idx ON pts FIELDS point HNSW DIMENSION 4
    DIST EUCLIDEAN
    TYPE F32
    EFC 150
    M 12
    M0 24
    LM 0.40242960438184466f;
-- Users are strongly suggested not to set an LM value, as
-- it is computed based on other parameters. Only users
-- completely versed in the field should manually set it
For more details, see the DEFINE INDEX statement documentation.
DISKANN index
Available since: v3.1.0
| Parameter | Default | Options | Description |
|---|---|---|---|
| DIMENSION | Vector dimension | ||
| DIST | EUCLIDEAN | EUCLIDEAN, COSINE, INNER_PRODUCT, COSINE_NORMALIZED | Distance (narrower set than HNSW) |
| TYPE | F32 | F32, F16, I8, U8 | Element encoding (COSINE_NORMALIZED requires F32 or F16) |
| DEGREE | 64 | > 0 | Target maximum graph degree |
| L_BUILD | 100 | > 0 | Construction search-list size |
| ALPHA | 1.2 | DiskANN pruning parameter | |
| HASHED_VECTOR | off | Optional hash-stabilised vector keys |
DEFINE INDEX diskann_idx
  ON pts FIELDS point DISKANN DIMENSION 4 DIST COSINE TYPE F32;
DISKANN keeps its graph and full-precision vectors in the key-value store and answers queries through a bounded in-memory cache, so resident memory is bounded by the cache rather than by the dataset. (DISKANN does not apply product quantisation; per-vector size is governed only by the chosen TYPE.) The cache defaults to 256 MiB and is shared across all DISKANN indexes; cap it with SURREAL_DISKANN_CACHE_SIZE.
DISKANN is available on 64-bit platforms and in WebAssembly builds, including the Wasm engine in a browser. Other 32-bit platforms, such as 32-bit x86 and 32-bit Arm, use HNSW instead. See DEFINE INDEX → DISKANN for the full memory model.
Querying
DEFINE INDEX hnsw_idx ON pts FIELDS point HNSW DIMENSION 4;

LET $vector = [2,3,4];
SELECT
    id,
    vector::distance::knn() as dist  -- distance from $vector
                                     -- knn reuses the value computed during
                                     -- the query, in this case the euclidean
                                     -- distance
FROM pts
WHERE point
    <|2|>  -- return 2, in this case using the distance function defined in the
           -- index: euclidean
    $vector;
With a DISKANN index defined on point, the same <|K, EF|> approximate form applies; the second number bounds the dynamic candidate list for search (see the KNN operator).
| Functions | |
|---|---|
vector::distance::knn() | reuses the value computed during the query |
vector::distance::chebyshev(point, $vec) | |
vector::distance::cosine(point, $vec) | 1 - vector::similarity::cosine(point, $vec) |
vector::distance::euclidean(point, $vec) | |
vector::distance::hamming(point, $vec) | |
vector::distance::manhattan(point, $vec) | |
vector::distance::minkowski(point, $vec, 3) | third param is 𝑝 |
vector::distance::mahalanobis(point, $vec, $cov) | third param is the covariance matrix, not an index distance |
vector::similarity::cosine(point, $vec) | |
vector::similarity::jaccard(point, $vec) | |
vector::similarity::pearson(point, $vec) | |
vector::similarity::spearman(point, $vec) |
WHERE statement
Query | HNSW index | DISKANN index |
|---|---|---|
<|2|> | uses distance function defined in index | same when the index distance matches |
<|2, EUCLIDEAN|> | brute force method | brute force method |
<|2, COSINE|> | brute force method | brute force method |
<|2, MANHATTAN|> | brute force method | brute force method |
<|2, MINKOWSKI, 3|> | brute force method (third param is 𝑝 ) | brute force method |
<|2, CHEBYSHEV|> | brute force method | brute force method |
<|2, HAMMING|> | brute force method | brute force method |
<|2, 10|> | second param is effort* | same approximate form - second value bounds the candidate list |
\* effort - for HNSW and DISKANN, the second number in <|K, N|> tells the engine how far to search along the graph. Both algorithms are approximate and may miss some vectors.
ORDER BY statement
From SurrealDB 4.0, an HNSW or DISKANN index also answers ORDER BY vector::distance::<metric>(point, $vec) LIMIT K when the function matches the distance the index was defined with, so ORDER BY vector::distance::euclidean(point, $vec) LIMIT 2 uses the hnsw_idx index above. The search runs with the same width as <|2|>, which is the larger of K and the index's EFC for HNSW or L_BUILD for DISKANN. See ordering by distance for the conditions.
Distance under JACCARD and PEARSON
Available since: v4.0.0
From SurrealDB 4.0, a KNN query on an index defined with DIST JACCARD or DIST PEARSON ranks records by the distance 1 - similarity, so the nearest vector comes first. Before 4.0, these two metrics ordered the results by the similarity itself. An existing HNSW index with either metric was built on the earlier ordering and must be rebuilt with REBUILD INDEX before it returns nearest-first results.
Rebuilding an HNSW or DISKANN index also makes KNN queries with a selective filter faster, as the rebuilt index lets those queries score candidates from the index. The upgrade page lists which indexes to rebuild and when: see upgrading from 3.3 to 4.0.
Notes
Verify index utilisation in queries using the
EXPLAIN FULLclause. E.g:SELECT id FROM pts WHERE point <|10|> [2,3,4,5] EXPLAIN FULL;𝑝 values: (more about 𝑝 in Minkowski distance)
20 = 1 → manhattan/diamond ◇
21 = 2 → euclidean/circle ○
22 = 4 → squircle ▢
2∞ = ∞ → square □