Before SurrealDB version 3.0.0, the FULLTEXT ANALYZER clause used the syntax SEARCH ANALYZER.
Just like in other databases, SurrealDB uses indexes to help optimise query performance. An index can consist of one or more fields in a table and can enforce a uniqueness constraint. If you don't intend for your index to have a uniqueness constraint, then the fields you select for your index should have a high degree of cardinality, meaning that there is a high amount of diversity between the data in the indexed table records.
Requirements
You must be authenticated as a root owner or editor, namespace owner or editor, or database owner or editor before you can use the
DEFINE INDEXstatement.You must select your namespace and database before you can use the
DEFINE INDEXstatement.
Statement syntax
DEFINE INDEX [ OVERWRITE | IF NOT EXISTS ] @name
    ON [ TABLE ] @table
    [ FIELDS | COLUMNS ] @fields
    [ @special_clause ]
    [ COMMENT @string ]
    [ CONCURRENTLY ]
    [ DEFER ]
The @special_clause part of the statement is an optional part in which an index can be declared for special usage such as guaranteeing unique values, full-text search, and so on. The available clauses are:
UNIQUE [ NULLS NOT DISTINCT ]
| COUNT [ WHERE @condition ]
| FULLTEXT ANALYZER @analyzer [ BM25 [(@k1, @b)] ] [ HIGHLIGHTS ]
| HNSW DIMENSION @dimension [ TYPE @type ] [ DIST @distance ]
    [ EFC @efc ] [ M @m ]
| DISKANN DIMENSION @dimension [ TYPE @type ] [ DIST @distance ]
    [ DEGREE @degree ] [ L_BUILD @l_build ]
    [ ALPHA @alpha ] [ HASHED_VECTOR ]
| SPATIAL
An index has at most one of these clauses. From SurrealDB 4.0, a statement that gives two of them, or the same one twice, is a parse error such as Cannot combine UNIQUE with COUNT or UNIQUE is given twice, rather than keeping only the last one.
Index types
SurrealDB offers a range of indexing capabilities designed to optimise data retrieval and search efficiency.
Standard (non-unique) index
An index without any special clauses allows for the indexing of attributes that may have non-unique values, facilitating efficient data retrieval. Non-unique indexes help index frequently appearing data in queries that do not require uniqueness, such as categorization tags or status indicators.
The following example creates a non-unique index for an age field on a user table.
-- optimise queries looking for users of a given age
DEFINE INDEX userAgeIndex ON TABLE user FIELDS age;
Besides = and comparisons such as > and <, a standard index is used for a range with IN, and for a string prefix with string::starts_with(). Before SurrealDB 3.3.1, these two scanned the whole table.
-- Both use the index from 3.3.1
SELECT * FROM user WHERE age IN 18..30;
SELECT * FROM user WHERE string::starts_with(name, 'Ann');
Only the function-call form is read as a prefix. The method form name.starts_with('Ann') returns the same records, but scans the table.
Indexing an array field
On a field that holds an array, a standard index has one entry for each element. A condition still compares the whole value, so with tags = ['a', 'b'], the condition tags = 'a' is false and tags = ['a', 'b'] is true, with or without the index. To find the records whose array holds an element, use CONTAINS or CONTAINSANY and index the elements with tags.*:
DEFINE INDEX post_tags ON post FIELDS tags.*;

SELECT * FROM post WHERE tags CONTAINS 'a';
SELECT * FROM post WHERE tags CONTAINSANY ['a', 'c'];
An index declared as FIELDS tags is not used for CONTAINS, and the query scans the table instead. The field may still hold a string written before its type was declared, and CONTAINS on a string looks for a substring, which an element lookup cannot find. A tags.* index finds such a string for the plain form tags CONTAINS 'a', as described in Array-element composite indexes. The form tags.* CONTAINS 'a' takes each element of the field, and a string is indexed whole, so it does not find a substring inside a string.
Before SurrealDB 3.3.1, the query planner treated a FIELDS tags index on an array field as if each record held a single value, so a query could return different records with the index than without it. count() with tags = 'a' counted the records whose array held 'a', tags = ['a', 'b'] returned nothing, a range such as tags > 'a' could return a record twice, and ORDER BY tags followed the order of the index entries. From 3.3.1 these return the same results as without the index on a field whose type is an array, such as array<string> or option<array<string>>, and the index does not need to be rebuilt. A field with no declared type, or a type that also allows a value that is not an array, keeps the earlier behaviour. So does a server started with SURREAL_PLANNER_STRATEGY set to compute-only.
Indexing a computed value
The field path in FIELDS can end with one or more method calls. The index then stores the result of the methods for each record, and updates it when the record changes. This lets a query that filters on a transformed value, such as a lowercase name, use an index:
DEFINE INDEX product_kind ON product FIELDS kind.trim().lowercase();

CREATE product:1 SET kind = ' Banana ';
CREATE product:2 SET kind = 'apple';

SELECT id FROM product WHERE kind.trim().lowercase() = 'banana';[
{
id: product:1
}
]Adding EXPLAIN to the query shows that it reads the index. The IndexScan operator names product_kind and looks up the computed value 'banana':
SELECT id FROM product WHERE kind.trim().lowercase() = 'banana' EXPLAIN;{
attributes: {
projections: 'id'
},
children: [
{
attributes: {
access: "= 'banana'",
direction: 'Forward',
index: 'product_kind',
table: 'product'
},
context: 'Db',
operator: 'IndexScan'
}
],
context: 'Db',
operator: 'SelectProject'
}A query uses the index only when its condition repeats the expression as it is written in FIELDS. WHERE kind = 'banana' and the function-call form WHERE string::lowercase(kind) = 'banana' both scan the table, although the second one returns the same records, and their EXPLAIN output shows a TableScan instead. Comparisons and IN work on a computed value in the same way as on a stored one, and a composite index can mix the two, as in FIELDS kind.lowercase(), price.
Only method calls on a field path are accepted. A function call such as string::lowercase(kind) or an operator such as price * qty fails when the index is defined. To index one of those, store the result in a field of its own with DEFINE FIELD ... VALUE and index that field.
A column that ends in method calls is accepted on a SCHEMALESS table only. On a SCHEMAFULL table, defining such an index fails with an error such as The field 'kind.lowercase()' does not exist, even when the field kind is defined. On a SCHEMAFULL table, store the computed value with DEFINE FIELD ... VALUE and index that field instead.
Computed values on an optional field
Every record write runs the methods, and a method cannot run on NONE or NULL. With the index on kind.trim().lowercase() above, a record with no kind, or with kind set to NULL, fails with an error such as There was a problem running the trim() function. no such method found for the none type, and so does CREATE product:3 SET kind = 5. A DEFINE INDEX over existing records that lack the field fails in the same way. The index never yields NONE in place of the error, because the same condition in a table scan fails with it too.
To accept records without the field, write .? before the first method in the column and in the condition. The methods are then skipped when the field is NONE or NULL, and the index returns the same records as a table scan:
DEFINE TABLE product SCHEMALESS;
DEFINE INDEX product_kind_optional ON product FIELDS kind.?.trim().lowercase();

CREATE product:1 SET kind = '  Banana ';
CREATE product:2 SET kind = 'APPLE';
CREATE product:3;
CREATE product:4 SET kind = NULL;
CREATE product:5 SET kind = 'banana';

SELECT VALUE id FROM product WHERE kind.?.trim().lowercase() = 'banana' ORDER BY id;
//- [product:1, product:5]

-- NULL is a value, so only the record without the field matches NONE
SELECT VALUE id FROM product WHERE kind.?.trim().lowercase() = NONE ORDER BY id;
//- [product:3]
A UNIQUE index on such a column accepts any number of records without the field or with it set to NULL, and still refuses two records whose computed values are equal.
Writing the optional part as ?., as in kind?.trim().lowercase(), is a parse error.
Unique index
Ensures each value in the index is unique. A unique index helps enforce uniqueness across records by preventing duplicate entries in fields such as user IDs, email addresses, and other unique identifiers.
The following example creates a unique index for the email address field on a user table.
-- Makes sure that the email address in the user table is always unique
DEFINE INDEX userEmailIndex ON TABLE user FIELDS email UNIQUE;
The created index can be tested using the INFO statement.
INFO FOR TABLE user;The INFO statement will help you understand what indexes are defined in your TABLE.
{
    "events": {},
    "fields": {},
    "indexes": {
        "userEmailIndex": {
            sql: "DEFINE INDEX userEmailIndex ON user FIELDS email UNIQUE"
        }
    },
    "lives": {},
    "tables": {}
}
As a UNIQUE index is defined on the email field, a duplicate entry for that field will throw an error.
-- Create a user record and set an email ID.
CREATE user:1 SET email = 'test@surrealdb.com';[
{
"email": "test@surrealdb.com",
"id": "user:1"
}
]Creating another record with the same email ID will throw an error.
-- Create another user record and set the same email ID.
CREATE user:2 SET email = 'test@surrealdb.com';Database index `userEmailIndex` already contains 'test@surrealdb.com',
with record `user:1`To set the same email for user:2, the original record must be deleted
DELETE user:1;
CREATE user:2 SET email = 'test@surrealdb.com'
[
{
"email": "test@surrealdb.com",
"id": "user:2"
}
]A UNIQUE index does not treat an empty field as a duplicate. Any number of records can leave the field out (NONE) or set it to NULL, so a unique field can still be optional.
DEFINE FIELD email ON user TYPE option<string | null>;
DEFINE INDEX userEmailIndex ON user FIELDS email UNIQUE;

CREATE user:1;
CREATE user:2;
CREATE user:3 SET email = NULL;
CREATE user:4 SET email = NULL;

SELECT count() FROM user GROUP ALL;[{ count: 4 }] Treating NULL as a value with NULLS NOT DISTINCT
Available since: v4.0.0
UNIQUE NULLS NOT DISTINCT makes NULL take part in uniqueness like any other value, so only one record can hold NULL in the field. A record that leaves the field out (NONE) is still not compared, so any number of records can do that. In a composite index, a tuple that holds NULL is compared as a whole, and a tuple that holds NONE is not compared.
DEFINE INDEX unique_v ON solo FIELDS v UNIQUE NULLS NOT DISTINCT;

CREATE solo:1 SET v = NULL;
CREATE solo:2;
CREATE solo:3;
CREATE solo:4 SET v = NULL;"Database index `unique_v` already contains NULL, with record `solo:1`"An empty array is indexed as NULL, so on such an index two records with an empty array collide, and so do an empty array and NULL. Adding the clause to an existing index with DEFINE INDEX OVERWRITE builds the index again, and the statement fails, keeping the existing index, if the table already holds more than one NULL. INFO FOR TABLE shows the clause as part of the index definition.
Conditional uniqueness
A UNIQUE index applies to every record in the table. WHERE is accepted only on a COUNT index, so DEFINE INDEX ... UNIQUE WHERE ... is a parse error. Because a unique index ignores NONE, a field with a VALUE clause that holds the value only when the condition is true gives the same effect as a partial unique index. The following index allows any number of inactive plans for an email address, but only one active plan:
DEFINE FIELD email ON plan TYPE string;
DEFINE FIELD active ON plan TYPE bool;
DEFINE FIELD active_email ON plan VALUE IF active { email } ELSE { NONE };
DEFINE INDEX one_active_plan ON plan FIELDS active_email UNIQUE;

CREATE plan SET email = 'ana@example.com', active = false;
CREATE plan SET email = 'ana@example.com', active = false;
CREATE plan SET email = 'ana@example.com', active = true;
CREATE plan SET email = 'ana@example.com', active = true;Database index `one_active_plan` already contains 'ana@example.com', with record `plan:...`A unique index stays correct when transactions write at the same time: of two concurrent inserts with the same value, one commits and the other fails with a retryable transaction conflict. See Unique indexes under concurrent writes.
On a field that holds an array, an index has one entry for each element rather than one for the whole array. A UNIQUE index on such a field therefore makes every element unique across all records, so two records cannot share any element:
DEFINE INDEX unique_tag ON post FIELDS tags UNIQUE;

CREATE post:1 SET tags = ['a', 'b'];
CREATE post:2 SET tags = ['b', 'c'];Database index `unique_tag` already contains 'b', with record `post:1`The uniqueness is between records. One record whose array holds the same element twice, such as tags = ['d', 'd'], does not conflict with itself, and the index holds that element once for it.
To make the array as a whole unique instead, so that two records cannot have the same tags but may share some, end the field with .... The index then has one entry for the whole array:
DEFINE INDEX unique_tags ON post FIELDS tags... UNIQUE;

CREATE post:1 SET tags = ['a', 'b'];
CREATE post:2 SET tags = ['b', 'c'];
CREATE post:3 SET tags = ['a', 'b'];Database index `unique_tags` already contains ['a', 'b'], with record `post:1`INFO FOR TABLE shows this index as FIELDS tags…, with a single ellipsis character, which SurrealQL also accepts in place of .... The order of the elements counts, so ['b', 'a'] is a different value from ['a', 'b']. To treat the two as the same, index a field that holds the array sorted and converted to a single value:
DEFINE FIELD tag_key ON post VALUE <string> tags.sort();
DEFINE INDEX unique_tags ON post FIELDS tag_key UNIQUE;
A UNIQUE index compares values exactly, so 'Bob' and 'bob' count as different. For a case-insensitive unique value, index a computed value that normalises it:
DEFINE INDEX unique_name ON user FIELDS name.lowercase() UNIQUE;

CREATE user:1 SET name = 'Bob';
CREATE user:2 SET name = 'bOB';Database index `unique_name` already contains 'bob', with record `user:1`A query uses this index for WHERE name.lowercase() = 'bob', but not for a condition on name alone. Alternatively, store the normalised value in a field of its own and index that field, which keeps the lowercase value visible in query results:
DEFINE FIELD name_key ON user VALUE name.lowercase();
DEFINE INDEX unique_name ON user FIELDS name_key UNIQUE;
Composite index
A composite index spans multiple fields of a table. Composite indexes are mainly used to create a unique index when the definition of what is unique pertains to more than one field.
-- Create an index on the account and email fields of the user table
DEFINE INDEX test ON user FIELDS account, email UNIQUE;
As with a single field, a composite UNIQUE index does not check a record for duplicates when any of its fields is NONE or NULL. In the following example, t:1 and t:2 both have i = 1 and no j, and both are created. Only t:4 fails, because it repeats both values of t:3.
DEFINE INDEX t_idx ON t FIELDS i, j UNIQUE;

CREATE t:1 SET i = 1;
CREATE t:2 SET i = 1;
CREATE t:3 SET i = 1, j = 'a';
CREATE t:4 SET i = 1, j = 'a';Database index `t_idx` already contains [1, 'a'], with record `t:3`To check the other fields when one is missing, give the optional field a default value, such as DEFINE FIELD j ON t TYPE string DEFAULT '', or add a separate UNIQUE index on the fields that must be unique by themselves.
When more than one of the fields holds an array, the index has one entry for every combination of their elements. A record with tags = ['a', 'b'] and authors = ['x', 'y'] gives four entries, so a UNIQUE index refuses any later record that repeats one of those four pairs:
DEFINE INDEX tag_author ON post FIELDS tags, authors UNIQUE;

CREATE post:1 SET tags = ['a', 'b'], authors = ['x', 'y'];
CREATE post:2 SET tags = ['a'], authors = ['y'];Database index `tag_author` already contains ['a', 'y'], with record `post:1`A query that uses such an index returns each record once, however many of its entries match.
Before SurrealDB 3.3.1, an index over two or more array fields stored only some of the combinations, so the CREATE post:2 above succeeded. An index written by an earlier release stays incomplete after upgrading until you run REBUILD INDEX on it. Earlier releases could also return a record once for each matching entry when a query used a composite index with an array field, such as FIELDS account, emails.*.address queried by account alone. That needs no action after upgrading.
Array-element composite indexes
Available since: v3.1.0
From SurrealDB 3.1.0, a composite index can lead with an array-element field (tags.*) so containment predicates combine with ordering on a trailing field without a full table scan. This supports patterns such as WHERE tags.* CONTAINS 'x' ORDER BY age DESC LIMIT N and the multi-value forms CONTAINSANY / ANYINSIDE on array fields.
DEFINE INDEX tag_age ON article FIELDS tags.*, age;

-- Bounded index walk (check with EXPLAIN FULL)
SELECT * FROM article
WHERE tags.* CONTAINS 'release-notes'
ORDER BY age DESC
LIMIT 10;
CONTAINSALL / ALLINSIDE may still apply a residual filter above the union when intersection semantics require it. See operators and EXPLAIN to confirm the planner choice.
A containment condition that takes each element of the field, as tags.* CONTAINS 'x', tags[*] CONTAINS 'x' and 'x' INSIDE tags[*] do, reads the index on tags.* directly. The plain form tags CONTAINS 'x', and 'x' INSIDE tags, CONTAINSANY and CONTAINSALL, can also match a record whose tags is not an array, such as a string that holds 'x' as a substring. The index lists a record whose tags is a string, a range, another single value or missing under NONE, so from SurrealDB 4.0 the plain form reads the entries for 'x', NONE and NULL together, and checks the condition on each record it reads. EXPLAIN shows this as a UnionIndexScan with one branch for each value.
The plain form reads the table instead in three cases:
Any record has stored an object or a record link in the field. The index stores such a value whole, so it has no entry that the condition can find.
The query has an
ORDER BYthat the index does not give, such asORDER BYa field that is not the next field of the index, or aLIMITwith noORDER BY. A table scan rejects most records without decoding them, so it costs less in these cases.The index was built by a release before 4.0, which did not record the kinds of value it stored.
REBUILD INDEXrecords them.
With ORDER BY on the next field of the index, as in WHERE tags CONTAINS 'x' ORDER BY created DESC LIMIT 10, the plan reads the three sets of entries in index order and stops at the limit.
From SurrealDB 4.0, a field declared as a set is indexed as a whole by .*, not element by element. WHERE s CONTAINS 3 on a set field reads the records instead of using the index, and a UNIQUE index over s.* treats the whole set as the key.
A composite index can include more than one array field, and a record can hold arrays in all of them. The index holds an entry for each combination of their elements, so a query with a condition on each field reads both from the index:
DEFINE INDEX tags_sizes ON product FIELDS tags.*, sizes.*;
CREATE product:jumper SET tags = ["wool", "winter"], sizes = ["S", "M"];
CREATE product:shirt SET tags = ["cotton"], sizes = ["M", "L"];

EXPLAIN SELECT id FROM product
WHERE tags.* CONTAINS "wool" AND sizes.* CONTAINS "M";SelectProject [ctx: Db] [projections: id]
IndexScan [ctx: Db] [table: product, index: tags_sizes, access: ['wool', 'M'], direction: Forward]Count index
Available since: v3.0.0
A count index maintains a running count of records on a table. It is used with count() and GROUP ALL in a query. SurrealDB stores incremental count deltas and compacts them in the background.
Count indexes come in two forms:
COUNT- counts every record in the table. Used withSELECT count() FROM <table> GROUP ALL(noWHERE).COUNT WHERE <condition>- counts only records that match the condition. Used withSELECT count() FROM <table> WHERE <condition> GROUP ALLwhen the queryWHEREclause exactly matches the index condition.
As a count index is declared on a table as a whole, it cannot use the FIELDS / COLUMNS clause.
Full-table counts
For SELECT count() FROM <table> GROUP ALL, SurrealDB already uses a CountScan fast path that counts record keys in storage without deserialising every record. An unconditional COUNT index is optional here; it can reduce work further once count deltas have been compacted, but a freshly built index on a large existing table may hold millions of delta entries until compaction runs.
DEFINE INDEX idx ON indexed_reading COUNT;

FOR $_ IN 0..100000 {
    CREATE reading SET temperature = rand::int(0, 10);
};

FOR $_ IN 0..100000 {
    CREATE indexed_reading SET temperature = rand::int(0, 10);
};

-- Wait a moment before running these two
-- queries to ensure the index is built
SELECT count() FROM reading GROUP ALL;
SELECT count() FROM indexed_reading GROUP ALL;
Filtered counts (COUNT WHERE)
Use COUNT WHERE when you repeatedly need SELECT count() … WHERE … GROUP ALL and do not want to scan and deserialise every record. The planner uses IndexCountScan when the query WHERE matches the index condition exactly (same expression as written in DEFINE INDEX).
DEFINE TABLE item SCHEMALESS;
DEFINE INDEX item_active_count ON item COUNT WHERE status = "active";

CREATE item:a SET status = "active";
CREATE item:b SET status = "active";
CREATE item:c SET status = "inactive";

SELECT count() FROM item WHERE status = "active" GROUP ALL;

EXPLAIN ANALYZE SELECT count() FROM item WHERE status = "active" GROUP ALL;
Requirements for the filtered fast path:
GROUP ALLmust be present.The query
WHEREmust match the index condition exactly (not a broader or different predicate).The index build must be complete (
INFO FOR INDEX …showsready).Field-level
SELECTpermissions on fields in the condition must not block index-only counting.
If the WHERE clause is not an exact match, SurrealDB falls back to a full table scan, filter, and count.
When to use which
For many applications, a standard B-tree index (FIELDS / COLUMNS) is the default for filtered counts. Recent planner improvements let a covering B-tree use the same IndexCountScan fast path as a COUNT WHERE index, so the two often perform similarly at query time.
Available since: v4.0.0
A B-tree index also counts several values of its field without reading a record: count() over status IN ['draft', 'review'], or over status = 'draft' OR status = 'review', adds up one walk of the index per value. The values must be literals and must differ from each other, so IN ['draft', 'draft'] reads the records instead, and an IN list of more than 32 values does not use the index at all. A count over a page of results, SELECT count() FROM (SELECT 1 FROM article WHERE status = 'draft' LIMIT 100) GROUP ALL, stops walking the index once it reaches the limit. EXPLAIN shows each walk as an IndexScan with keys_only: yes under the IndexCountScan.
That does not make count indexes obsolete, however, as they solve a narrower problem and have a smaller storage footprint.
If you would add
DEFINE INDEX … FIELDS statusanyway, a separateCOUNT WHERE status = "active"index is usually redundant. In this case, a standard B-tree is preferred.When to use
COUNT WHEREinstead: materialised cardinality for a fixed condition you do not want to back with a B-tree; compound predicates without a covering index; or a dedicated counter separate from lookup indexes.
The following chart sums up a few use cases and when to prefer one vs. the other.
| Goal | Prefer |
|---|---|
count() … GROUP ALL with no WHERE | Nothing extra required; CountScan counts record keys. Unconditional COUNT is optional. |
count() … WHERE field = value GROUP ALL on a field you already filter on | FIELDS field B-tree (also supports SELECT, ORDER BY, and other predicates) |
| Many per-value counts on the same field | One B-tree on that field |
One fixed combined predicate (IN, AND, etc.) counted repeatedly | COUNT WHERE with the exact same expression in the query |
| Fast counts for a predicate but no B-tree on those fields | COUNT WHERE |
Compound WHERE with no covering composite B-tree | COUNT WHERE with the exact compound condition |
Storage footprint
Count indexes and B-tree indexes store different shapes of data, so size is not the same even when query performance is similar.
A B-tree index stores one entry per indexed record: encoded field value(s) plus the record id in the key. Storage grows with the number of records in the table (O(n) for that index).
A COUNT WHERE index does not store per-record field keys. It appends small delta entries (IndexCountKey) when records enter or leave the predicate, then compacts them into a single aggregate entry in the background. In steady state, footprint is usually much smaller than a B-tree on the same field, often a handful of keys rather than one per record.
So COUNT WHERE can be attractive when you need fast filtered counts without paying the per-record storage of a B-tree if it will not be used for anything else.
To compare indexed and non-indexed performance, the WITH NOINDEX clause can be used.
-- Slow path: scan every record
SELECT count() FROM item WITH NOINDEX WHERE status = "active" GROUP ALL;

-- Fast path: count index deltas (or B-tree keys if a covering index exists)
SELECT count() FROM item WHERE status = "active" GROUP ALL;
Multiple conditions
As each COUNT WHERE index tracks one fixed predicate, it does not accelerate several different counts unless each query repeats the exact condition stored in the index.
DEFINE INDEX openish_count ON person COUNT
    WHERE status IN ["active", "non-active", "delayed"];

-- Fast only when the WHERE matches the index exactly
SELECT count() FROM person
    WHERE status IN ["active", "non-active", "delayed"]
    GROUP ALL;
In the above example, it does not also speed up WHERE status = "active" GROUP ALL or other subsets.
For separate per-status totals, one FIELDS status B-tree is usually simpler than one COUNT WHERE index per value. See When to use which.
Use EXPLAIN ANALYZE to confirm IndexCountScan is selected. If the query WHERE differs even slightly from the index condition, SurrealDB falls back to a full scan.
Other COUNT syntax notes
-- Other clauses like `COMMENT` are fine
DEFINE INDEX idx ON users COUNT
    COMMENT "Users are expected to grow substantially so index the count"
    CONCURRENTLY;

-- Conditional count indexes
DEFINE INDEX active_users ON users COUNT WHERE status = "active" CONCURRENTLY;

-- But not `FIELD`
DEFINE INDEX idx2 ON person FIELD name;Parse error: Expected at least one column - Use FIELDS to define columns
--> [1:29]
|
1 | DEFINE INDEX idx2 ON person FIELD name;
| ^^^^^ Full-text search (FULLTEXT) index
Enables efficient searching through textual data, supporting advanced text-matching features like proximity searches and keyword highlighting.
The Full-Text search index helps implement comprehensive search functionalities in applications, such as searching through articles, product descriptions, and user-generated content.
The following example creates a full-text search index for a name field on a user table.
-- Define the an analyzer with
DEFINE ANALYZER example_ascii TOKENIZERS class FILTERS ascii;
-- Since 3.0.0: only FULLTEXT used to benefit from concurrent full-text search
DEFINE INDEX userNameIndex ON TABLE user FIELDS name
FULLTEXT ANALYZER example_ascii BM25 HIGHLIGHTS;SEARCHorFULLTEXT: By using theSEARCHkeyword, you enable full-text search on the specified field.ANALYZER ascii: Uses a custom analyzer calledexample_asciiwhich uses the class tokenizer andasciifilter to analyse the text input.BM25: Ranking algorithm used for relevance scoring. BM25 weighs a term by how rare it is, and every matching term gets a weight above zero, sosearch::scoreis positive for every match. Before SurrealDB 4.0, the weight of a term appearing in half or more of the indexed documents was clamped to zero, which madesearch::scorereturn0for it. See how common terms are weighted.HIGHLIGHTS: Allows keyword highlighting in search results output when using thesearch::highlightfunctionFIELDS: a full-text search index can only be used on one field at a time. To use full-text search on more than one field, use a separateDEFINE INDEXstatement for each one.
A field that is unique and searchable
An index has a single kind, such as UNIQUE or FULLTEXT. For a field that has to be both unique and searchable, define two indexes on it:
DEFINE ANALYZER simple TOKENIZERS blank FILTERS lowercase;
DEFINE INDEX title_unique ON book FIELDS title UNIQUE;
DEFINE INDEX title_search ON book FIELDS title FULLTEXT ANALYZER simple BM25;

CREATE book:1 SET title = 'The Grey Book';
SELECT id FROM book WHERE title @@ 'grey';[{ id: book:1 }]Both indexes are used without naming them: the query planner chooses the index by the operator in the condition, so WHERE title = 'The Grey Book' uses title_unique and WHERE title @@ 'grey' uses title_search. WITH INDEX is not needed here, and naming the index that cannot serve the operator, as in WITH INDEX title_search with =, makes the query scan the table instead.
A DEFINE INDEX takes at most one of UNIQUE, COUNT, FULLTEXT, HNSW and DISKANN. Writing two kinds in one statement is a parse error that points at the second kind, and the same kind written twice reports that it is given twice:
DEFINE INDEX title ON book FIELDS title UNIQUE FULLTEXT ANALYZER simple;Parse error: Cannot combine FULLTEXT with UNIQUE
--> [1:48]
|
1 | DEFINE INDEX title ON book FIELDS title UNIQUE FULLTEXT ANALYZER simple;
| ^^^^^^^^ an index can only be one of UNIQUE, COUNT, FULLTEXT, HNSW or DISKANN
--> [1:41]
|
1 | DEFINE INDEX title ON book FIELDS title UNIQUE FULLTEXT ANALYZER simple;
| ^^^^^^ First given hereThe UNIQUE index above compares titles exactly, while the search ignores case. To make the unique check match the same way as the search, store a key built with the analyzer itself, using search::analyze(), and make the key unique. With the ascii filter, the key also ignores accents, which a computed value such as nickname.lowercase() does not:
DEFINE ANALYZER ascii_lcase TOKENIZERS blank FILTERS lowercase, ascii;
DEFINE FIELD nickname ON user TYPE string;
DEFINE FIELD nickname_key ON user VALUE search::analyze('ascii_lcase', nickname).join(' ');
DEFINE INDEX nickname_unique ON user FIELDS nickname_key UNIQUE;
DEFINE INDEX nickname_search ON user FIELDS nickname FULLTEXT ANALYZER ascii_lcase BM25;

CREATE user:1 SET nickname = 'Zoë';
CREATE user:2 SET nickname = 'ZOE';Database index `nickname_unique` already contains 'zoe', with record `user:1`search::analyze() returns the tokens as an array, and .join(' ') turns them into one string. The key is computed again on each write, so do not make the field READONLY, or a changed nickname keeps its old key. A lookup on the key uses the unique index:
SELECT id FROM user WHERE nickname_key = 'zoe' EXPLAIN;{
attributes: {
projections: 'id'
},
children: [
{
attributes: {
access: "= 'zoe'",
direction: 'Forward',
index: 'nickname_unique',
predicate: "nickname_key = 'zoe'"
},
context: 'Db',
operator: 'IndexScan'
}
],
context: 'Db',
operator: 'SelectProject'
} FULLTEXT vs. SEARCH
Since version 3.0.0, using FULLTEXT ANALYZER is the syntax used for a text analyzer. The FULLTEXT clause allows for more performant concurrent full-text search, as well as the ability to use the OR operator.
Spatial index
Available since: v4.0.0
A SPATIAL index lets a query find the records whose geometry lies in an area without reading every record of the table. It indexes a field holding a geometry, such as a geometry<point>, and it can index any geometry type.
DEFINE INDEX @name ON [ TABLE ] @table
	FIELDS [ @prefix_field, ... , ] @geometry_field SPATIAL
The index serves these conditions on the indexed field:
The spatial operators
INSIDE,CONTAINS,INTERSECTS,CONTAINSANY,CONTAINSALL,ANYINSIDEandALLINSIDE, with the field on either side.A radius in metres given with
geo::distanceand<or<=, such asgeo::distance(location, $here) < 10000. The arguments can be in either order, and the comparison can be written either way round, as in10000 > geo::distance(location, $here).Several of these conditions joined with
ANDorOR, and a condition beside one that another index serves, such asstatus = 'open' AND location INSIDE $area.
The following example indexes the locations of six cities and finds those within 400 km of London:
DEFINE TABLE city SCHEMAFULL;
DEFINE FIELD name ON city TYPE string;
DEFINE FIELD location ON city TYPE geometry<point>;
DEFINE INDEX city_location ON city FIELDS location SPATIAL;

INSERT INTO city [
	{ id: city:london, name: 'London', location: (-0.1276, 51.5072) },
	{ id: city:paris, name: 'Paris', location: (2.3522, 48.8566) },
	{ id: city:brussels, name: 'Brussels', location: (4.3517, 50.8503) },
	{ id: city:amsterdam, name: 'Amsterdam', location: (4.9041, 52.3676) },
	{ id: city:berlin, name: 'Berlin', location: (13.4050, 52.5200) },
	{ id: city:tokyo, name: 'Tokyo', location: (139.6917, 35.6895) }
] RETURN NONE;

SELECT VALUE name FROM city
	WHERE geo::distance(location, (-0.1276, 51.5072)) < 400000
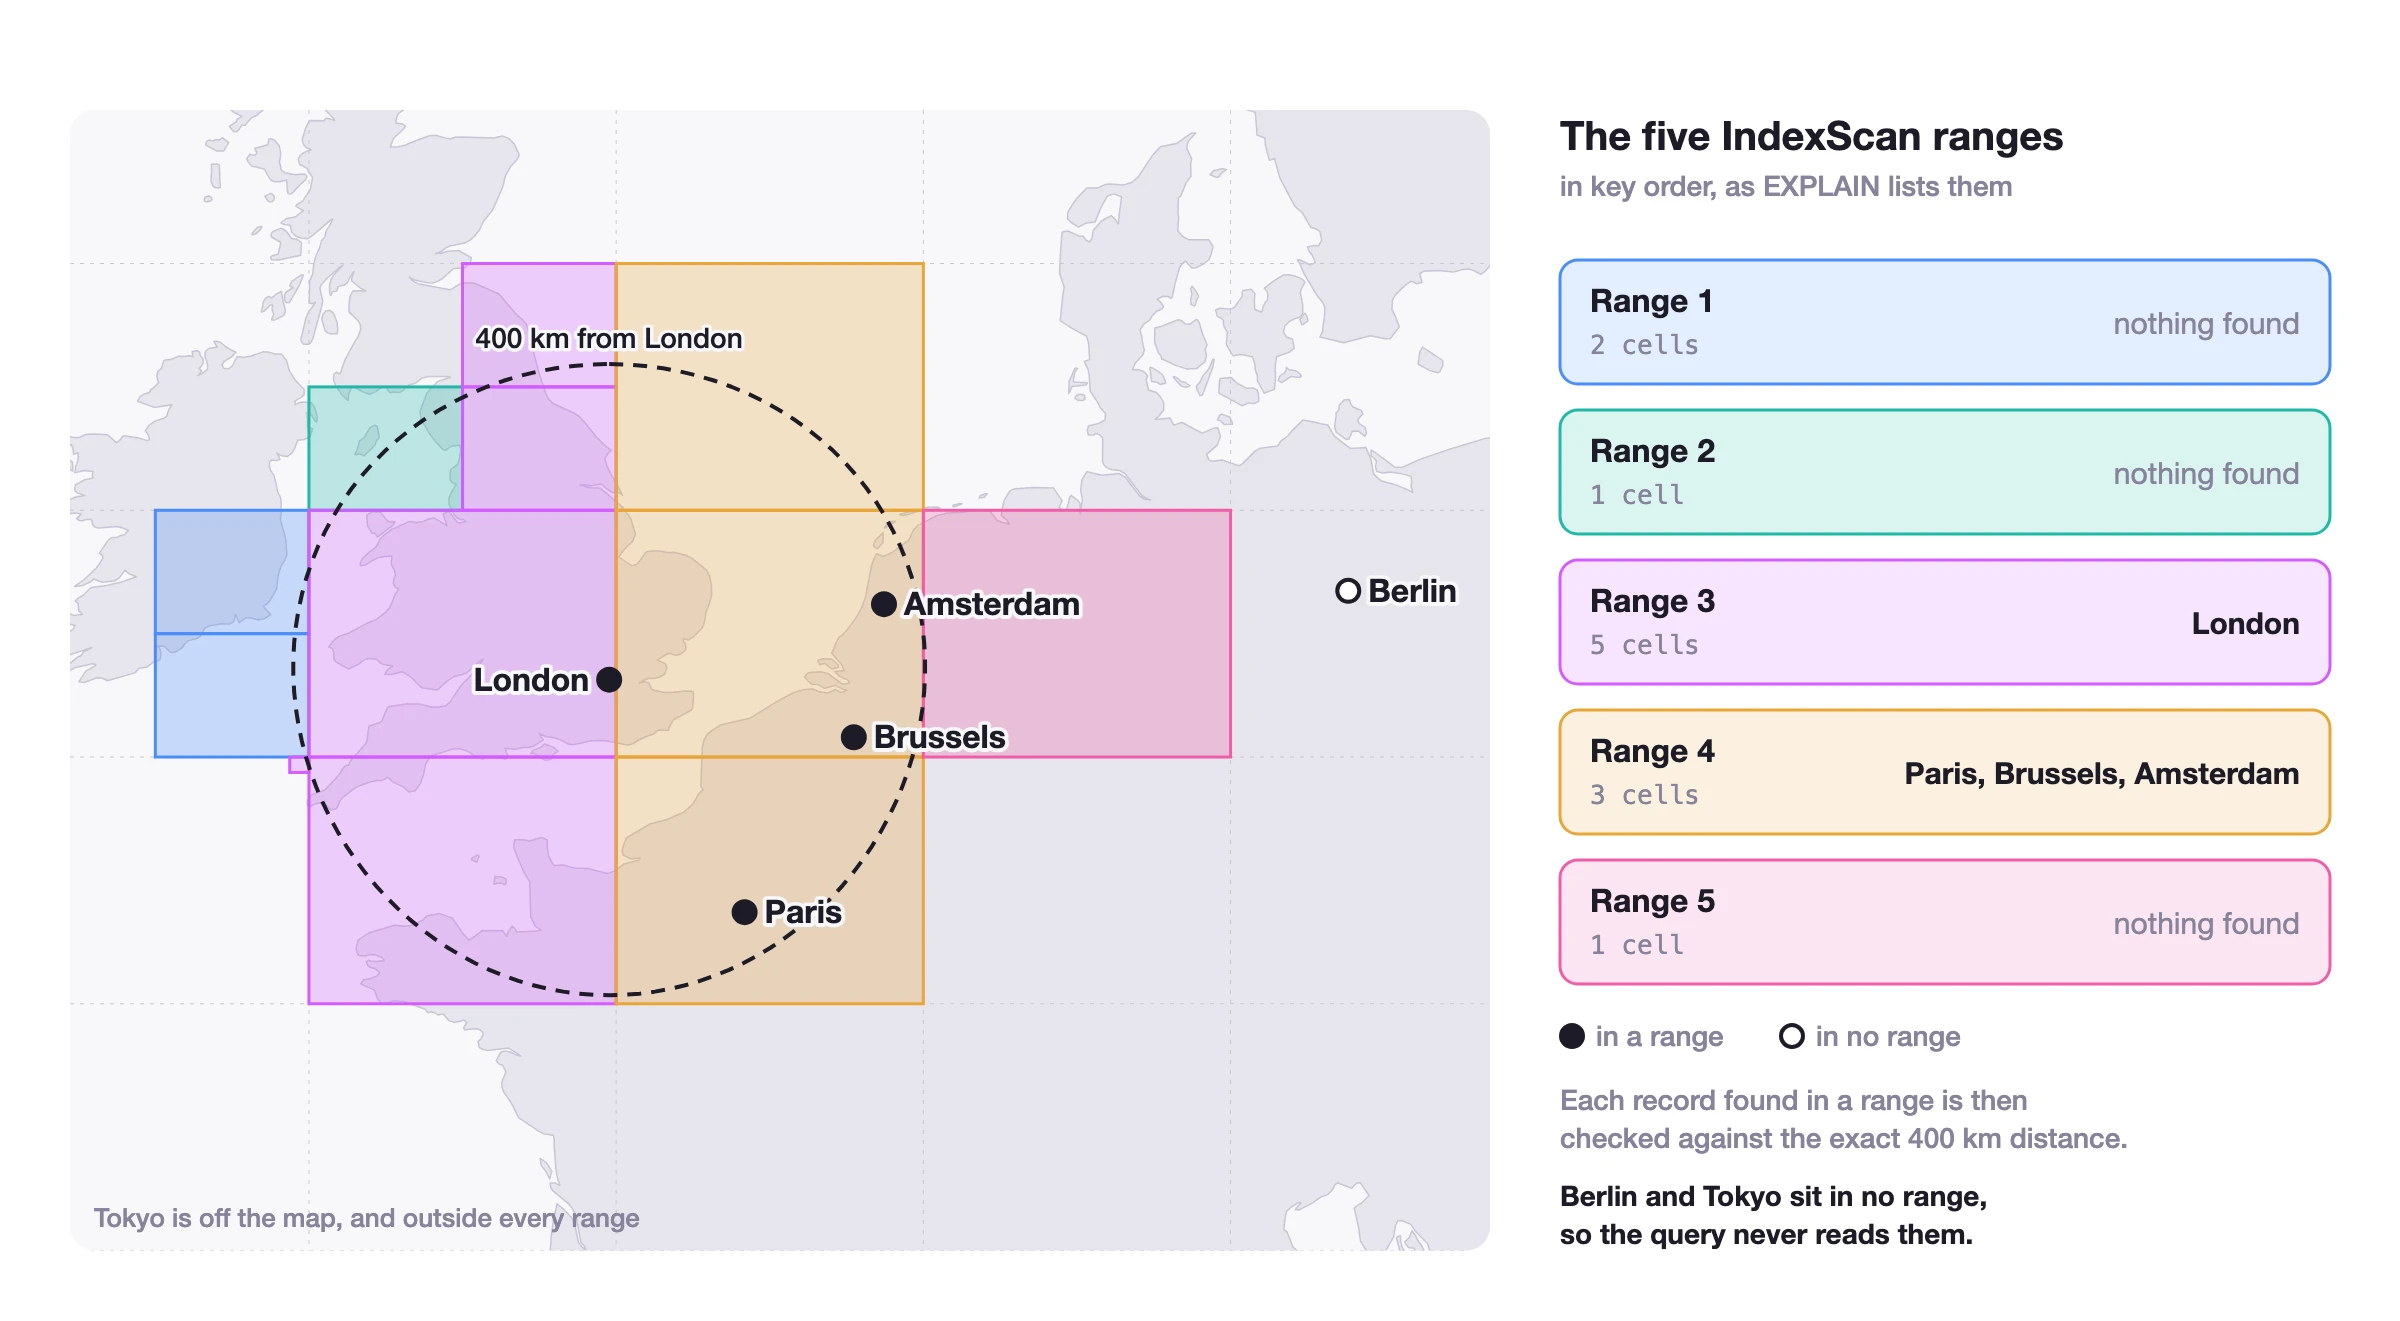
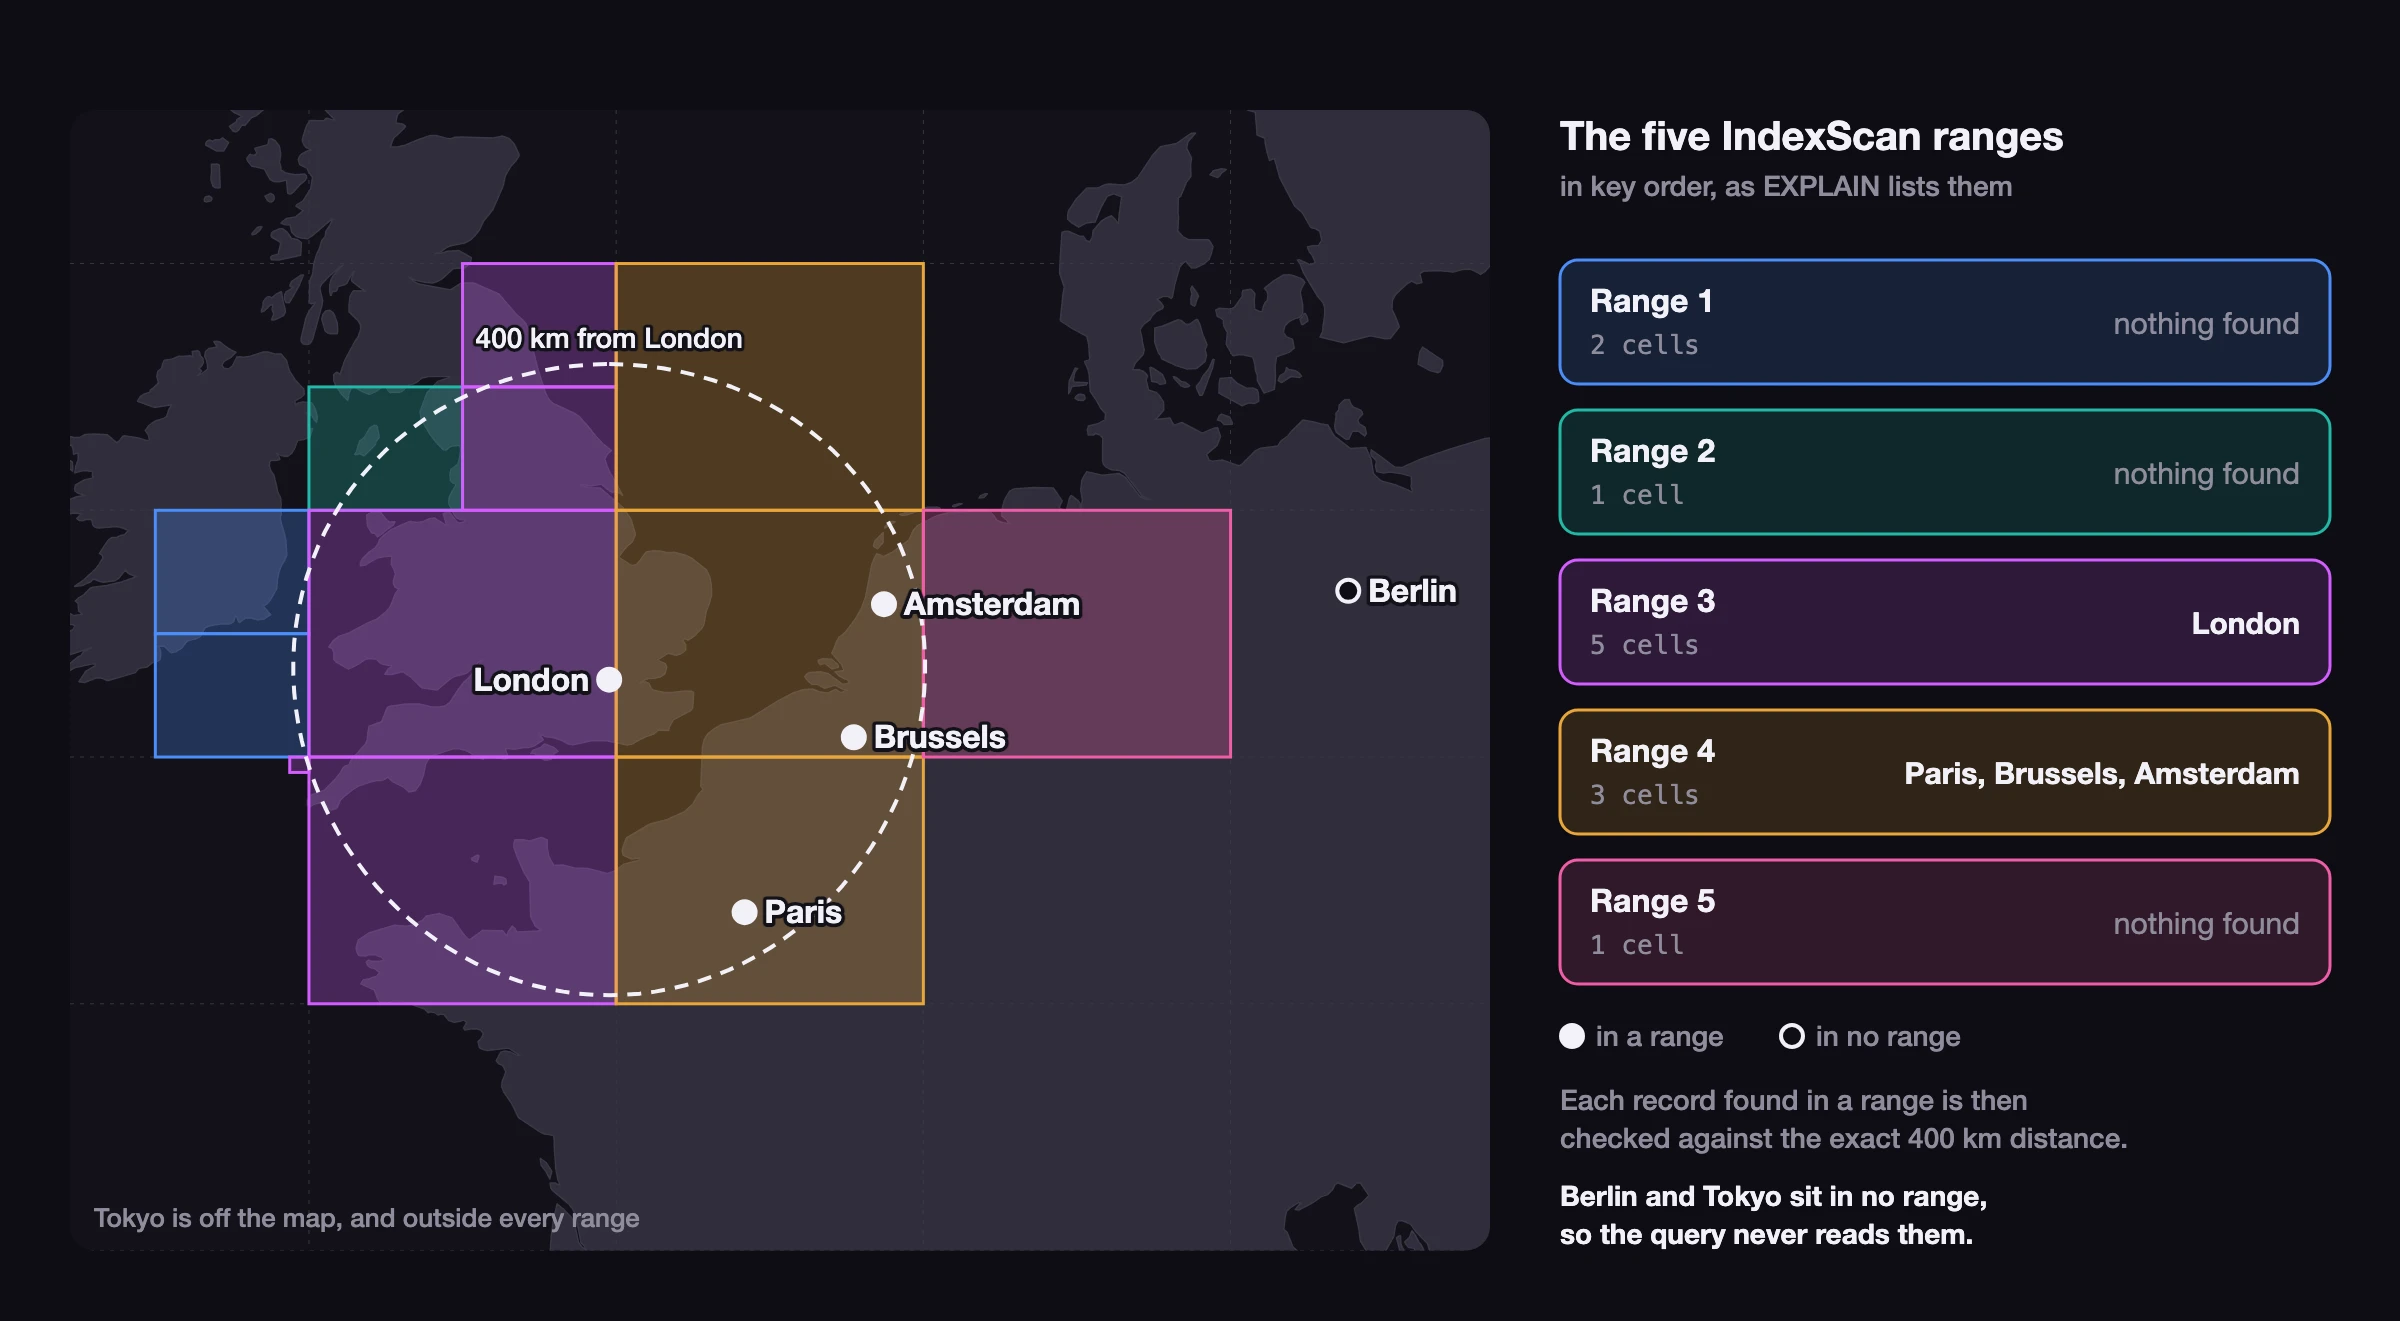
ORDER BY name;['Amsterdam', 'Brussels', 'London', 'Paris']The index stores each geometry as cells of a grid over the globe. A query reads the ranges of cells that cover its area and then checks each record it finds against the exact condition. EXPLAIN shows one IndexScan for each range:
EXPLAIN SELECT VALUE name FROM city
WHERE geo::distance(location, (-0.1276, 51.5072)) < 400000;ProjectValue [ctx: Db] [expr: name]
UnionIndexScan [ctx: Db] [table: city, branches: 5, decode: [name]]
IndexScan [ctx: Db] [table: city, index: city_location, access: >=1655143231802834952 <=1655283969291190264, point_filter: geo::distance(location, (-0.1276, 51.5072)) < 400000, direction: Forward]
IndexScan [ctx: Db] [table: city, index: city_location, access: >=1655635813012078600 <=1655706181756256248, point_filter: geo::distance(location, (-0.1276, 51.5072)) < 400000, direction: Forward]
IndexScan [ctx: Db] [table: city, index: city_location, access: >=1655776550500433928 <=1656481337453838328, point_filter: geo::distance(location, (-0.1276, 51.5072)) < 400000, direction: Forward]
IndexScan [ctx: Db] [table: city, index: city_location, access: >=1802284275878330376 <=1803128700808462328, point_filter: geo::distance(location, (-0.1276, 51.5072)) < 400000, direction: Forward]
IndexScan [ctx: Db] [table: city, index: city_location, access: >=1803410175785173000 <=1803691650761883640, point_filter: geo::distance(location, (-0.1276, 51.5072)) < 400000, direction: Forward]The cells are rectangles of longitude and latitude, and each range is a run of neighbouring cells. Drawn on a map, the five ranges cover the 400 km circle with some margin. London is in one range and Paris, Brussels and Amsterdam are in another, while Berlin and Tokyo are in none, so the query never reads them:
A polygon works in the same way. With the records above, this query uses the index and returns the cities inside a box around the Low Countries:
SELECT VALUE name FROM city
	WHERE location INSIDE { type: 'Polygon', coordinates: [[[0, 48], [6, 48], [6, 53], [0, 53], [0, 48]]] }
ORDER BY name;['Amsterdam', 'Brussels', 'Paris']The index does not serve every condition on a geometry:
OUTSIDE, and ageo::distancecomparison with>or>=, read the whole table.An ordering by distance, such as
ORDER BY distance LIMIT 3ongeo::distance(location, $here) AS distance, sorts every record. To find the nearest records with the index, add a radius to theWHEREclause, so that only the records inside it are sorted.
Fields before the geometry
Fields listed before the geometry field make a compound index, which serves a query that compares each of them for equality, or with CONTAINS for an array field indexed with .*, and also has a spatial condition. A query with only the spatial condition does not use a compound index, so define a separate index on the geometry field alone as well if such queries are common.
DEFINE TABLE vehicle SCHEMAFULL;
DEFINE FIELD fleet ON vehicle TYPE string;
DEFINE FIELD location ON vehicle TYPE geometry<point>;
DEFINE INDEX vehicle_fleet_location ON vehicle FIELDS fleet, location SPATIAL;

INSERT INTO vehicle [
	{ id: vehicle:1, fleet: 'north', location: (-0.12, 51.51) },
	{ id: vehicle:2, fleet: 'north', location: (2.35, 48.85) },
	{ id: vehicle:3, fleet: 'south', location: (-0.10, 51.50) },
	{ id: vehicle:4, fleet: 'north', location: (-0.11, 51.52) }
] RETURN NONE;

SELECT VALUE id FROM vehicle
	WHERE fleet = 'north'
		AND geo::distance(location, (-0.1276, 51.5072)) < 10000
ORDER BY id;[vehicle:1, vehicle:4]Arrays and sets of geometries
A field of type array<geometry<point>> is indexed with FIELDS stops SPATIAL, and each geometry in it is indexed. For a set<geometry<point>>, or an array on a schemaless table, use FIELDS stops.* SPATIAL. The operators that take several geometries, such as ANYINSIDE and ALLINSIDE, then use the index:
DEFINE TABLE route SCHEMAFULL;
DEFINE FIELD stops ON route TYPE array<geometry<point>>;
DEFINE INDEX route_stops ON route FIELDS stops SPATIAL;

CREATE route:a SET stops = [(-0.12, 51.51), (2.35, 48.85)];
CREATE route:b SET stops = [(13.40, 52.52)];

SELECT VALUE id FROM route
WHERE stops ANYINSIDE { type: 'Polygon', coordinates: [[[-1, 51], [1, 51], [1, 52], [-1, 52], [-1, 51]]] };[route:a]Vector search inside an area
When a KNN query on an HNSW or DISKANN index has a spatial condition in the same WHERE clause, the SPATIAL index first finds the records inside the area, and the vector search then ranks only those records. The query returns the k nearest records inside the area, rather than the k nearest records overall with those outside the area removed. In the following example, place:bistro in Paris has the same vector as place:cafe, but is outside the 10 km radius:
DEFINE TABLE place SCHEMAFULL;
DEFINE FIELD location ON place TYPE geometry<point>;
DEFINE FIELD embedding ON place TYPE array<float>;
DEFINE INDEX place_location ON place FIELDS location SPATIAL;
DEFINE INDEX place_embedding ON place FIELDS embedding HNSW DIMENSION 2;

INSERT INTO place [
	{ id: place:cafe, location: (-0.12, 51.51), embedding: [1.0, 0.0] },
	{ id: place:bakery, location: (-0.10, 51.50), embedding: [0.8, 0.2] },
	{ id: place:library, location: (-0.11, 51.52), embedding: [0.0, 1.0] },
	{ id: place:bistro, location: (2.35, 48.85), embedding: [1.0, 0.0] }
] RETURN NONE;

SELECT id, vector::distance::knn() AS distance FROM place
	WHERE geo::distance(location, (-0.1276, 51.5072)) < 10000
		AND embedding <|2,40|> [1.0, 0.0]
ORDER BY distance;[
{ distance: 0f, id: place:cafe },
{ distance: 0.28284270931360533f, id: place:bakery }
]Datastore format
A SPATIAL index needs a datastore that uses the 4.0 record format, because a 3.x node cannot read it. A new datastore, and an in-memory or SurrealKV datastore after its first 4.0 start, already does. A TiKV datastore upgraded from 3.x refuses DEFINE INDEX ... SPATIAL until every node runs 4.0 and the nodes start with SURREAL_FEATURE_LEVEL=4.0.
Vector search indexes
Vector search indexes in SurrealDB support efficient k-nearest neighbors (kNN) and Approximate Nearest Neighbor (ANN) operations, which are used to perform similarity searches within complex, high-dimensional datasets and data types. Refer to the Vector Search Cheat Sheet for the parameters allowed.
After a large insert or update, a vector index stores the new records separately until a background process merges them into its graph. Searches return correct results throughout, but are slower until that merge completes. INFO FOR INDEX reports this as building.compacting, which is separate from building.status.
From 3.0.0 until 3.3.1, an HNSW or DISKANN index lost track of records when more than nine of them held an identical vector. KNN results left out the tenth and later records, and could return fewer than k results after such records were deleted. SurrealDB 3.3.1 fixes this for new writes, but an index that was already affected stays that way until it is rebuilt. After upgrading, run REBUILD INDEX on each vector index whose table can hold more than nine records with the same vector, such as duplicated embeddings or a placeholder vector.
Before SurrealDB 3.3.1, a KNN query could return fewer than k results for a user whose table SELECT permission hides some records. With no other condition in the WHERE clause, as in WHERE embedding <|10,40|> $query, hidden records took places in the top k and were then removed, so a record user who can see few of the records could get no results at all. Adding any other condition to the WHERE clause avoided this. A DISKANN index could also return no results for a query with a SELECT permission or another WHERE condition once the index had been compacted. SurrealDB 3.3.1 applies the permission while it searches, so both return the nearest records that the user can see.
Types
When defining a vector index with HNSW, you can define the types the vector will be stored in. The TYPE clause is optional and can be used to specify the data type of the vector. SurrealDB supports the following types:
F64 | F32 | F16 | I64 | I32 | I16 | I8 | U8
F64: Represents 64-bit floating-point numbers (double precision floating-point numbers).F32: Represents 32-bit floating-point numbers (single precision floating-point numbers).F16: Represents 16-bit floating-point numbers (half precision floating-point numbers).I64: Represents 64-bit signed integers.I32: Represents 32-bit signed integers.I16: Represents 16-bit signed integers.I8: Represents 8-bit signed integers.U8: Represents 8-bit unsigned integers.
In SurrealDB the default type for vectors is F32.
An integer TYPE truncates each component rather than quantising it, so a normalised embedding, with components between -1 and 1, is stored as all zeros and KNN results become arbitrary. Use F32 or F16 for embeddings.
DISKANN indexes, available from SurrealDB 3.1, accept a narrower set of element types: F32, F16, I8, and U8 only, and only a subset of distance metrics - see the DISKANN section below.
For example, to define a vector index with 64-bit signed integers, you can use the following query:
DEFINE INDEX idx_hnsw_embedding
  ON Document FIELDS items.embedding HNSW DIMENSION 4 TYPE I64;
HNSW (Hierarchical Navigable Small World)
This method uses a graph-based approach to efficiently navigate and search in high-dimensional spaces. While it is an approximate technique, it offers a high-performance balance between speed and accuracy, making it ideal for very large datasets.
Keep in mind the in-memory nature of HNSW when considering system resource allocation.
In the example above, you may notice the EFC and M parameters. These are optional to your query but are parameters of the HNSW algorithm and can be used to tune the index for better performance.
M (Max Connections per Element): Defines the maximum number of bidirectional links (neighbors) per node in each layer of the graph, except for the lowest layer. This parameter controls the connectivity and overall structure of the network. Higher values of M generally improve search accuracy but increase memory usage and construction time.
EFC (EF construction): Stands for "exploration factor during construction." This parameter determines the size of the dynamic list for the nearest neighbor candidates during the graph construction phase. A larger efConstruction value leads to a more thorough construction, improving the quality and accuracy of the search but increasing construction time. The default value is 150.
M0 (Max Connections in the Lowest Layer): Similar to M, but specifically for the bottom layer (the base layer) of the graph. This layer contains the actual data points. M0 is often set to twice the value of M to enhance search performance and connectivity at the base layer, at the cost of increased memory usage.
LM (Multiplier for Level Generation): Used to determine the maximum level l for a new element during its insertion into the hierarchical structure. It is used in the formula l←⌊−ln(unif(0..1))⋅mL⌋, where unif(0..1) is a uniform random variable between 0 and 1. This parameter influences the distribution of elements across different levels, impacting the overall balance and efficiency of the search structure.
You can only provide TYPE, M, and EFC. SurrealDB automatically computes M0 and LM with the most appropriate value. If not specified, M AND EFC are set to 12 and 150, respectively. Refer to the Vector Search Cheat Sheet for the parameters allowed.
Memory cache usage for HNSW indexes
Available since: v3.0.0
HNSW vector search caches element vectors in a bounded memory cache, reducing memory spikes and improving stability under load. The cache is a single budget shared across every HNSW index in the process, not a per-index allowance. It defaults to 256 MiB and can be modified via the SURREAL_HNSW_CACHE_SIZE environment variable. The value is an integer number of bytes - for example, 268435456 for the 256 MiB default.
This budget covers the cached vectors only. As noted above, the HNSW graph itself is held in memory: it is loaded on first use and is not bounded by this setting, so it must be sized for separately. If the full graph will not fit in RAM, DISKANN below is the index designed for that case.
DISKANN (disk-based approximate nearest neighbours)
Available since: v3.1.0
DiskANN-style indexes provide on-disk approximate nearest-neighbour graphs. They are aimed at very large embedding sets where keeping the full graph in RAM (as with HNSW) is impractical: vectors and graph structure are persisted in the key-value store and paged through a bounded cache, trading some latency for a much larger working set.
DISKANN is available on 64-bit platforms and in WebAssembly builds, including the Wasm engine in a browser. Other 32-bit platforms, such as 32-bit x86 and 32-bit Arm, do not include DISKANN and use HNSW as their vector index.
Syntax and defaults
The clause mirrors HNSW: DISKANN DIMENSION … followed by optional TYPE, DIST, tuning knobs, and HASHED_VECTOR.
DEFINE INDEX diskann_pts
  ON pts FIELDS point DISKANN DIMENSION 4 DIST EUCLIDEAN TYPE F32;
-- Same index with defaults written out explicitly:
-- DEFINE INDEX diskann_pts ON pts FIELDS point DISKANN DIMENSION 4 DIST EUCLIDEAN TYPE F32 DEGREE 64 L_BUILD 100 ALPHA 1.2;| Clause | Default | Notes |
|---|---|---|
DIST | EUCLIDEAN | Only EUCLIDEAN, COSINE, INNER_PRODUCT, and COSINE_NORMALIZED are valid for DISKANN. |
TYPE | F32 | Must be one of F32, F16, I8, U8. COSINE_NORMALIZED further requires F32 or F16. From SurrealDB 4.0, I8 and U8 allow a DIMENSION of at most 33025. |
DEGREE | 64 | Target maximum graph degree (> 0). |
L_BUILD | 100 | Construction search-list size (> 0). |
ALPHA | 1.2 | DiskANN pruning parameter. |
HASHED_VECTOR | off | Same semantics as for HNSW - hash-stabilised vector - document keys. |
Queries use the same KNN operator shape as HNSW: <|K, EF|> (approximate) or <|K, DIST|> when the distance matches the index, letting the optimiser pick the DISKANN graph. The second number in the approximate form bounds the dynamic candidate list during search (analogous to HNSW EF).
Memory model and cache size
While HNSW's graph is held resident in memory, a DISKANN index is key-value-backed. The graph, its adjacency lists, and the full-precision element vectors are persisted in the key-value store (for example, on disk under SurrealKV) and remain the source of truth. Only a bounded in-memory cache holds the hot working set, while cold nodes and vectors are streamed from the key-value store on demand. A DISKANN index's resident memory is therefore bounded by the cache size rather than by the size of the dataset, which is what makes it suitable for larger-than-memory workloads.
Vectors are stored at full precision, and every distance a query reports is computed from the full vector. From SurrealDB 4.0, a DISKANN index of TYPE F32 or TYPE F16 also keeps an 8-bit code of each vector, which adds one byte per dimension to each vector. A search compares candidates using these codes, then ranks its nearest results from the full vectors. An index defined before 4.0 has the codes only after REBUILD INDEX, and setting the SURREAL_DISKANN_QUANTIZED_SEARCH environment variable to false makes a search compare full vectors throughout. Apart from the codes, the size of each vector depends only on the chosen TYPE (F32, F16, I8, or U8).
The cache is a single budget shared across every DISKANN index in the process. It defaults to 256 MiB and can be capped with the SURREAL_DISKANN_CACHE_SIZE environment variable, the DISKANN counterpart of SURREAL_HNSW_CACHE_SIZE. The value is an integer number of bytes - for example, 268435456 for the 256 MiB default.
Choosing HNSW or DISKANN
| Concern | Prefer HNSW | Prefer DISKANN |
|---|---|---|
| Working set size | Fits comfortably in memory with headroom for the HNSW cache | Much larger than RAM; cold data should stay on disk |
| Latency profile | Lowest latency when the graph is hot in cache | Extra I/O; better for throughput to cost on huge corpora |
| Vector element types | Full set (F64 … I16 in docs above) | Compact types (F32, F16, I8, U8) |
| Deployment target | Includes WASM | Server / native binaries only |
Brute Force method
The Brute Force method is suitable for tasks with smaller datasets or when the highest accuracy is required. Brute Force currently supports Euclidean, Cosine, Manhattan and Minkowski distance functions.
In the example below, the query searches for points closest to the vector [2,3,4,5] and uses vector functions to calculate the distance between two points, indicated by <|2,EUCLIDEAN|>.
Verifying index use in queries
The EXPLAIN clause shows the execution plan of a query, including whether it uses an index.
DEFINE INDEX userEmailIndex ON user FIELDS email UNIQUE;
CREATE user:test SET email = 'test@surrealdb.com';

SELECT * FROM user WHERE email = 'test@surrealdb.com' EXPLAIN FULL;
An IndexScan operator names the index the query planner used. With FULL, each operator also reports metrics, including how many rows it produced (output_rows).
{
	attributes: {
		projections: '*'
	},
	children: [
		{
			attributes: {
				access: "= 'test@surrealdb.com'",
				direction: 'Forward',
				index: 'userEmailIndex',
				predicate: "email = 'test@surrealdb.com'"
			},
			context: 'Db',
			metrics: {
				elapsed_ns: 2380999,
				output_batches: 1,
				output_rows: 1,
				records_fetched: 0
			},
			operator: 'IndexScan'
		}
	],
	context: 'Db',
	metrics: {
		elapsed_ns: 47083,
		output_batches: 1,
		output_rows: 1,
		records_fetched: 0
	},
	operator: 'SelectProject',
	total_rows: 1
}
Using the ANY/ALL operators for string indexes
Available since: v2.4.0
An index on a string field is used by = and by IN with an array of values. The containment operators CONTAINS, CONTAINSANY, ALLINSIDE and ANYINSIDE return the same records on such a field, but they scan the table, because they only use an index defined on the elements of an array field (such as tags.*), through a condition that takes each element (such as tags.* CONTAINS 'x'). CONTAINS on a string is a substring match.
DEFINE FIELD name ON account TYPE string;
DEFINE INDEX name_index ON account FIELDS name;

CREATE account:billy SET name = "Billy McConnell";

-- IN uses the index
EXPLAIN SELECT * FROM account WHERE name IN ["Billy McConnell"];
//- "SelectProject [ctx: Db] [projections: *]\n    IndexScan [ctx: Db] [index: name_index, access: = 'Billy McConnell', direction: Forward, predicate: name INSIDE ['Billy McConnell']]\n"

-- CONTAINSANY scans the table
EXPLAIN SELECT * FROM account WHERE name CONTAINSANY ["Billy McConnell"];
//- "SelectProject [ctx: Db] [projections: *]\n TableScan [ctx: Db] [table: account, direction: Forward, predicate: name CONTAINSANY ['Billy McConnell'], pre_decode_filter: yes]\n" In SurrealDB 2.4 and later 2.x releases, CONTAINSANY, ALLINSIDE and ANYINSIDE with the values in an array used an index on a string field, and CONTAINS did not. From 3.0.0, use = or IN to query a string index.
Rebuilding Indexes
Indexes can be rebuilt using the REBUILD statement. This can be useful when you want to update the index definition or when you want to rebuild the index to optimise performance.
You may want to rebuild an index over time to ensure that the index is up-to-date with the latest data in the table.
REBUILD INDEX userEmailIndex ON user; Using IF NOT EXISTS clause
The IF NOT EXISTS clause can be used to define an index only if it does not already exist. If an index with the same name already exists, the statement does nothing and returns NONE, even when the new definition is different. The existing index keeps its old definition. Without the clause, defining an index that already exists returns the error The index 'example' already exists.
An existing index is not built again, but a changed definition in the statement is never applied either. To change an index, use the OVERWRITE clause, or REMOVE INDEX followed by DEFINE INDEX. For a schema script that runs each time an application starts, OVERWRITE is usually the better choice from SurrealDB 4.0, because it applies a changed definition and keeps an unchanged index as it is.
-- Create a INDEX if it does not already exist
DEFINE INDEX IF NOT EXISTS example ON example FIELDS example;
Using OVERWRITE clause
The OVERWRITE clause can be used to define an index and overwrite an existing one if it already exists. You should use the OVERWRITE clause when you want to modify an existing index definition. If the index already exists, the DEFINE INDEX statement will overwrite the existing definition with the new one.
From SurrealDB 4.0, OVERWRITE builds the index again only when it needs to. When the table, the fields, and the index type with its parameters are the same as before, and the existing index is ready, the index and its data are kept and only the definition is replaced. A changed COMMENT is therefore applied without a rebuild, and a schema script that runs each time an application starts can use OVERWRITE for every index. The index is built again from the data in the table when the definition changes, when the existing index is still building or failed to build, or when it was built by an earlier release in an older index format.
An unchanged OVERWRITE does not tokenise the records again after an analyzer changes, because the index definition is the same. To build an unchanged index again, use REBUILD INDEX.
Before SurrealDB 4.0, OVERWRITE built the index again every time, even when the definition had not changed. On those versions, IF NOT EXISTS is the way to define an unchanged index without a rebuild.
-- Create an INDEX and overwrite if it already exists
DEFINE INDEX OVERWRITE example ON example FIELDS example;
Using CONCURRENTLY clause
Building indexes can be lengthy and may time out before they're completed. Without CONCURRENTLY, DEFINE INDEX blocks until the index is fully built (or the build fails). The CONCURRENTLY clause can be used when you need the statement to return immediately while indexing continues in the background. This allows other operations to keep running while the index builds, during which you can monitor progress with INFO FOR INDEX.
-- Create an INDEX concurrently
DEFINE INDEX test ON user FIELDS email CONCURRENTLY;
INFO FOR INDEX test ON user;
INFO FOR INDEX test ON user;
When building an index concurrently, SurrealDB starts the index creation as a background process. You can monitor the status of this process using the INFO FOR INDEX statement. The output includes a building block that provides several key details:
-- Check the indexing status
INFO FOR INDEX test ON user;-- Query
{
building: {
initial: 8143,
pending: 19,
status: 'indexing',
updated: 80
}
}The indexing process consists of two stages: initial and update.
Initial Stage:
During this stage, SurrealDB indexes all existing records. The number of indexed records is represented by the
initialproperty. While this stage is in progress, any new inserts, updates, or deletions are tracked aspending.Update Stage:
Once the initial stage is completed, SurrealDB begins indexing the pending records accumulated during the initial phase. At this point:
The
initialcount remains stable.The
pendingcount should gradually decrease as these records are processed; however, it may temporarily increase if new modifications occur during indexing.The
updatedproperty indicates the number of pending records that have been indexed during this stage.
When both stages are complete, the index status changes to ready, meaning that the index is now automatically updated within the same transaction that inserts, updates, or deletes records.
-- Query

{
	building: {
		status: 'ready'
	}
}
If the build fails, for example because a UNIQUE index finds two records with the same value, the index stays defined and INFO FOR INDEX shows status: 'error' with the reason. From SurrealDB 4.0, while a UNIQUE index is in this state, a write that adds a value to it is refused, because the index cannot check that the value is unique. Deletes, and writes that do not set the indexed fields, still succeed. To recover, remove the duplicate values and run REBUILD INDEX, or remove the index with REMOVE INDEX.
CREATE t:1 SET a = 1;
CREATE t:2 SET a = 1;
DEFINE INDEX ua ON t FIELDS a UNIQUE CONCURRENTLY;
-- Wait for the background build to fail
SLEEP 500ms;
CREATE t:3 SET a = 2;'Database index `ua` on table `t` failed to build, so it cannot enforce UNIQUE for this write: fix the duplicate values and run REBUILD INDEX, or REMOVE INDEX'Defining an index inside a transaction
A DEFINE INDEX without CONCURRENTLY builds the index in transactions of its own, which commit before the transaction that holds the statement. When the statement shares its transaction with other statements, such as inside BEGIN ... COMMIT, and the table already holds records, the rest of that transaction cannot read the entries the build wrote. From SurrealDB 4.0, the transaction handles the index as follows until it commits:
Queries in the transaction do not use the new index. A query on the indexed fields reads the table instead, so its result is correct. A full-text match fails with
There was no suitable index supporting the expression, and a nearest-neighbour search ranks the records of the table, as it does while a vector index builds.A
UNIQUEindex still checks the values the build indexed, so a duplicate of an existing value fails at the statement with the usual uniqueness error.A statement that deletes a record the build indexed, or changes one of its indexed fields, is refused and names the record and the index. A change to fields outside the index is allowed, and so is any change to a record that the transaction created after the definition.
CREATE product:1 SET sku = 'A-1';

BEGIN;
DEFINE INDEX sku ON product FIELDS sku UNIQUE;
UPDATE product:1 SET sku = 'A-2';
COMMIT;'Cannot change record `product:1`: index `sku` was defined by this transaction, and the build that ran for it wrote an entry for the record that this transaction cannot see. Define the index CONCURRENTLY, or commit the definition before changing the record.'As the error says, define the index with CONCURRENTLY, or commit the definition before the statements that change the records. A CONCURRENTLY build starts after the transaction closes, so none of these rules applies to it. An index defined over a table with no records has nothing to build, and the transaction reads and writes it as usual. If the transaction is cancelled or fails, the definition is removed with it.
The order matters in the other direction too. From SurrealDB 4.0, a DEFINE INDEX without CONCURRENTLY is refused when its transaction has already created, changed or deleted a record of the table, because the build cannot see those writes. The refusal comes before anything of the index is written, and the rest of the transaction fails with it:
BEGIN;
CREATE user:one SET email = 'one@example.com';
DEFINE INDEX email ON user FIELDS email UNIQUE;
COMMIT;'Cannot define index `email` on `user`: this transaction has written records of `user`, which a build without CONCURRENTLY cannot see. Define the index CONCURRENTLY, or commit those writes first.'The same applies to a block, a loop, a function and a transaction that a client holds open. Writes to other tables, reads of the table, a write that a rollback to a save point undid, and an IF NOT EXISTS definition of an index that already exists are not refused.
While such a transaction is open, other sessions on the same node cannot write the table without the risk that the build misses the write. From SurrealDB 4.0, a write by another session to a record of the table waits until the defining transaction ends. If that transaction commits, the waiting write fails with a retryable transaction conflict, and its retry sees the new index. If it rolls back, the write continues. A write that has waited for 60 seconds fails with the same retryable conflict. Reads, writes to other tables, and the defining transaction's own writes do not wait. The same applies to a DEFINE INDEX OVERWRITE that replaces an index, even as a statement of its own, because it builds inside its own transaction.
This wait is kept in the memory of the node that runs the definition. On a datastore that several nodes write, such as TiKV, a write through another node does not wait, and the index can miss it. On such a datastore, and on any table that other sessions write often, define the index as a statement of its own or with CONCURRENTLY, whose build starts only once the definition has committed.
The DEFER clause
Available since: v2.5.0
DEFER is available in SurrealDB 2.5 through 2.x only. On 3.x the clause is rejected at parse time, and this section applies to 2.x deployments. On 3.x, use CONCURRENTLY to build an index in the background - note that it addresses initial builds, not the ongoing write-path queueing DEFER provided.
Index updates in SurrealDB occur synchronously during document operations. This ensures immediate consistency, in which all reads return the most recent write. However, this can become a bottleneck during high-volume parallel ingestion, leading to write-write conflicts and increased latency, particularly with Full-Text or Vector indexes.
The DEFER clause can be used in this case if eventual consistency is acceptable, namely a setting in which reads may return stale data for a short period, but will eventually converge to the most recent write. An index with this clause will be enqueued in a persistent background queue so that ingestion and indexing are decoupled.
DEFINE ANALYZER simple TOKENIZERS blank,class FILTERS lowercase;
DEFINE INDEX title_index ON blog FIELDS title
	FULLTEXT ANALYZER simple BM25(1.2,0.75) HIGHLIGHTS DEFER;
Note: As unique indexes offer a guarantee that no records that contravene the index will ever exist, the UNIQUE clause cannot be used together with DEFER.
Performance Implications
When defining indexes, consider which fields are queried most frequently, and index those to optimise performance.
Indexes may improve the performance of SurrealQL statements. This may not be noticeable with small tables but it can be significant for large tables; especially when the indexed fields are used in the WHERE clause of a SELECT statement.
Indexes can also impact the performance of write operations (INSERT, UPDATE, DELETE) since the index needs to be updated accordingly. Therefore, the need for read performance has to be balanced against write performance.